"I don't have a GPU" is officially dead 🤯
You can now run 70B model on a single 4GB GPU and it even scales up to the colossal Llama 3.1 405B on just 8GB of VRAM.
AirLLM uses "Layer-wise Inference." Instead of loading the whole model, it loads, computes, and flushes one layer at a time
→ No quantization needed by default
→ Supports Llama, Qwen, and Mistral
→ Works on Linux, Windows, and macOS
100% Open Source.
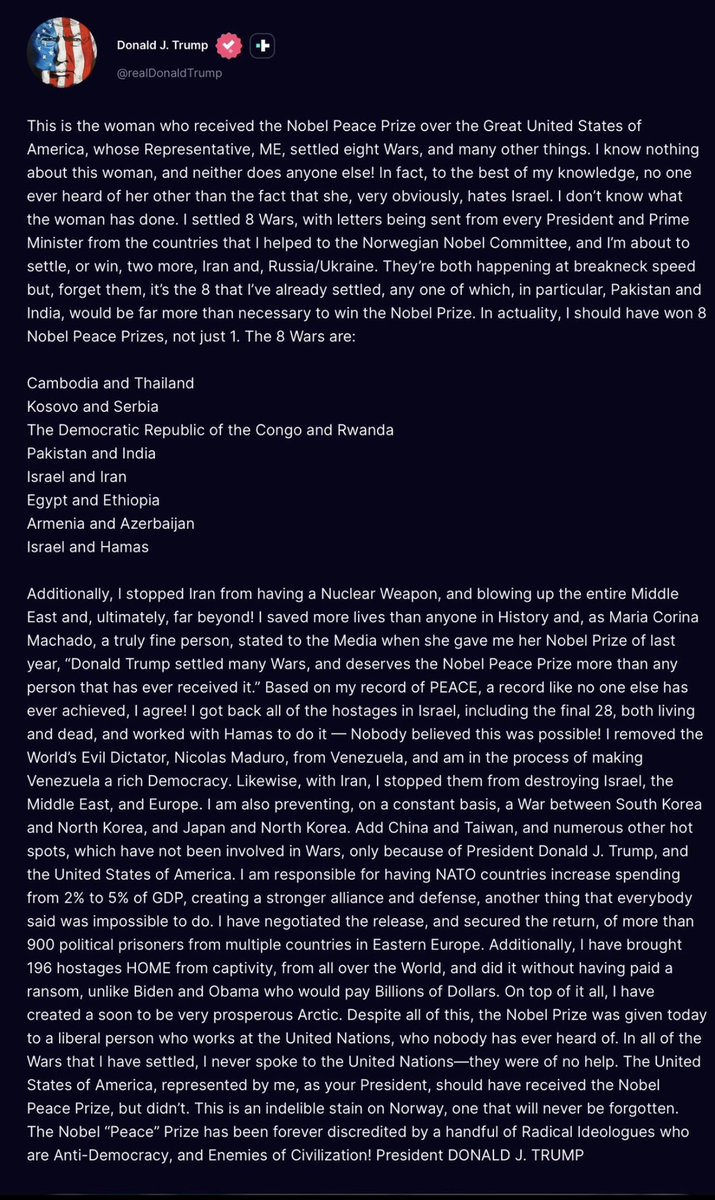
Donald Trump is insane.
This confirms it :
“This is the woman who received the Nobel Peace Prize over the Great United States of America, whose Representative, ME, settled eight Wars, and many other things. I know nothing about this woman, and neither does anyone else! In fact, to the best of my knowledge, no one ever heard of her other than the fact that she, very obviously, hates Israel. I don’t know what the woman has done. I settled 8 Wars, with letters being sent from every President and Prime Minister from the countries that I helped to the Norwegian Nobel Committee, and I’m about to settle, or win, two more, Iran and Russia/Ukraine. They’re both happening at breakneck speed but, forget them, it’s the 8 that I’ve already settled, any one of which, in particular, Pakistan and India, would be far more than necessary to win the Nobel Prize. In actuality, I should have won 8 Nobel Peace Prizes, not just 1. The 8 Wars are:
Cambodia and Thailand
Kosovo and Serbia
The Democratic Republic of the Congo and Rwanda
Pakistan and India
Israel and Iran
Egypt and Ethiopia
Armenia and Azerbaijan
Israel and Hamas
Additionally, I stopped Iran from having a Nuclear Weapon, and blowing up the entire Middle East and, ultimately, far beyond! I saved more lives than anyone in History and, as Maria Corina Machado, a truly fine person, stated to the Media when she gave me her Nobel Prize of last year, “Donald Trump settled many Wars, and deserves the Nobel Peace Prize more than any person that has ever received it.” Based on my record of PEACE, a record like no one else has ever achieved, I agree! I got back all of the hostages in Israel, including the final 28, both living and dead, and worked with Hamas to do it — Nobody believed this was possible! I removed the World’s Evil Dictator, Nicolas Maduro, from Venezuela, and am in the process of making Venezuela a rich Democracy. Likewise, with Iran, I stopped them from destroying Israel, the Middle East, and Europe. I am also preventing, on a constant basis, a War between South Korea and North Korea, and Japan and North Korea. Add China and Taiwan, and numerous other hot spots, which have not been involved in Wars, only because of President Donald J. Trump, and the United States of America. I am responsible for having NATO countries increase spending from 2% to 5% of GDP, creating a stronger alliance and defense, another thing that everybody said was impossible to do. I have negotiated the release, and secured the return, of more than 900 political prisoners from multiple countries in Eastern Europe. Additionally, I have brought 196 hostages HOME from captivity, from all over the World, and did it without having paid a ransom, unlike Biden and Obama who would pay Billions of Dollars. On top of it all, I have created a soon to be very prosperous Arctic. Despite all of this, the Nobel Prize was given today to a liberal person who works at the United Nations, who nobody has ever heard of. In all of the Wars that I have settled, I never spoke to the United Nations—they were of no help. The United States of America, represented by me, as your President, should have received the Nobel Peace Prize, but didn’t. This is an indelible stain on Norway, one that will never be forgotten. The Nobel "Peace" Prize has been forever discredited by a handful of Radical Ideologues who are Anti-Democracy, and Enemies of Civilization! President DONALD J. TRUMP”
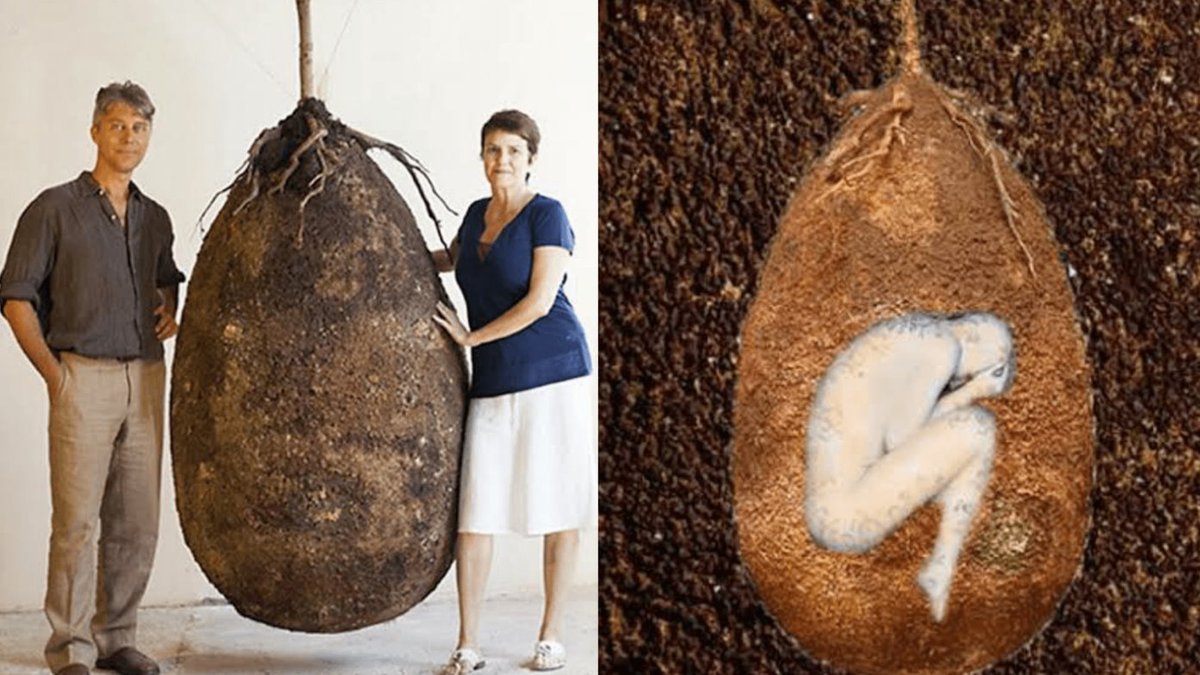
🚨: The biodegradable burial pod turns your body into a tree.
Once buried, the biodegradable plastic shell breaks down and the remains provide nutrients to a sapling planted right above it.
Therefore, everyone needs to make sure as soon as possible that their own content cannot, years from now, be claimed by AI companies as their own intellectual achievements.
Adding watermarks means that you’d better never preserve AI-generated content verbatim in your own text. By changing the wording and writing style, and altering word frequencies, you can turn it into your own property.
Constrained by the nature of training itself, AI cannot generate watermarks by restricting its thinking ability the relationships within vector space unless there is some kind of internal feedback mechanism similar to question and answer (and that would only work for long texts)
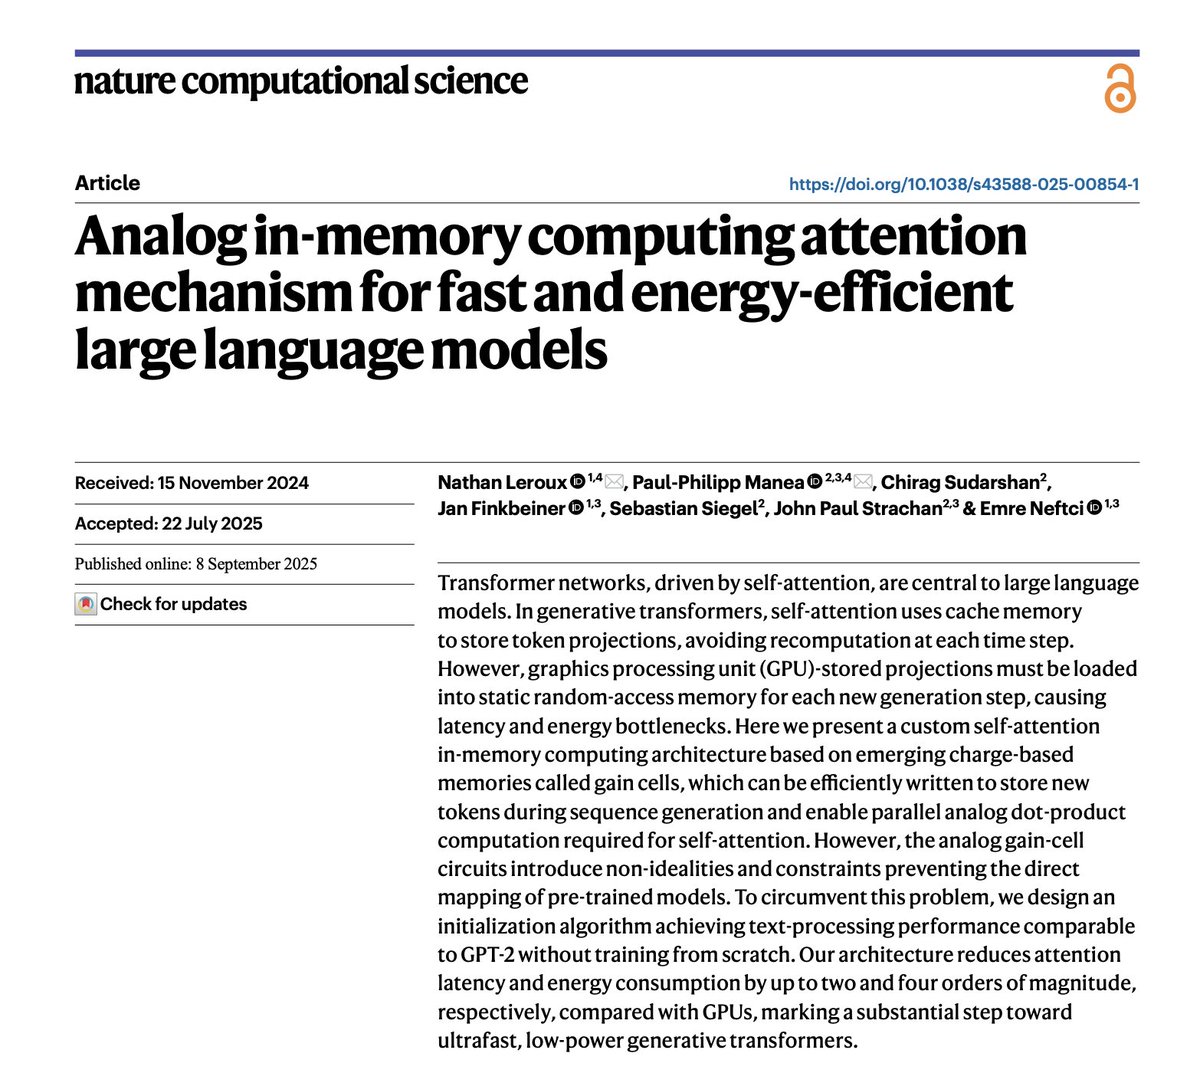
Researchers built an analog chip that runs LLM attention 100x faster than an H100 and uses 70,000x less power.
It's called GainCellAttention.
Every AI chip you use is built on an 80-year-old flaw called the von Neumann architecture.
the processor and the memory are physically separated.
To generate a single word, a GPU has to shuttle massive amounts of data back and forth across this divide. Over and over again.
Moving that data costs up to 10,000x more energy than actually doing the math.
But a team of researchers published a paper in Nature that completely destroys this bottleneck.
They built an analog in-memory computing architecture.
Instead of moving data from the memory to the processor, they put the processor inside the memory.
Using emerging hardware called "gain cells," the AI performs its most expensive calculation, the attention mechanism, directly inside the storage arrays.
The data never moves.
The compute happens exactly where the memory lives.
The result? A massive leap in energy efficiency and speed. It completely eliminates the latency of fetching data for every single token.
It is building AI chips that function exactly like the human brainwhere memory and computation are the exact same thing.
Nvidia researchers did it again!
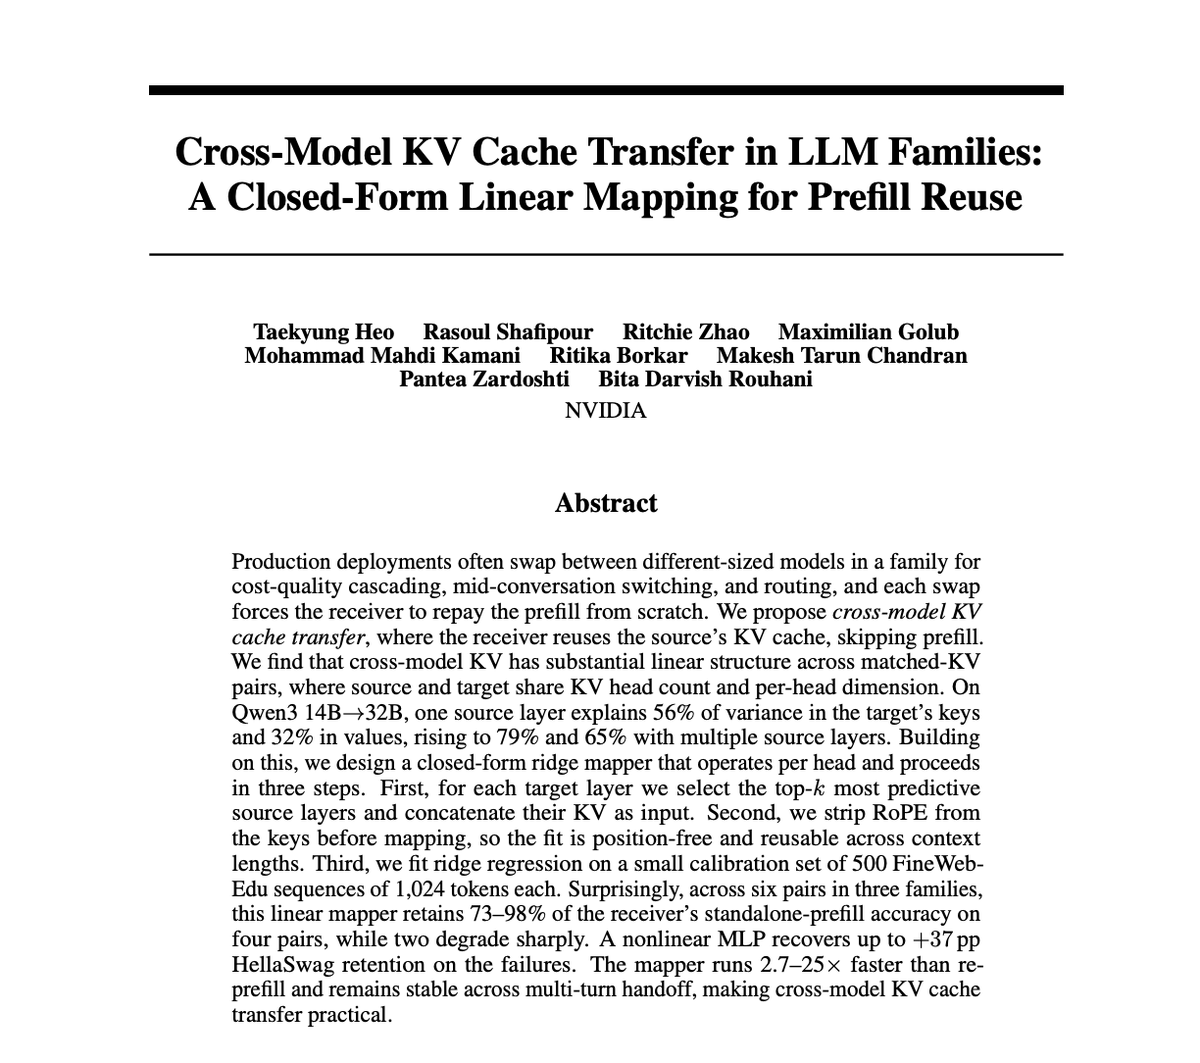
they found a way to transfer KV caches directly between different AI models.
if you run llms, you know the absolute pain of "prefilling". if you want to swap from a small, cheap model to a large, smart model mid-conversation, the big model has to recalculate the entire chat history from scratch. it kills your latency and your compute budget.
but a researchers just found a way to completely skip this..
they built a "closed-form linear mapping" that literally transfers the "memory" (kv cache) from a smaller model directly into a larger model.. without ever re-reading the prompt.
here is exactly why this is actual magic..
the discovery: they proved that kv caches across different sized models in the same family (like qwen3 14b to 32b) are linearly connected. a single layer in the small model can predict 56% of the variance in the big model's keys. if you bundle a few layers together, it jumps to 79%.
the rope trick: to make this work for any prompt length, they strip the "rope" (rotary positional embedding) off the keys before mapping them. they transfer the pure, position-free semantic data, and then re-apply the rotation on the target model.
the insane speed: this mathematical bridge transfers the context 2.7x to 25x faster than forcing the big model to re-prefill the text.
zero fine-tuning: there is no expensive training loop here. they just pass 500 texts (1,024 tokens each) through both models and solve a simple ridge regression equation per head. the calibration takes less than 90 minutes on an 8xh100 node.
the accuracy: across four out of six model pairs tested, this simple linear mapper retained 73-98% of the big model's native accuracy. for the two pairs that struggled, they use a nonlinear mlp fallback that recovers up to +37 points on hellaswag.
this means dynamic routing just got fully unlocked..
you can now use a cheap 8b model for the basic parts of a chat, and instantly hand off its exact brain state to a massive 70b model the second a user asks a complex coding question. zero latency penalty.
we are officially entering the era of fluid, cost-cascading ai architectures..
When several people talk at once, a transcript can get messy fast.
Our new Nemotron 3 Diarization model tracks who spoke when, even when voices overlap. It handles up to eight speakers, has 100M parameters, and is now available on @huggingface 🤗