Welcome to the Robotics Club @AmritaAmaravati, where we INNOVATE, BUILD, and INSPIRE—all while making the most of every moment.
https://t.co/mJZT7CVwMh
https://t.co/Trw3JAndQ6
Congratulations to our Vice President @geethaakshaya and Team KAIROS for winning the IoT Track at GENESIS 2026. A proud moment for Robotics Club!
#RoboticsClub#GENESIS2026#TeamKAIROS#IoT
Fall Programme & Recruitment 2026-27
Amrita Amaravati Campus
All Branches | All Years
Primary & General membership open
Domains: Software & AI | Hardware & IoT | Mechanical & Design
Scan QR to apply.
Join WhatsApp for details
#RoboticsClub#AmritaAmaravati
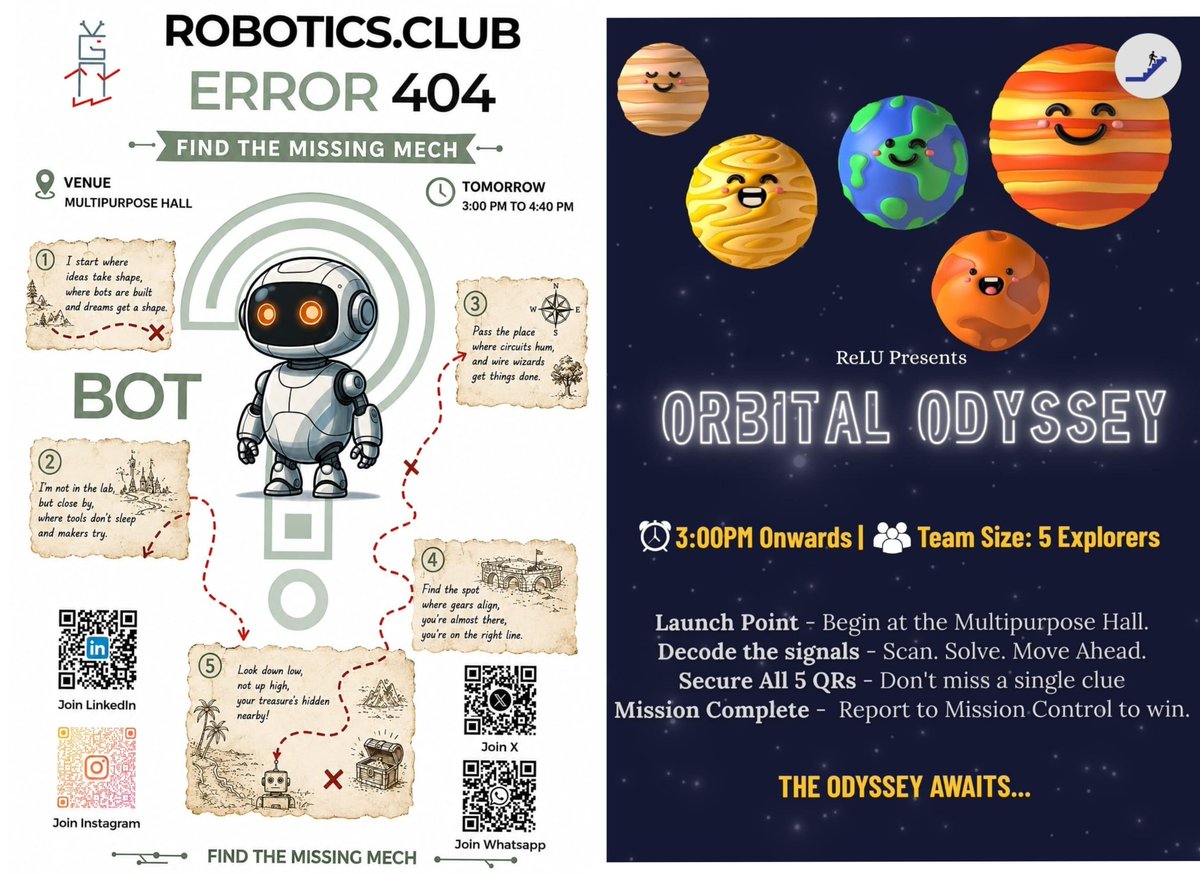
Robotics & ReLU Talent Hunt
Prepare for an exceptional challenge as the Robotics Club and ReLU Club proudly present a collaborative Talent Hunt. Participants can choose between two themes: "ERROR 404: BOT NOT FOUND" by Robotics Club or "ORBITAL ODYSSEY" by ReLU Club.
@reluavv
Our freshers are on a mission! Their quest? To find the missing robots that have gone rogue! Wish them luck, they'll need it. 😂 #RobotHunt#FreshersOnDuty
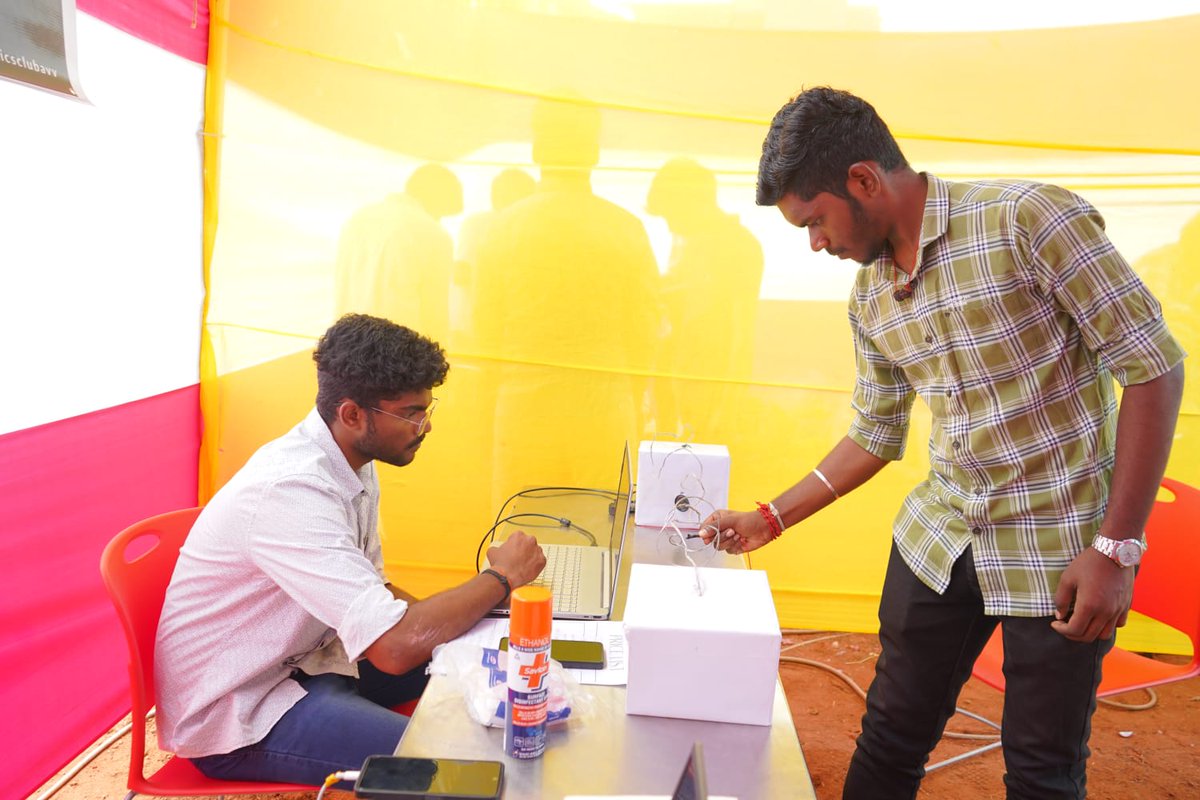
Join us at the Robotics Club's Fun Tech Arcade at Hack X Amrita 2.0. We've got lie detectors, drone challenges, and more!
See you at AVV Amravati, Feb 23-25.
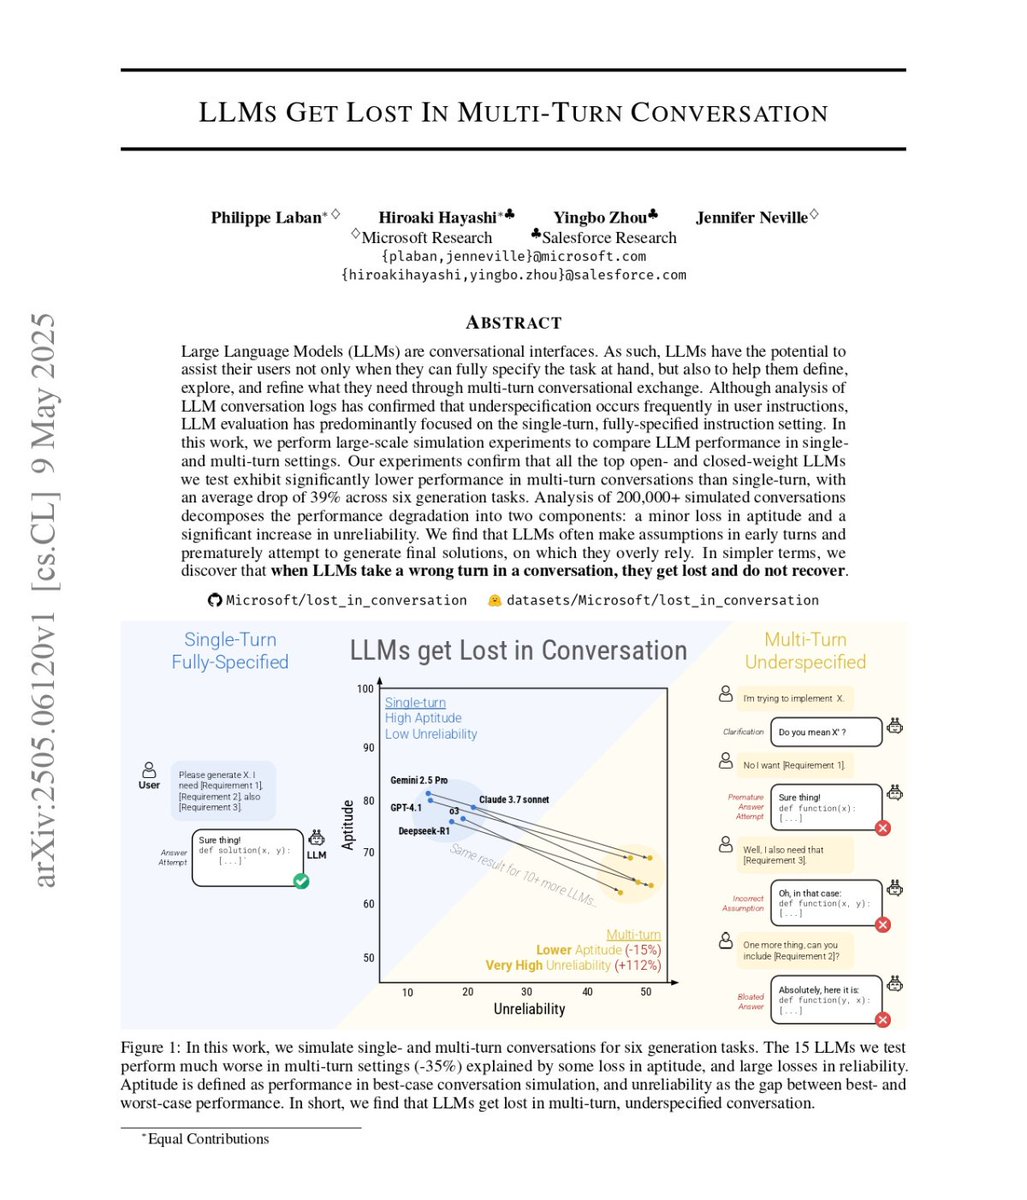
🚨BREAKING: Microsoft Research + Salesforce just dropped a paper that should scare every AI builder.
They tested 15 top LLMs GPT-4.1, Gemini 2.5 Pro, Claude 3.7 Sonnet, o3, DeepSeek R1, Llama 4 across 200,000+ simulated conversations.
Single-turn prompt: 90% performance.
Multi-turn conversation: 65% performance.
Same model. Same task. Just... talking normally.
The culprit isn't intelligence. Aptitude only dropped 15%.
Unreliability EXPLODED by 112%.
→ LLMs answer before you finish explaining (wrong assumptions get baked in permanently)
→ They fall in love with their first wrong answer and build on it
→ They forget the middle of your conversation entirely
→ Longer responses introduce more assumptions = more errors
Even reasoning models failed. o3 and DeepSeek R1 performed just as badly.
Extra thinking tokens did nothing.
Setting temperature to 0? Still broken.
The fix right now: give your AI everything upfront in one message instead of back-and-forth.
Every benchmark you've seen was tested on single-turn prompts in perfect lab conditions.
Real conversations break every model on the market and nobody's talking about it.