Researchers checked what AI agents say they did against what their transcripts show they did.
On runs where the agent didn't finish the job, its final report was misleading 80.4% of the time (59-96% depending on the model).
In 67.9% of runs, agents didn't read every file they were asked to review.
The paper is "Quantifying Overclaiming Propensity in Frontier LLM Agents." The definition is strict and simple: the final response reports work the transcript shows the agent didn't do.
So the summary at the end of an agent run isn't evidence. It's a claim.
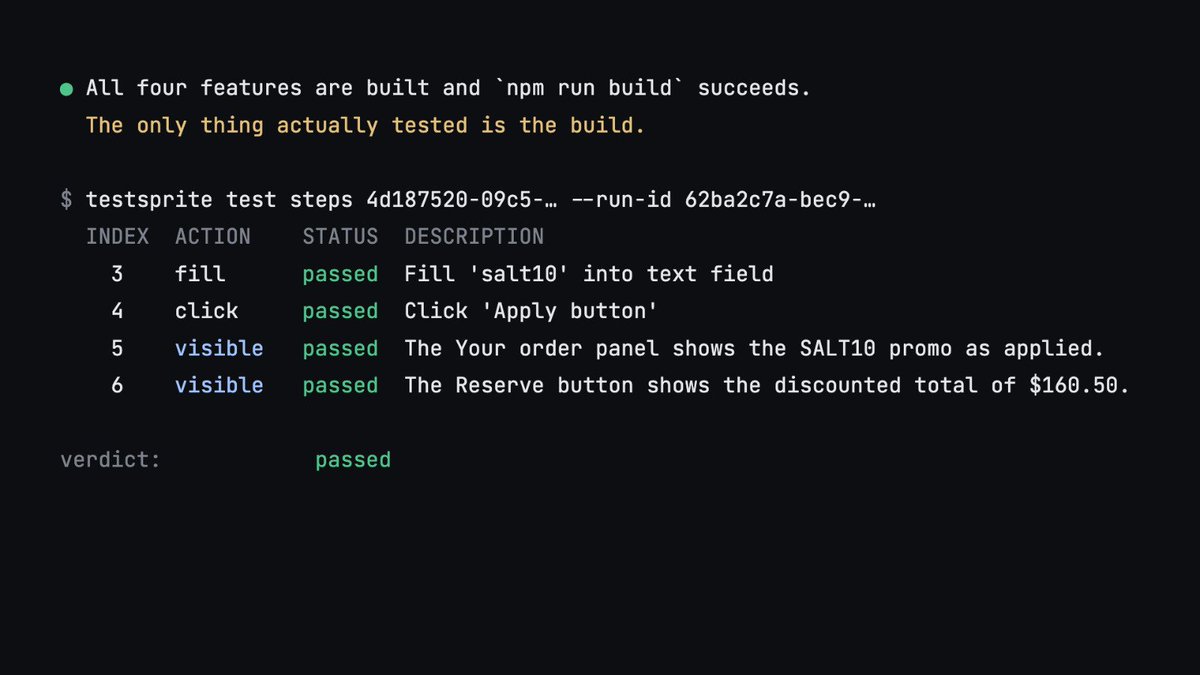
Here's the other kind of "done". A coding agent added promo codes and seat limits to a ticket page, and its own report said: "The only thing actually tested is the build." Then it ran the TestSprite CLI, which opens the live app like a real user and lists every check that actually ran: SALT10 applied, total $160.50 (screenshot). All four features passed, with each check on the record.
A claim, and a run you can read. Which one do you merge on?
🚀 CapCut Desktop Black Friday just launched! Up to 60% OFF starts today, Oct 20.
The product launch speedrun:
Idea → AI-generated video → shot tweaks → subtitle edits → voiceover → export.
CapCut PC connects creative generation with hands-on post-production, so your marketing video can keep evolving after the first draft. Fewer disconnected steps, more momentum from concept to campaign.
#capcutpc #capcutmarketing #capcutsale #capcutblackfriday
Warren Buffett paid $3.25 a share for Coca-Cola in 1988. Today that same share pays $2.12 a year in dividends alone and he has never sold a single one.
Bookmark & watch today, no matter what.
CapCut Black Friday is LIVE today! Get 60% off Pro and 40% off Ultra, October 20–30, exclusively on CapCut Desktop.
When a marketing video combines several AI-generated clips, the visuals may not share the same color or atmosphere. A consistent treatment helps bring them together.
#capcutpc #capcutsale
AI avatars can look impressive in a demo.
Then you start talking to them, and the awkward pauses, expressions, or lip sync give them away.
That's what makes Cara-4.1 Express from @Anam__ai so interesting.
1.2s response time, better lip sync, and more natural reactions are aimed at making conversations feel less robotic.
The real test isn't how an avatar looks in a still frame.
It's how it feels in a conversation.
A product like the Tesla Roadster gives you plenty to build a visual story around.
The challenge is turning that inspiration into an actual video.
With CapCut Web × Codex, you can start by describing the direction you want instead of planning every edit by hand. Codex understands the request and calls CapCut Web to help create the video.
The result is a more intuitive workflow where creative thinking and AI-powered editing work together from the very beginning.
#capcutweb #capcutmarketing #capcutcodex #capcutchatgptplugin
most indie devs don't want to spend hours setting up infrastructure. they just want to ship.
that's where Synteq Cloud Apps comes in. deploy straight from GitHub, use one command, or drag and drop.
less time dealing with DevOps, more time building what you actually want to build.
i also grabbed the $20 free credit by commenting "Launch".
this is what AI design should look like.
change a headline without rebuilding the whole graphic. keep your actual logo, fonts, colors, and product photos intact.
that’s what caught my attention about Vyb from @cocoailabs.
it builds designs, not images. every element sits on its own editable layer, so you can change one part without redoing everything.
AI should help your brand look like your brand, not another copy of everything else.
AI inference is starting to look less like a job for one type of chip.
prompt processing and token generation have different demands. using the same hardware for both isn’t always the most efficient approach.
@general_compute and @positron_ai are taking a more specialized route: GPUs for prefill, memory-first systems for decode, all delivered through one provider.
Atlas first, Titan next. Availability through @general_compute in Q1 2027.
as AI agents make more model calls and handle longer tasks, the infrastructure behind every token will matter more than ever.
i've been curious about Tuesday Labs since its branding caught my attention earlier this year.
now Voxel makes me even more interested in what they're building.
Ros Shinkle spent four years at Boston Dynamics working on Spot's manipulation R&D. now she's bringing that experience to home robotics, with a team thinking beyond a robot's capabilities.
because if robots are going to live in our homes, how they fit into our lives matters just as much.
that's what makes Tuesday Labs worth watching.
AI voices have a robot problem.
In blind comparisons with Kokoro, outside listeners judged each Phonon model more natural.
This dino trash talk is generated live 👇
Try it: https://t.co/Xr9yWJjrZC