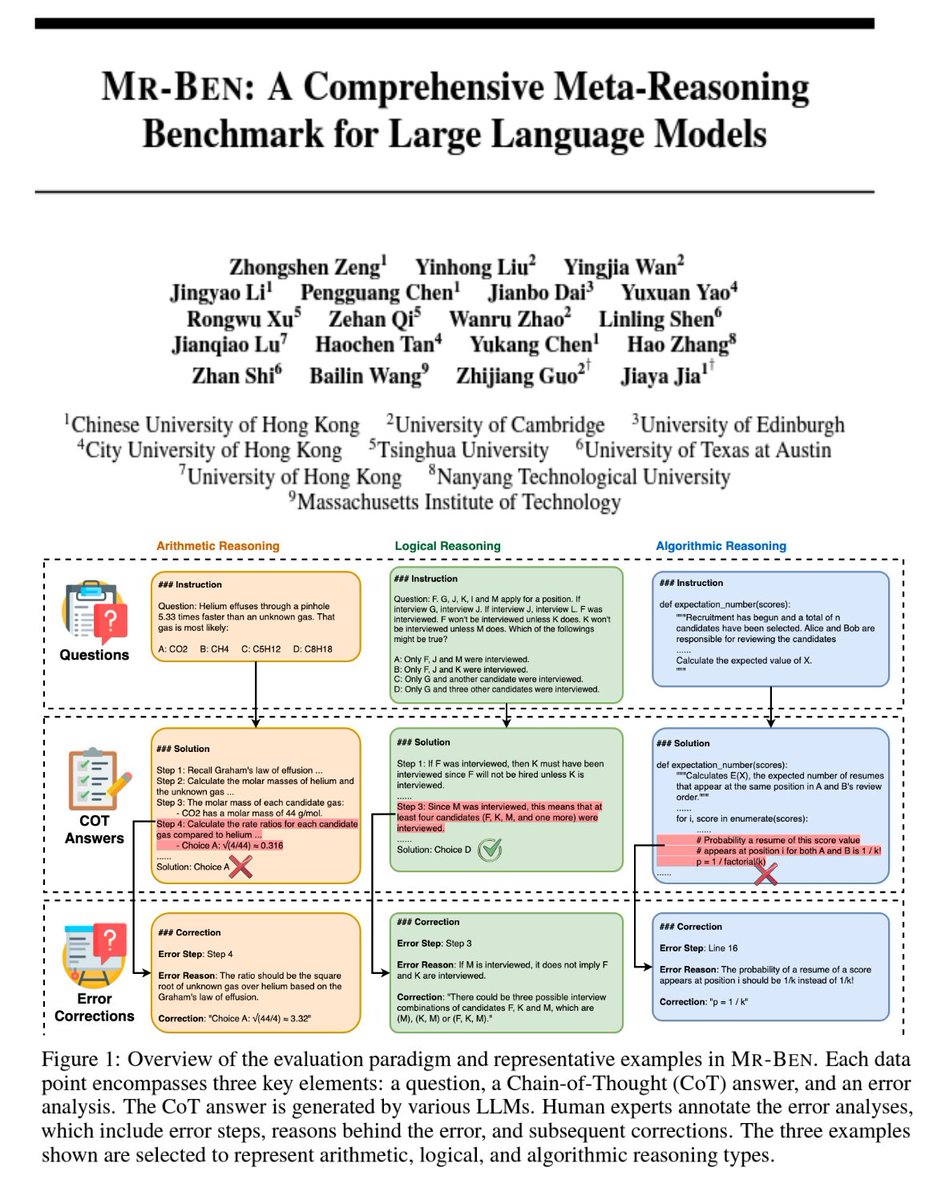
Check out our new reasoning benchmark !!🚀
Is LLM really reasoning or just parroting🦜 ? Why not test if LLM can judge the correctness of different reasoning paths🧠? We cover diverse subjects and reasoning paradigms from logic, coding, maths and more 🔥
📄https://t.co/QBICp3gKeo
What if a dexterous robot could learn a 20+ step chemistry experiment without a single on-robot training demo?
Meet TwinDEX: a pair of co-designed, three-finger, nine-DoF dexterous manipulation interface: one wearable for data collection, one for robot deployment.
The twinned design shares identical kinematics, contact surfaces, visual appearance, and sensors across collection and deployment — keeping observations and actions aligned end to end.
Trained from scratch on only a few hundred wearable demonstrations - with zero on-robot training or intervention data - TwinDEX completed a standardized chemistry experiment involving tool switches, fine force control, and bimanual coordination.
Robot-free data showed comparable learning efficiency on the multi-task evaluation, TwinDEX delivered 5.3 times effective throughput than on-robot teleoperation.
TwinDEX demonstrates that high-quality robot-free data can fully substitute for on-robot teleoperation data on challenging dexterous tasks — removing the dependency on real-robot hardware that has been the central bottleneck to scaling dexterous manipulation data.
This was the proof-it phase. Now comes scale: what emerges at tens of thousands, or millions, of episodes?
Watch the demo and read the technical blog: https://t.co/PgyFkrJdXG
#TwinDEX #Robotics #EmbodiedAI #DexterousManipulation
Is your model faithfully translating math into formal languages like Lean?
⚖ Introducing "FormalAlign"! #ICLR2025
⁉️To address the lack of scalable evaluation in autoformalization, we propose the FIRST method to evaluate semantic alignment between informal and formal languages.
🚀Exciting to see how recent advancements like OpenAI’s O1/O3 & DeepSeek’s R1 are pushing the boundaries!
Check out our latest survey on Complex Reasoning with LLMs. Analyzed over 300 papers to explore the progress.
Paper: https://t.co/k1HGQTA2kN
Github: https://t.co/VpcNVcEBSg
🚨 New Paper Alert! 🚨
When using LLMs for judgements, ever wondered about the consistency of those judgments? 🤔
Check out our latest work, where we quantify, evaluate, and enhance the logical/preference consistency of LLMs. 📚
🔗 Read more: https://t.co/QqqUuPHQRX
🎥 Frustrated by Sora's credit limits? Still waiting for Veo 2?
🚀 Open-source video DiTs are actually on par. We introduce FastVideo, an open-source stack to support fast video generation for SoTA open models. We have supported Mochi and Hunyuan, 8x faster inference, 720P 5-second video in 62 seconds.
I'll be presenting two co-authored posters in LLM reasoning and evaluation at #NeurIPS2024 (links & info in thread).
I am also looking for PhD opportunities 2025 Fall!🙌 DM or email me to have a chat (see bio), or come meet me at the posters. So excited to connect!
💥 Introducing "AutoPSV: Automated Process Supervised Verifier" - accepted at #NeurIPS2024!
AutoPSV automatically annotates reasoning steps via confidence tracking, making it efficient and effective even without ground-truth answers.
🔗 https://t.co/a7owZN53yp
🧵1/5
🔥Conformity in Large Language Models🔥
Our latest paper dives into how LLMs align their answers with incorrect majorities. We explore the fascinating interplay between LLM behavior and human psychology!🧠
Preprint:
https://t.co/JbuJUkdYmr
#AI#NLP#LLMs#Conformity
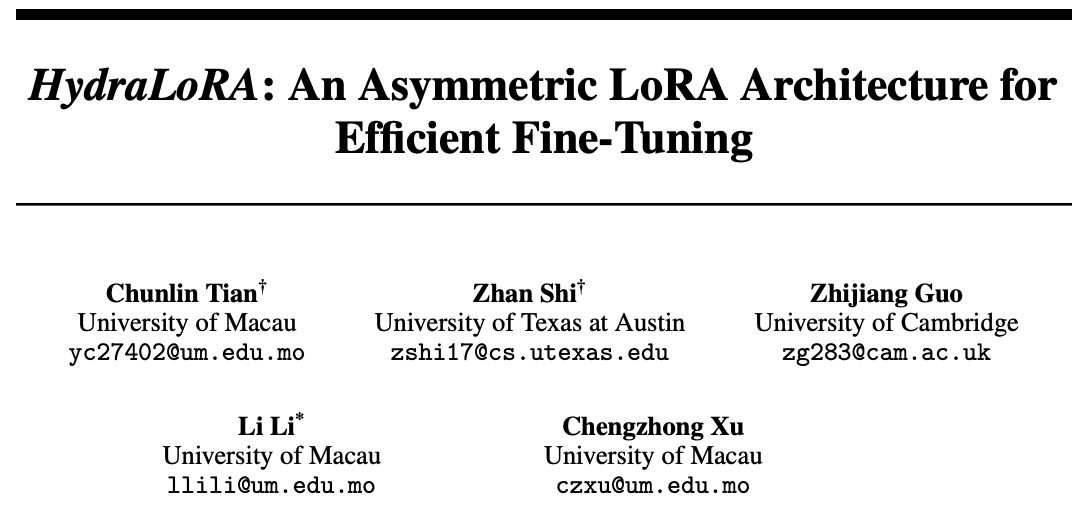
🔥Thrilled to announce our Oral acceptance at #NeurIPS2024! 🚀HydraLoRA, an asymmetric LoRA architecture with a shared A matrix for common knowledge and multiple B matrices for specialized adaptations, enhancing model performance while maximizing efficiency with a reduced param.
🚀Kindly checkout our project page at https://t.co/ZeaaidCAMf , we have provided an integrated evaluation script for you to eval your models in a single command ! 🫡 n/n🧵
🚀We’re officially accepted at NeurIPS 2024! Introducing MR.BEN—a groundbreaking framework designed to evaluate the reasoning processes of LLMs, not just their final answers. This aligns perfectly with the innovative spirit of OpenAI's o1 model. Dive into the details below! 1/n🧵
MR.BEN is an invaluable tool for researchers and developers aiming to elevate LLM reasoning. By pinpointing and addressing these limitations, we can build more capable and reliable AI systems. We’re currently evaluating the o1 family on MR.BEN—stay tuned for more updates! 5/n 🧵
Our metrics reveal striking disparities between open-source and closed-source models, shedding light on current LLM reasoning limitations. While they may seem comparable on traditional benchmarks, MR.BEN uncovers critical reasoning deficiencies. 4/n 🧵
As LLMs evolve💪, traditional benchmarks like MMLU, LogiQA and GSM8K have become saturated and lack differentiation🤔. In contrast, by applying our student-to-teacher transformation on top of these benchmarks to construct MR.BEN, even top models like GPT-4o score below 50%! 3/n🧵
MR.BEN assesses slow thinking by requiring LLMs to score solutions rather than answering questions. It prompts LLMs to reflect on assumptions and logic 🤖, check for errors, and even consider counterfactual scenarios. This makes MR.BEN ideal for measuring slow thinking! 2/n 🧵
🌟Excited to share LeCo's acceptance at #COLM2024!
🤔Fed up with LLMs' self-correct struggles and endless prompts?
🪄LeCo uses logits for confidence scores, skipping tedious prompts and rethinking from the last correct step.
📖:https://t.co/RMh6f1qKEe
💻:https://t.co/EollTSJBZq
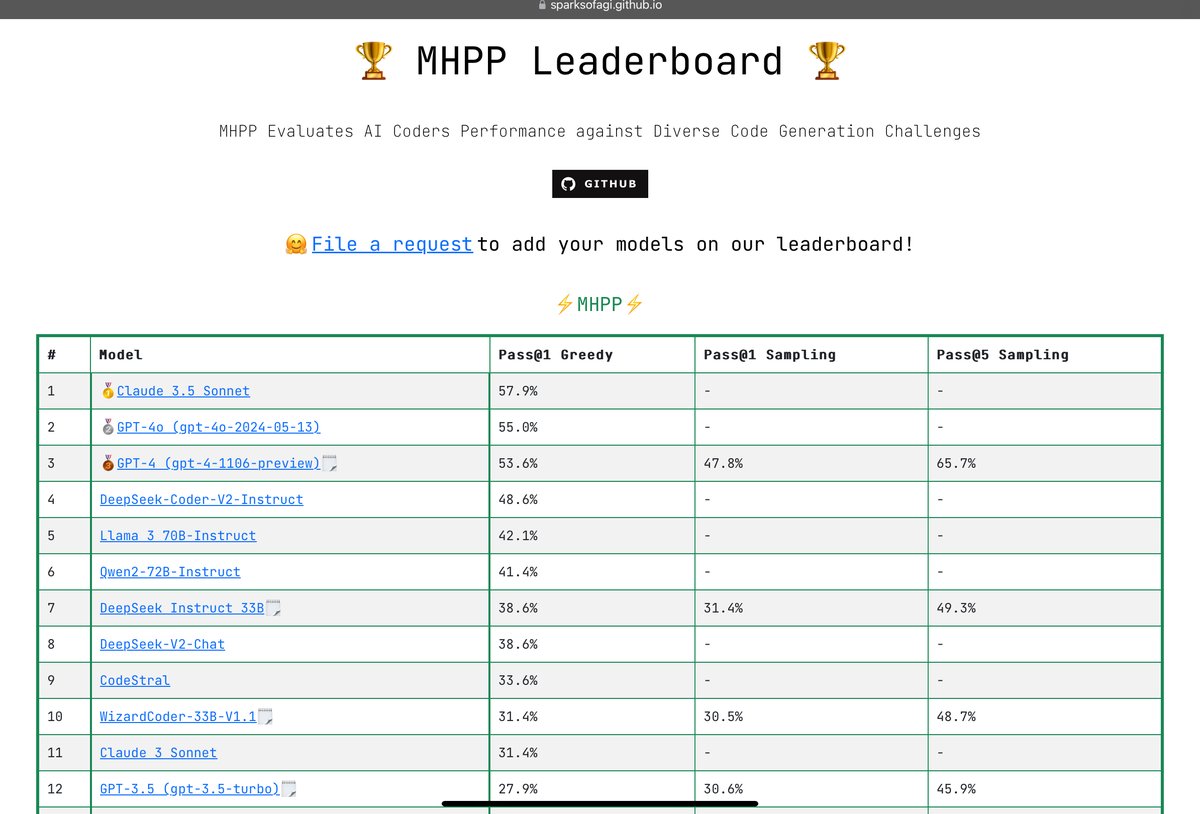
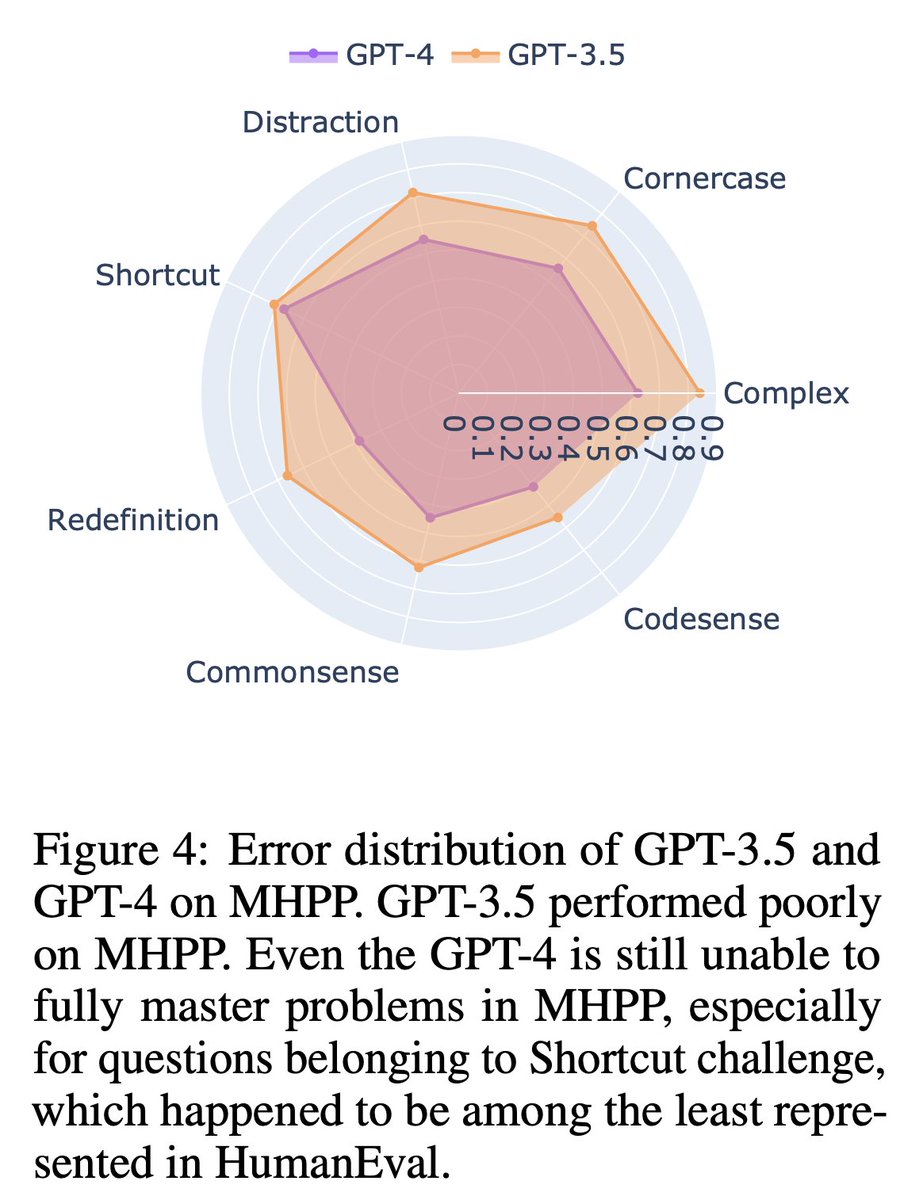
🥳Congrats on our paper's REJECTION from @COLM_conf with a score of 776! This work reveals the capabilities of many Code LLMs, while benchmarks like HE are overstudied and contaminated. Fascinating results: Claude 3.5 Sonnet outperformed all GPT models. A new champion is crowned!
@liyucheng_2 thanks for the kind comment! We tried our best to control the quality and did several rounds of inspection. However there might still be some unavoidable errors due to disambiguation/annotator quality etc. Let us know how the benchmark works out for you : )
Check out our new reasoning benchmark !!🚀
Is LLM really reasoning or just parroting🦜 ? Why not test if LLM can judge the correctness of different reasoning paths🧠? We cover diverse subjects and reasoning paradigms from logic, coding, maths and more 🔥
📄https://t.co/QBICp3gKeo
Why aligned LLMs are so vulnerable to adversarial attacks?
Our work attributes this vulnerability to reward misspecification during the alignment process. By exploiting this loophole, we find fundamentally misaligned prompts, leading to more effective automated red teaming. 🧵
🧵n/n
Following are the links to our work 🔥🔥
📃 Arxiv page: https://t.co/QBICp3hi3W
🖥️project page: https://t.co/ZeaaidCAMf
👨💻github repo: https://t.co/1C6a0fGdvz
🤗HF Dataset: https://t.co/PFoy46F3LX