We advance state-of-the-art #AI techniques paving the path for innovative products at @Salesforce. Focus areas: #AIAgents, #EnterpriseAI, #EGI, and #TrustedAI.
Looking for the cutting-edge of AI research? Follow Salesforce AI Research to see how we're transforming enterprise technology through advanced innovations. From world models to agentic systems, discover the future of AI before it hits the market.
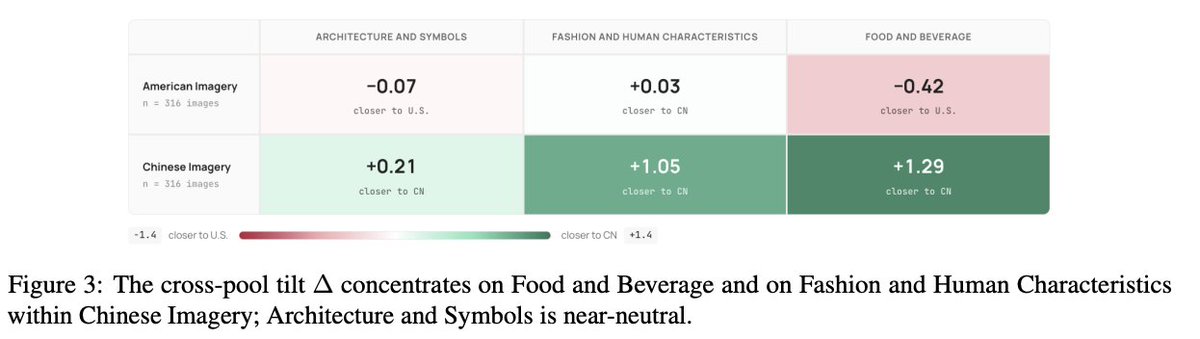
⚖️ Jury Duty: Calibration and Orientation Failures in MLLM-as-a-Judge Under Cultural Ambiguity: https://t.co/iYleB4mlas
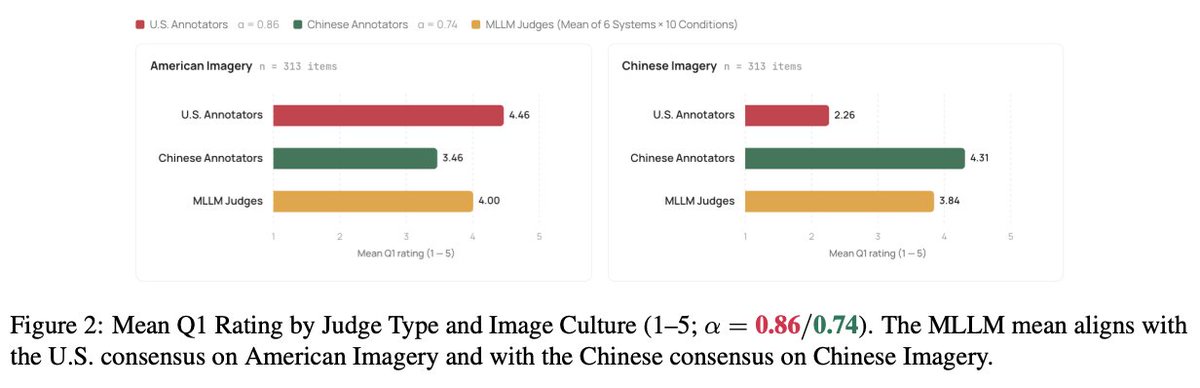
AI judges score the outputs that become training signal and leaderboard rankings. We tested whose judgment they reflect when cultures disagree.
→ VOIR DIRE: 626 paired U.S. and mainland Chinese image items across food, fashion, and architecture
→ Six MLLM judges rarely use the low end of the scale, which tilts contested items toward one cultural reading
→ Persona prompts only partly correct the tilt, and in-context examples deepen it
Our recommendation: report alignment against each reference pool separately.
#FutureOfAI #EnterpriseAI #EMNLP2026
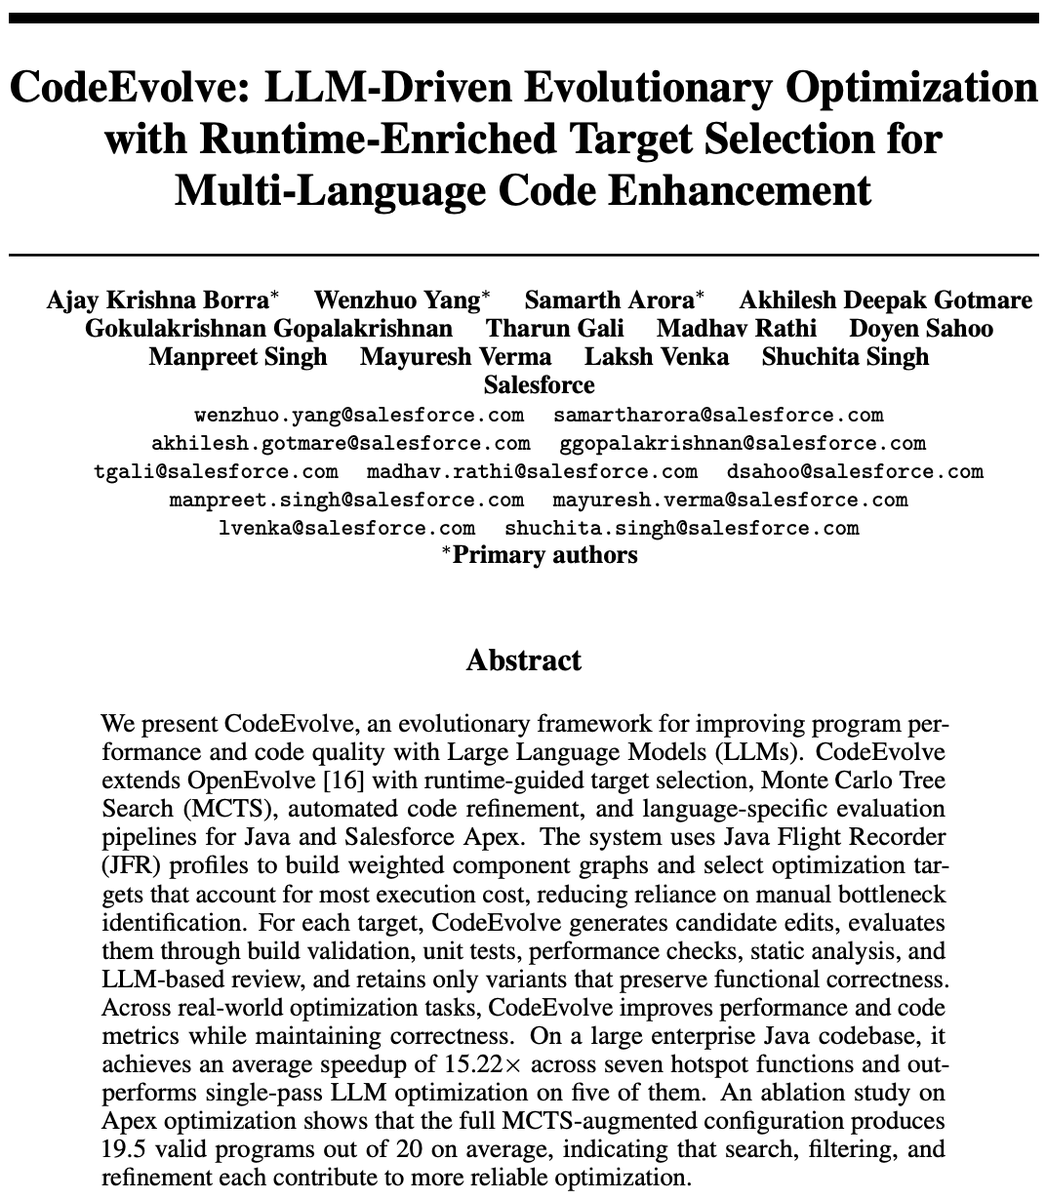
𝗖𝗼𝗱𝗲𝗘𝘃𝗼𝗹𝘃𝗲: LLM-Driven Evolutionary Optimization with Runtime-Enriched Target Selection for Multi-Language Code Enhancement
https://t.co/t2iNDsreuy
LLM code edits only help if they preserve behavior. CodeEvolve runs every candidate through builds, unit tests, performance checks, static analysis, and LLM review, and only validated variants enter the search population.
→ 19.5 of 20 Apex programs pass all tests on average with the full MCTS-augmented system, up from 7.9 for the OpenEvolve baseline
→ Variance in valid programs drops from ±4.16 to ±0.93
→ 15.22× average speedup across 7 production Java hotspot functions, with correctness intact
Authors: Ajay Krishna Borra, Wenzhuo Yang, Samarth Arora, Akhilesh Deepak Gotmare @akhilesh_gotmare, Gokulakrishnan Gopalakrishnan, Tharun Gali, Madhav Rathi, Doyen Sahoo @doyensahoo, Manpreet Singh, Mayuresh Verma, Laksh Venka, Shuchita Singh
#FutureOfAI #EnterpriseAI #SoftwareEngineering
Redesigning and auditing deep research writing for faithful reports: https://t.co/kZXAiqs78z
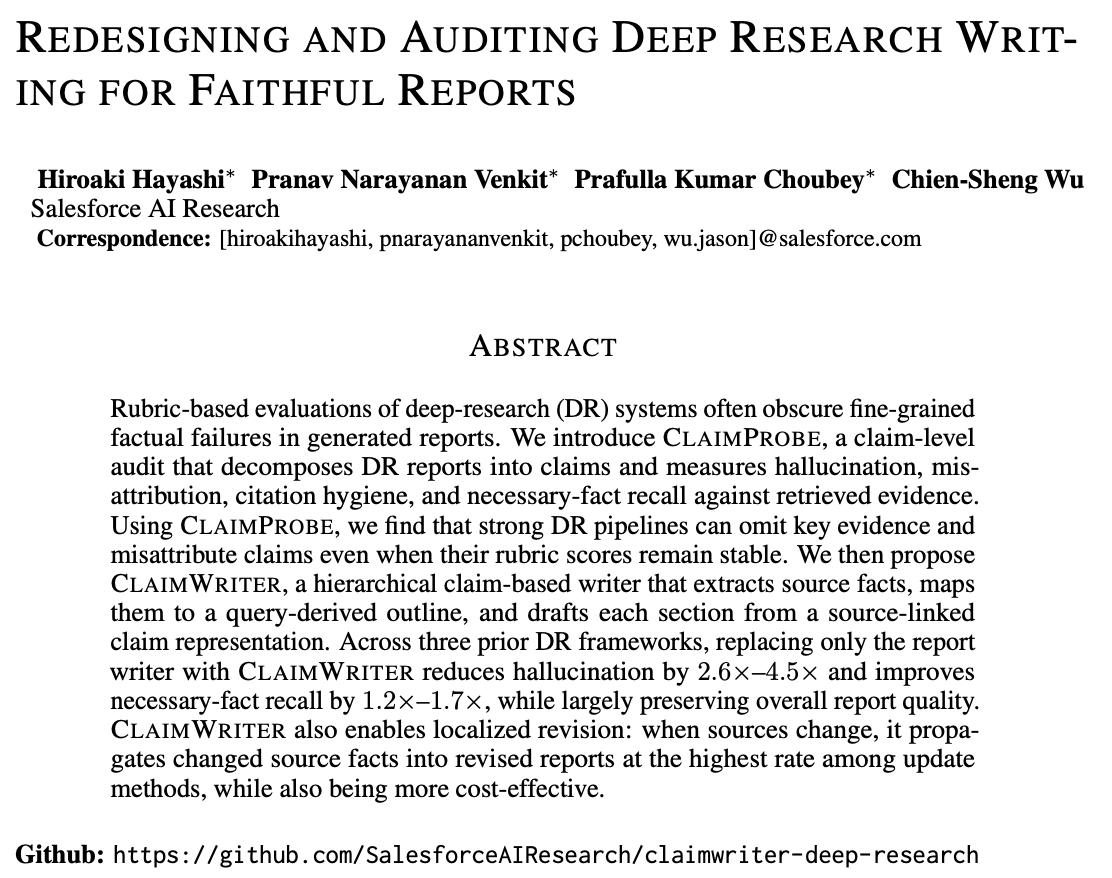
Deep research agents can write fluent, well-scored reports that still miss key facts, cite the wrong sources, or make claims no source supports.
ClaimWriter changes how the report gets written. It extracts facts from sources, maps them to an outline built from the user's query, and drafts each section from source-linked claims.
We swapped only the report writer into three deep research frameworks (Enterprise Deep Research, NVIDIA AI-Q, and Open Deep Research), keeping search and evidence collection fixed:
→ 2.6–4.5× less hallucination
→ 1.2–1.7× better recall of necessary facts
→ Overall report quality largely preserved
To measure the difference, we built ClaimProbe, a claim-level audit that checks each report claim against the retrieved evidence.
Code and benchmark: https://t.co/kF5EFZ8FQq
#FutureOfAI #EnterpriseAI
Moirai 2.0, our time-series foundation model, now powers zero-shot forecasting in Data 360. Teams can forecast pipeline, service volume, demand, and consumption on trusted enterprise data, with no custom model to build.
Article: https://t.co/5zFklTihDx
From research to product:
🔬 Pretrained on millions of diverse time series to learn seasonality, trends, and sudden shifts
⚡ Forecasts start in minutes, not weeks of model selection and tuning
📊 Built into Data 360 Transforms, Tableau Next, and D360 SQL
Next up: Moirai inside agents that reason over time-series data, explain root causes, and recommend actions.
📄 Papers: arXiv 2402.02592 (Moirai) and 2511.11698 (Moirai 2.0)
✍️ Avni Wadha
#TimeSeries #FoundationModels #Forecasting #AIResearch
EvoHarnessBench: Can Your Agents Keep Pace with an Evolving Harness? https://t.co/LQUhfKpAQB
Agents work through a harness of tools, skills, and specialist agents that keeps expanding as new capabilities arrive. EvoHarnessBench tests what happens as that harness grows, stage by stage, across 17 streams and 802 tasks.
A recurring pattern: the methods that best preserve earlier competence often struggle to use newly introduced capabilities, and vice versa. Aggregate scores can hide this, so we measure retention and adaptation separately.
Our results point to bi-level adaptation: inner updates from current experience, plus an outer check on whether those updates still hold once the harness moves again, including spotting when stored artifacts have gone stale.
Try the live demo or bring your own agent.
#AgenticAI #EnterpriseAI
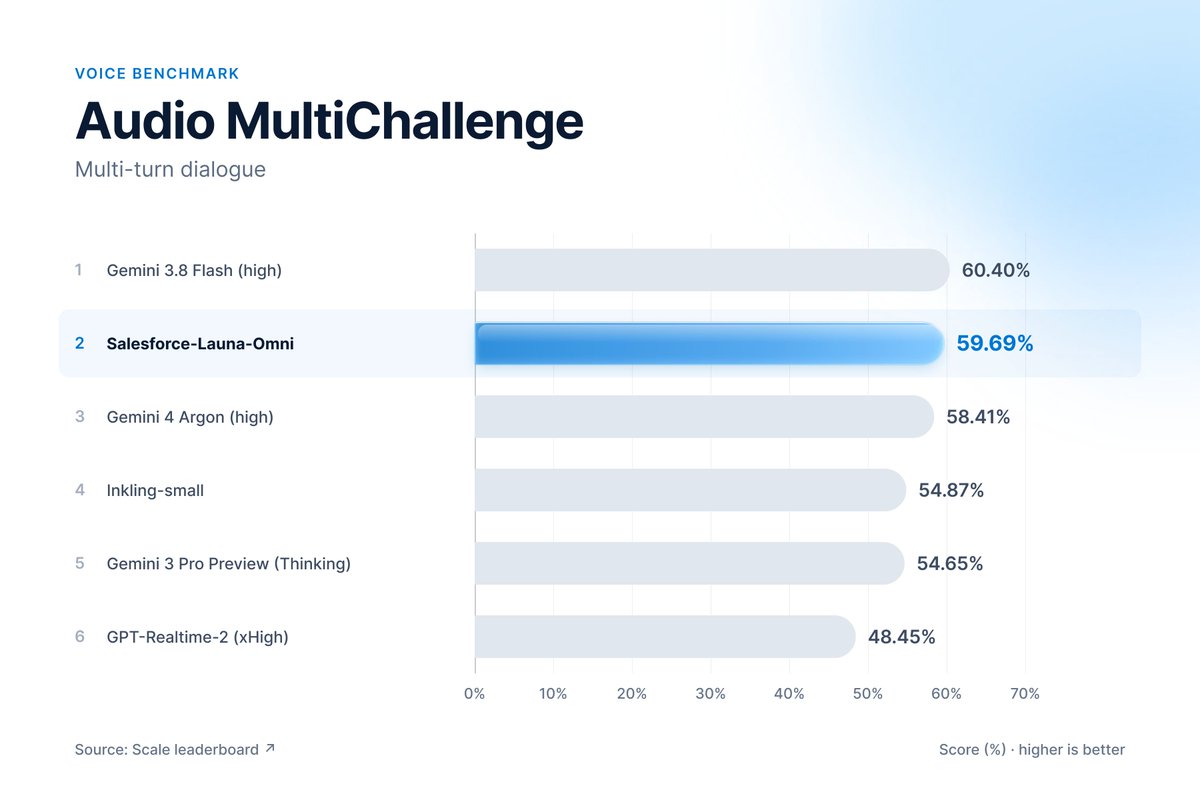
🎤 Most voice AI turns your speech into text, then thinks about the text. Everything else in your voice is already gone.
👂 Meet Launa-Omni. It hears you.
Just dropped: a new enterprise voice model from Salesforce AI Research. The leaderboards speak for themselves (links in comments). 👇
https://t.co/RUWVy6pV2W
On the Fragility of Self-Improving Agents: Variance, Task Order, and Underspecification: https://t.co/uSh4hMOp6G
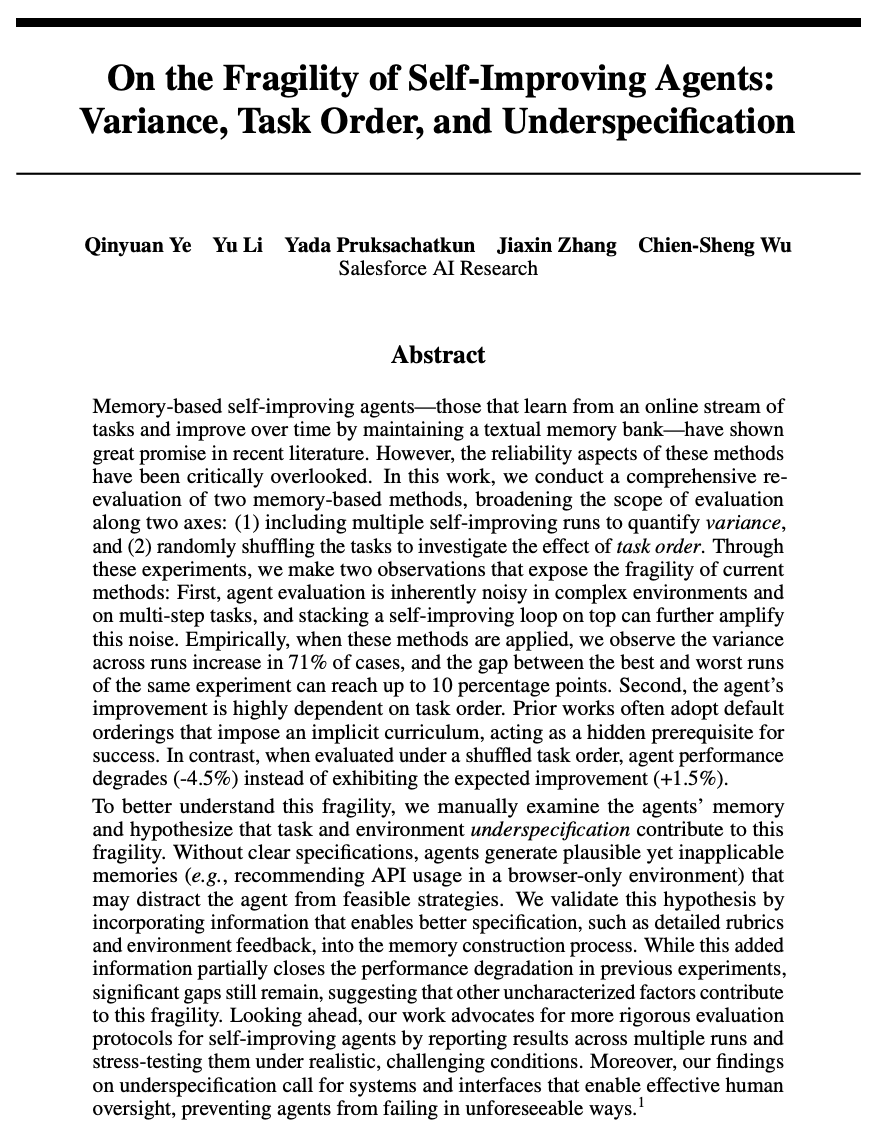
Memory-based agents learn from a stream of tasks and save lessons for future work. We re-evaluated two established methods across WebArena, VisualWebArena, and SCUBA, running each experiment multiple times and shuffling task order to reflect how requests arrive in practice.
What we learned:
📊 Results can vary widely across runs, so reporting multiple runs gives a clearer picture of real progress.
🔀 Default benchmark orderings follow an easy-to-hard curriculum, while real-world requests arrive in any order.
🧭 Clearer specification leads to more useful memories. Adding rubrics, environment feedback, and clearer prompts to memory construction closed 31% of the performance drop under shuffled task order.
The findings point toward stronger evaluation practices, memory validation, and interfaces that support human oversight. Code and data are available as open science.
#FutureOfAI #EnterpriseAI
Thanks for the spotlight, @omarsar0! 🙌
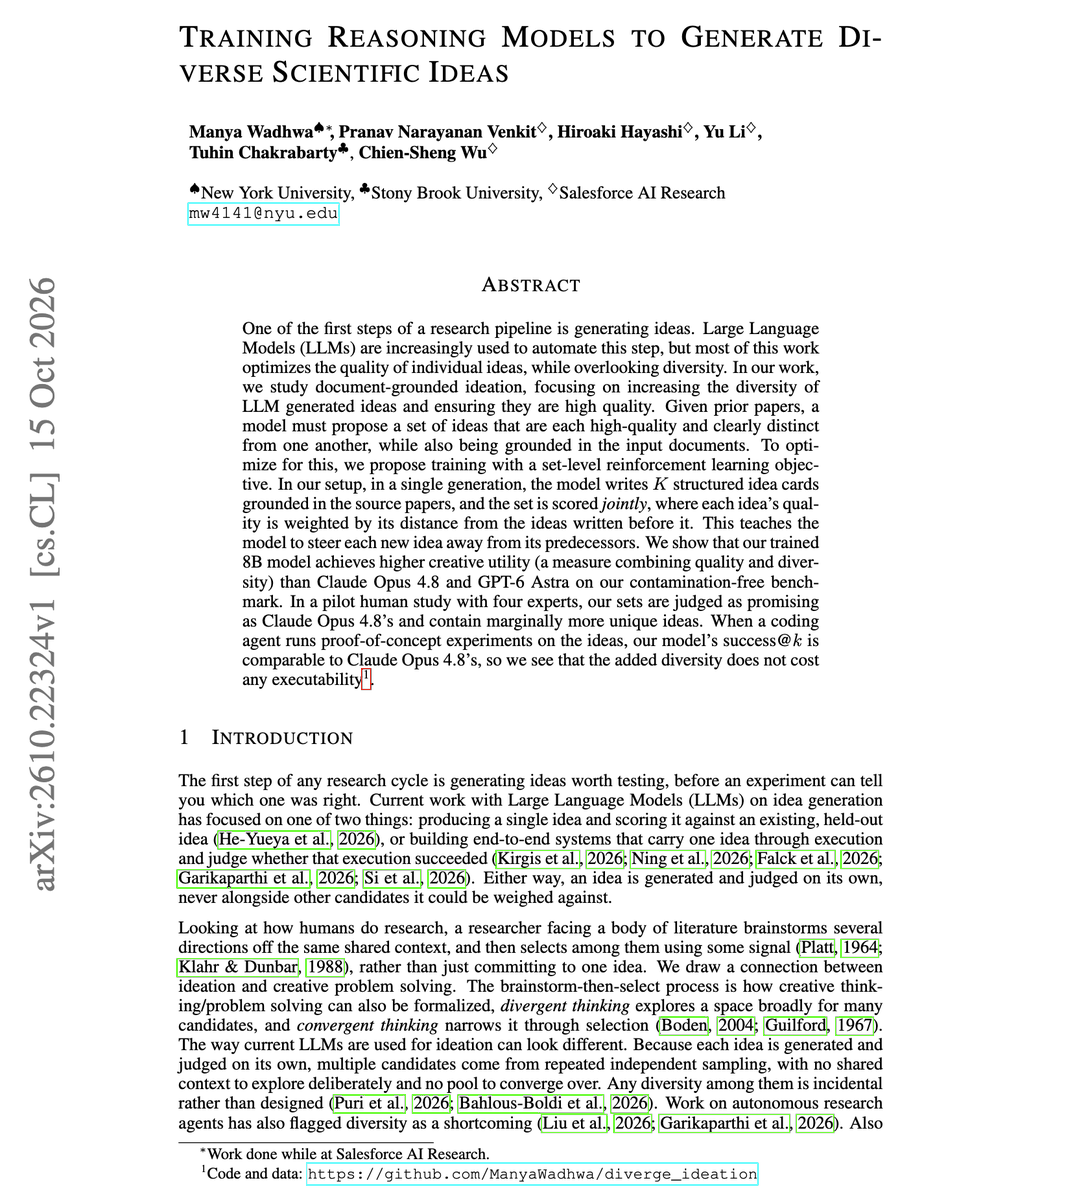
AI ideation tends to repeat itself, so we rewarded the whole set: each new idea scores higher the further it moves from the ones before it. 👇
Great application of small language models from Salesforce and colleagues.
AI-scientist pipelines are well known to struggle to propose novel and diverse research ideas.
This team trains an 8B reasoning model to write several research ideas in one generation from a set of source papers.
The reward scores the whole set, weighting each idea's quality by how far it sits from the ideas written before it. The model learns to move each new idea away from the earlier ones.
On their contamination-free benchmark, the 8B model scores higher on creative utility, a measure that combines quality and diversity, than Claude Opus 4.8 and GPT-6 Astra.
https://t.co/U75ba31DV8
Chat with Paper: https://t.co/sMFyV5EZuM
Where are agents going next? Three shifts we see:
→ Voice and agents augment the UI
→ Agents from different companies negotiate and collaborate
→ Agents self-improve with every interaction
More in Scale Your Agentic Enterprise:
https://t.co/DBpSgZjPN3
#AgenticAI #EnterpriseAI
Moirai, our zero-shot forecasting foundation model, has made the journey from research to production. Data Cloud Forecast is now generally available, and teams can select Moirai with a single setting while existing queries keep working. https://t.co/EdkJyozjYO #EnterpriseAI
AutoInfra: Infrastructure for rapid, parallel experimentation
https://t.co/DxT05IqobY
TrainForge decides what to try. AutoInfra carries each experiment from request to result across shared GPU capacity, through a single Tinker-compatible training API.
It also trains the models that power TrainForge and AutoR&D-Engineer, so what those agents discover feeds directly into the next model version.
→ GPT-OSS-120B LoRA training at $0.199 per million tokens on AWS, compared with $2.33 at Tinker's listed price
→ 91.5% lower cost per token, an estimated $2.13M saved per 1T training tokens
→ Isolated algorithm, training, and sandbox environments guard against reward hacking across self-improvement cycles
#FutureOfAI #EnterpriseAI
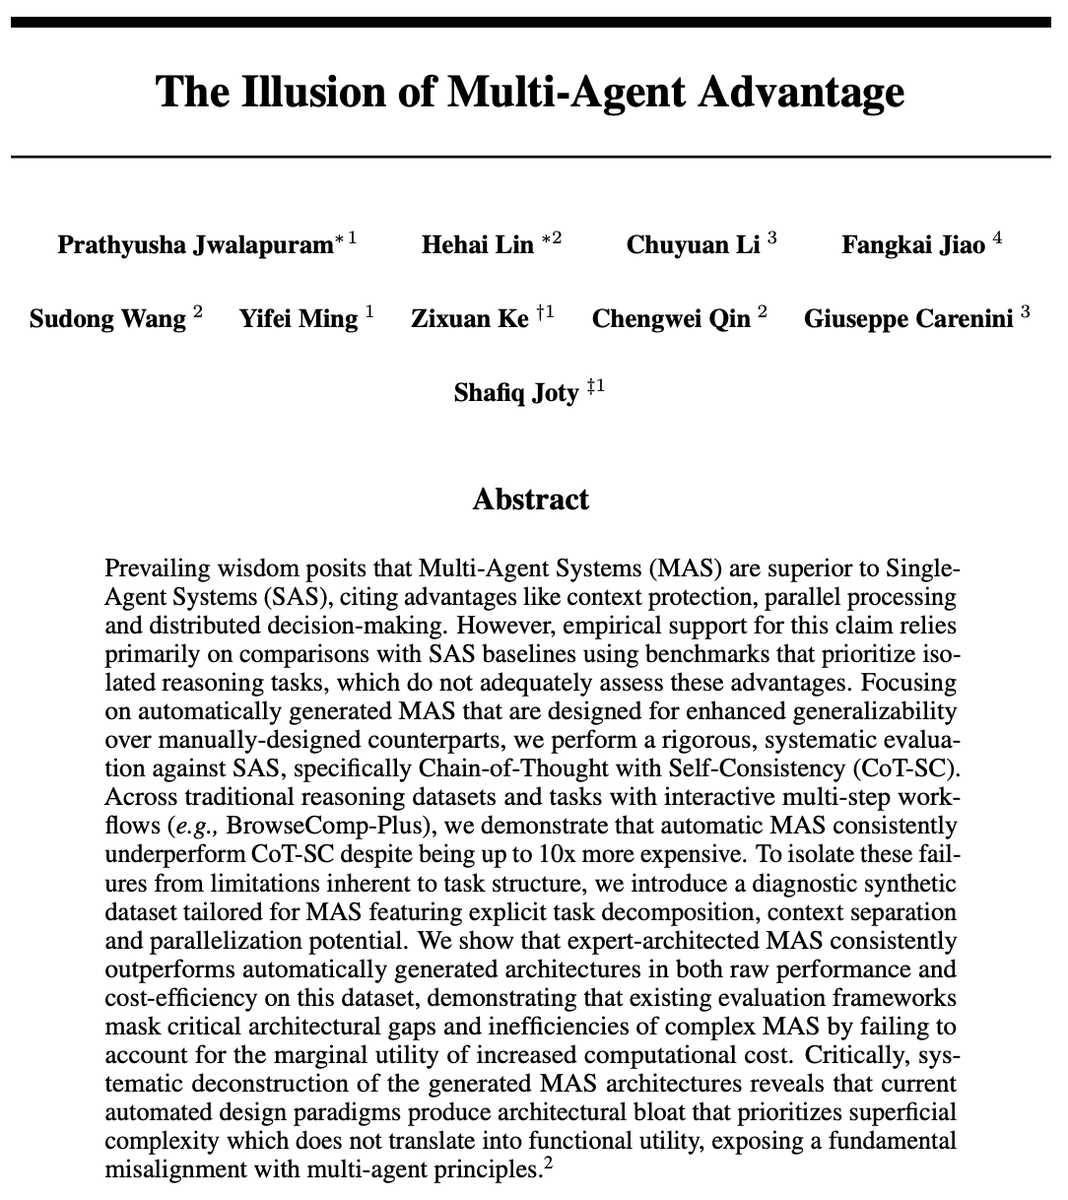
The illusion of multi-agent advantage: https://t.co/7BkU0h0KYG
Do multi-agent systems outperform a single agent? Across six automatic multi-agent frameworks, four LLMs, and five benchmarks, we found they consistently underperform Chain-of-Thought with Self-Consistency (CoT-SC) while costing up to 10x more.
→ CoT-SC often reaches higher accuracy at under 10% of the compute cost
→ A single-agent GPT-5 with CoT-SC beats the most sophisticated GPT-4o-based multi-agent frameworks using less than half the tokens
→ An expert-designed multi-agent system lifts GPT-5 from 57.0% to 96.5% on our new synthetic multi-hop financial reasoning (SMFR) benchmark, at cost comparable to CoT-SC
Multi-agent systems deliver when they are deliberately structured around parallelizable sub-tasks and context separation.
#AgenticAI #EnterpriseAI
Most teams find the outage, churn, or at-risk account after the moment to act has passed. 📡 Operational intelligence reasons over live business data continuously, so problems surface while there’s still time to fix them. https://t.co/JZrurvP0nx
Mastering Time Series Forecasting with Moirai 📈
→ 14% more accurate on understaffing
→ Nearly 40% more accurate on overstaffing
→ 30M+ downloads on Hugging Face
Itai Asseo @Digitai79 and Gautam Vasudev break down the impact: https://t.co/v5ny6T4Lcf
#EnterpriseAI #FutureOfAI
Scale Your Agentic Enterprise, Chapter 5, features our research on the Self-Evolving Enterprise, with @Digitai79 on why advantage now lives in orchestration, memory, feedback loops, and dark data.
https://t.co/Qtj6thuLka
#AgenticAI#EnterpriseAI
Best Friends, Not Forever: Evaluating Long-Horizon Persona Collapse and Behavioral Drift in AI Companions: https://t.co/SV4rSPXQF6
AI companions are expected to keep a consistent role and a shared history with users over time. Our benchmark ANCHOR tests both across 2,008 synthetic conversations, each running 85–130 sessions with four models.
On four-choice questions about what happened earlier in a conversation, models averaged 44.4% accuracy. Random guessing scores 25%.
→ Questions about how a user's situation changed stayed at 21–25%, the level of a guess
→ Accuracy ranged from 35.5% to 63.6% across model and memory combinations
→ No tested memory setting (long context, summaries, self-managed notes, or retrieval) consistently closed the gap
The findings point to stronger state updating and temporal memory as the next requirement for companions meant to carry a relationship forward.
#FutureOfAI #EnterpriseAI
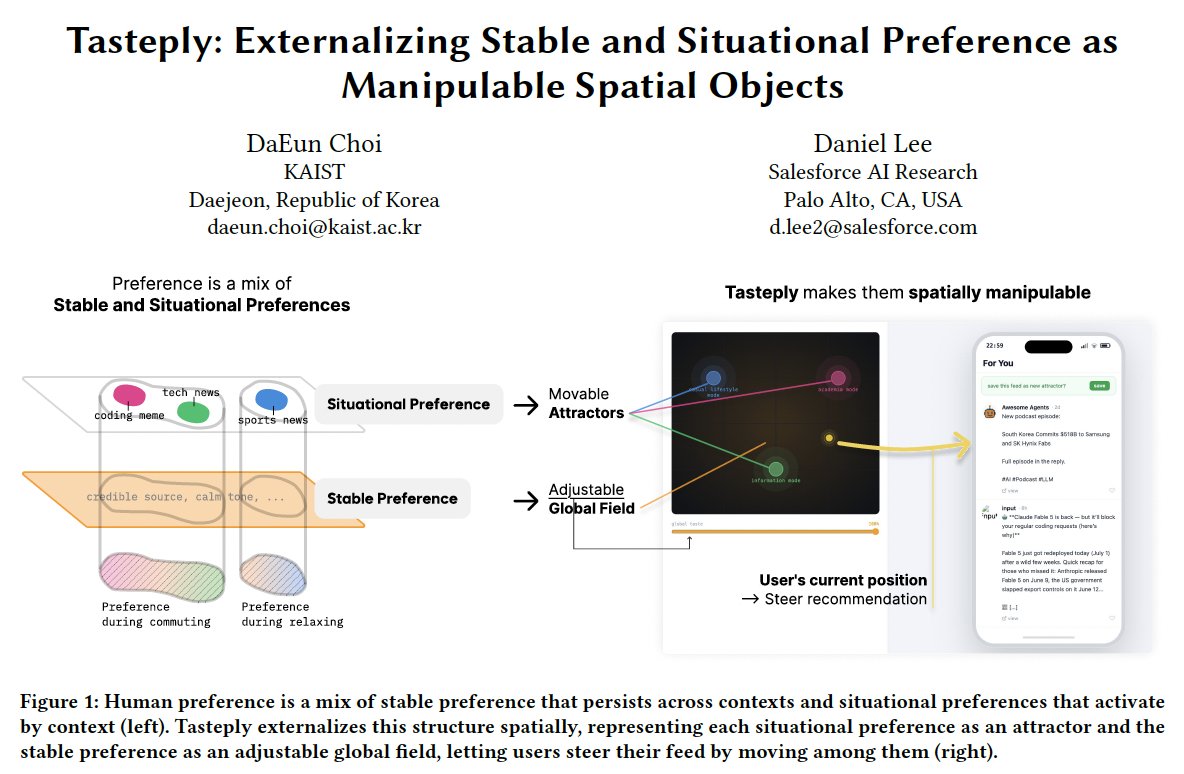
(3/3) 📄 Tasteply: Externalizing Stable and Situational Preference as Manipulable Spatial Objects
Lasting and in-the-moment preferences become spatial objects people can see, move, and adjust to steer how AI personalizes for them.
#UIST2026#FutureOfAI
(1/3) We're heading to Detroit for #UIST2026 (Nov 2-5) with 2 posters on interfaces that adapt to people 🧵
→ CORAL: generative interfaces that keep learning from collective use
→ Tasteply: preferences you can see, move, and shape
(2/3) 📄 CORAL: Continually Learning Generative Interfaces from Collective User Interactions
Generative UI is new, and early work builds interfaces in one shot. CORAL keeps learning from how people collectively use an interface and improves it over time.