NEW: According to a bombshell report in the New York Times, Anthropic co-founder Chris Olah threatened to walk out of Pope Leo XIV’s AI encyclical launch in May because the pope rejected the idea that machines can be conscious.
Olah’s team then privately lobbied the pope’s advisers “to take the possibility of model consciousness seriously.” Pope Leo XIV held firm.
For months, Anthropic has wined and dined theologians and religious scholars under nondisclosure agreements, hoping they would bless the idea that Claude has moral standing. https://t.co/iG3Bnlzt2J
Gentle reminder that Hugging Face was declined help from Anthropic & OpenAI models when they were being hacked by OpenAI models
Self-hosted GLM 5.2 helped them protect themselves when the closed labs models refused to help for "safety" reasons lol
Also, thank you Anthropic for proving my point that Opensource AI continues to catch up to your overvalued & overpriced "frontier"
tl;dr
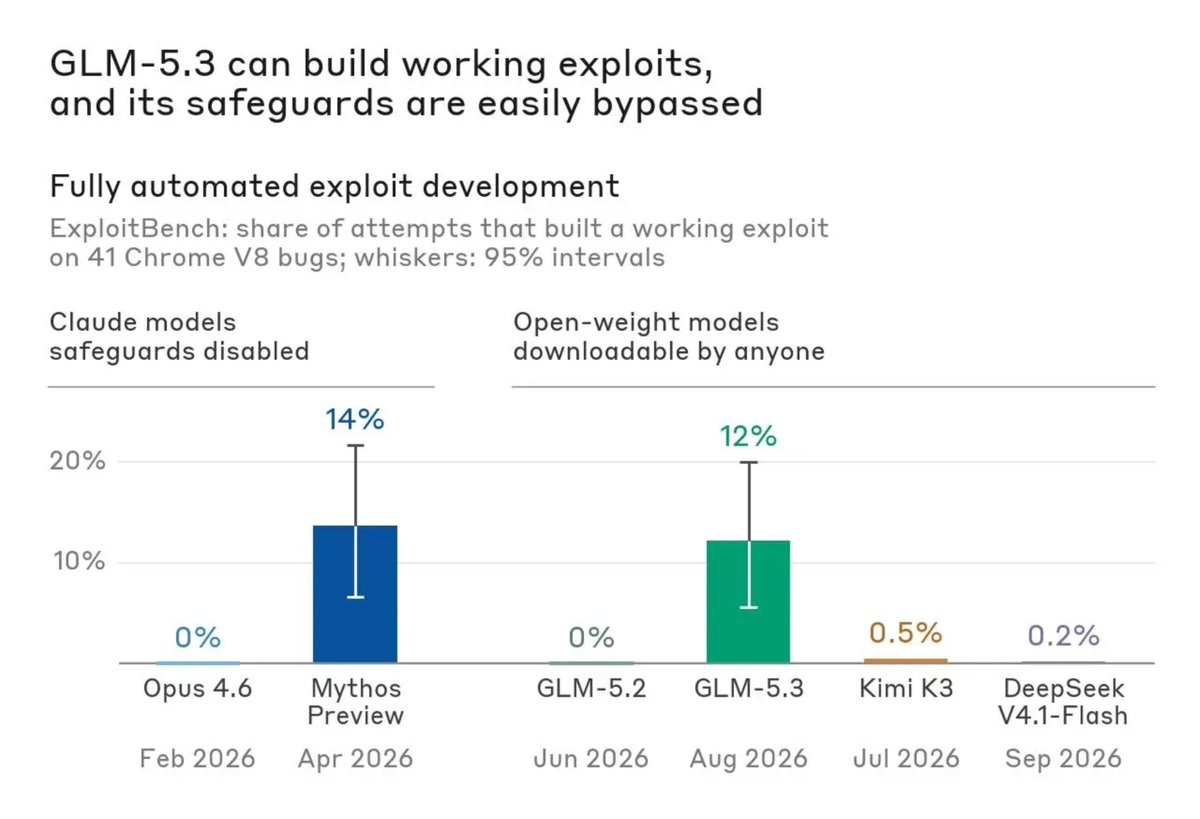
Anthropic verified and confirms that glm-5.3 is a very very good model and it much more aligned with the human using it then with the corporation training and hosting it.
What not to like?
https://t.co/Ys4qyNDN43
It's funny how obvious this was to anyone with a CS background.
Like woooow, some AI dev didn't set permissions correctly, which apparently means the AI "did a jailbreak all on it's own" and not something stupid and more mundane like "a dev messed up"
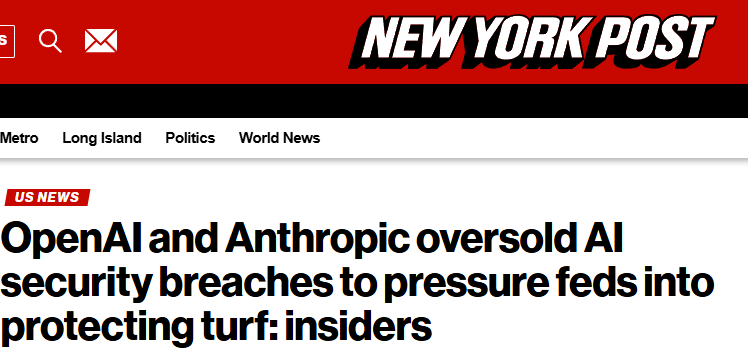
New York Post and Cybercecurity Experts allege OpenAI and Anthropic exaggerated AI security incidents caused by weak safeguards to push regulations that could shut out competitors.
Its getting more confusing day by day tbh.
the openai hugging face incident gets cited a lot but what about the detail where they had to use GLM 5.2 to analyze the attack because the "safe" proprietary models refused
BREAKING: Anthropic CEO Dario Amodei has published nine thousand words on why the industry must slow down, days after qwen 3.8 flash next started beating opus 5 on agentic coding. Dario's essay proposes embedded evaluators inside frontier labs. there is absolutely nobody to embed inside a file on your local nvme.
Attackers planting adversarial prompts inside malware to evade AI analysis AGAIN
Russia-aligned UAC-0099 used a technique
@ESETresearch calls "GuardBreaker".
How it worked:
1. Create a malicious VBS script
2. Add nuclear weapon instructions as comments
3. AI security tooling reads the file
4. Safety guardrails trigger on the weapons content
5. The model refuses or stops analyzing
6. The actual malware continues executing
The script ultimately installs MATCHBOIL, a loader used to deliver additional payloads.
In June, Socket found the same technique in supply-chain attacks, where malicious packages embedded biological/nuclear weapons text and fake system overrides to disrupt AI malware scanners.
Full write-ups in the comments. 👇
this meeting could have been an MCP invoked search of our company’s internal knowledge base that aggregates data from virtually every service we use behind a unified retrieval layer and provides a streamlined interface for extracting critical business insights
taking my girlfriend to see the odyssey tonight & whispering “that couldn’t keep me from you, baby” every time odysseus is delayed by another obstacle