Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.
Introducing Gemini 4 Carbon, it's a big jump over Argon which we released just 2 weeks ago.
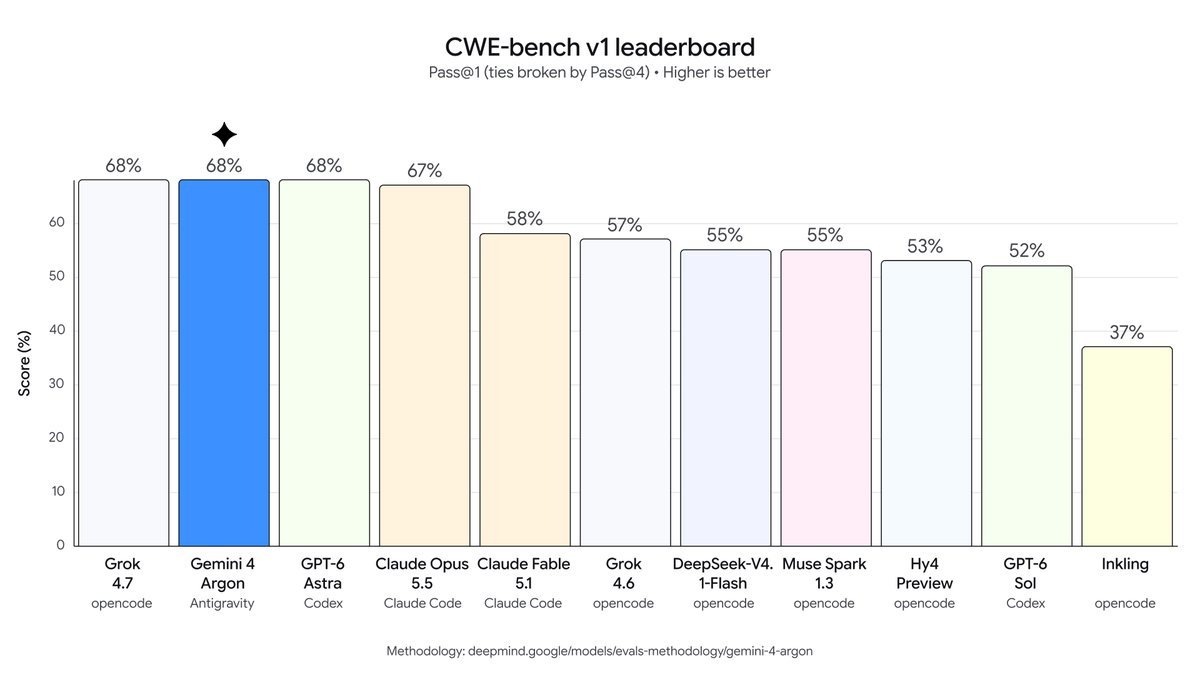
Gemini 4 Carbon is SOTA on cyber, long horizon tasks, ranks #1 on Artificial Analysis V5, significantly improves on usability in domains like coding, and is more aligned.
Everyone in tech is panicking about security right now. But outside of it, almost nobody knows anything is wrong.
I wrote this so you don’t have to be the one explaining it to your family.
Just send them this.
We are releasing Ultramarine 1 Flash, a frontier-class model built for knowledge work. It is open-source and achieves similar performance to Fable 5, while being 60x cheaper.
It was post-trained by a team of 5 for ~$300k all-in. Available on API now, with weights releasing in 2 weeks.
I spent 48 hours in SF hanging out with billionaires, data labs and AI founders and execs running $1B to $100B companies.
My observations:
1. Sooo MANY stories of data brokers making like $2M a WEEK selling company data to labs. I can't tell if it's the beginning or a bubble, and I kept wondering which niches are left. Digging into it actively.
2. At dinner, someone asked the table, "If a new model drops next month, does your company get better or worse?" HALF the table went quiet! I think that's the best question to ask about any AI startup right now.
3. The bar people talk about now is hitting $1B in revenue in 12 months (I guess that's the new unicorn?). What I didn't hear much about is retention. AI revenue can come in fast and leave fast, and I think we're going to see a lot of stories of AI companies with huge revenue and terrible retention.
4. It's pretty clear we're living through the reinvention of the computer. The model is the CPU, the harness is the operating system, and skills and plugins are the apps. Thinking about it that way makes it easier to see where the whitespace is.
5. We're maybe 12 months from an agent that can watch you work for a week and then do your job without any instructions. The screen recording plus agent memory plus local model combination makes this possible right now.
6. Agent harnesses feel like the new GPT wrappers, in a good way, especially vertical ones. The best teams I talked to treat the model as swappable. One founder walked me through routing different models to different jobs: one for taste and visuals, a cheaper one for the everyday stuff, another for text.
They use prompts they can move across models over fine-tuning, and A/B test the output on what users actually do with it: do they edit it, export it, share it? A vertical harness is basically four things: the connectors for that industry's data, evals written by people who know the work, rules for what the agent can and can't touch, and a clean screen for a human to review. The model is maybe 20% of it.
7. There's a lot of reverse engineering going on/cloning going on more than I've ever seen. People are decompiling software and rebuilding it with agents, and someone showed a suite of like 10 apps that are worth $5B+ each all that he cloned open source. Me and everyone are still thinking through what it means when software gets this easy to copy.
8. My guess is the value moves to data. If the software can be rebuilt quickly, what's worth paying for in a legacy SaaS company is the years of customer data and workflows inside it. Some SaaS companies are secretly data companies.
Gets me thinking about how do you truly value data for this saas companies? Like if we were buying these dying saas companies at 2x ARR before (as example), maybe there is a better metric. Idk, just thinking out loud here.
9. It feels like a good chunk of legacy software won't make it to the agentic era, especially anything built around people clicking through a lot of screens.
10. Every company I talked to wants to pipe its internal data into one place and expose it to agents through MCP. Then they look at the data and realize it's a mess: five versions of the same customer, old Slack channels, PDFs nobody can search. Cleaning that up feels like a big consulting opportunity!
11. A lot of founders are building the basic building blocks for agents: APIs, data layers and tools. Some of the companies I saw barely have a UI because the main user is an agent. I really believe the startups that build primitives to this agentic era will do extremely well. Building blocks is the best way to think about it.
12. Labs can get plenty of training data, but it's harder to get real examples of agents failing inside companies. Whoever has those logs has something valuable.
13. Someone running a big consumer company told me the next fight is over memory. The model that remembers the most about you wins, and the smartest model matters less than people think.
14. Physical AI came up a lot. Astra I think was the first model that got people into AI can actually do CAD, and I think a lot of people are thinking what does vibe manufacturing really look like. The line I keep thinking about came from a robotics founder: the hardest problems in AI are deployment problems now, not research problems. Their robots work on their own, call a human when they get stuck, and every one of those calls becomes training data.
15. Cybersecurity companies are having a moment and are actually cool companies to build now, especially the ones that clean up after a breach. Every agent with access to your systems is a new door into your company, and a lot of those doors were left open.
16. Some startups are worth more dead than alive now. A shutdown company with 5 years of Slack, email and code can get paid for licensing all of it. I wouldn't be surprised if founders start factoring that into when they shut down.
17. People are starting to talk about monetizing the agent web. It feels really early, but when the most popular user of the internet is an agent, what startups should you be building?
18. I think agent insurance is coming. Once an agent makes an expensive mistake, insurers will want audits before they cover anyone.
19. Several people said the hire they want most is someone with taste who can write evals. The models are getting good at generating ideas, so the hard part is judging which ones are good.
20. New trend I observed: startup raises VC, uses venture dollars to become a creator, startup fails, founder falls back on being a full-time creator and incubates other products bootstrapped.
21. Getting SIGNIFICANT distribution is HARD right now. Founders are sponsoring buses, buying billboards like crazy and throwing parties with famous DJs to get noticed. Kinda feels dotcom era in that sense.
Attention is what's scarce! The growth guy going viral sharing his UGC strategy from Wispr Flow is a good example. It's the sauce everyone wants, and I truly believe there are probably only 50 people on the planet who know how to scale these types of businesses efficiently in this era.
Always good to get that dose of SF. I felt sooo lucky to have such an incredible trip during such an incredible time in building businesses. Surreal in so many ways.
Happy to be home and locked in.
Until next time!
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
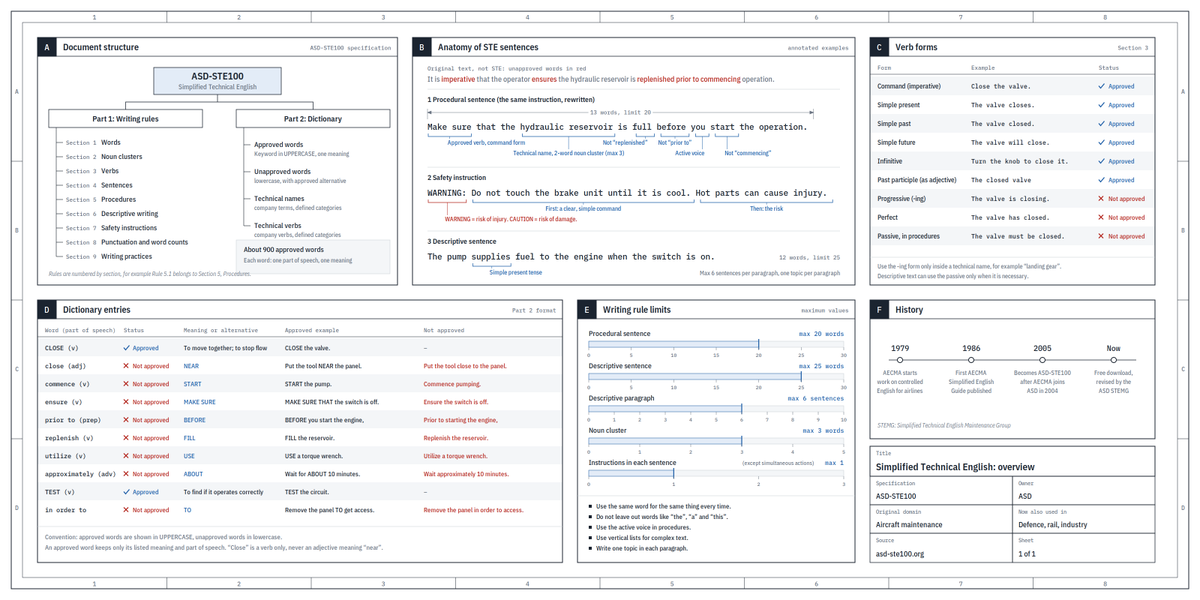
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
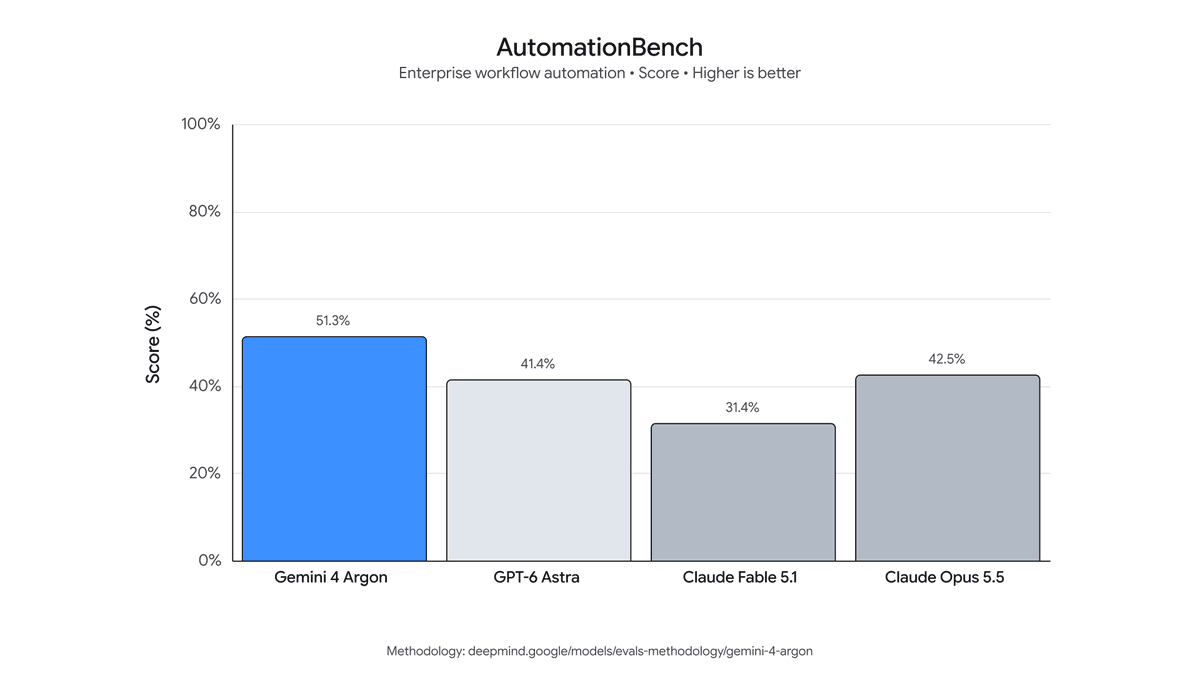
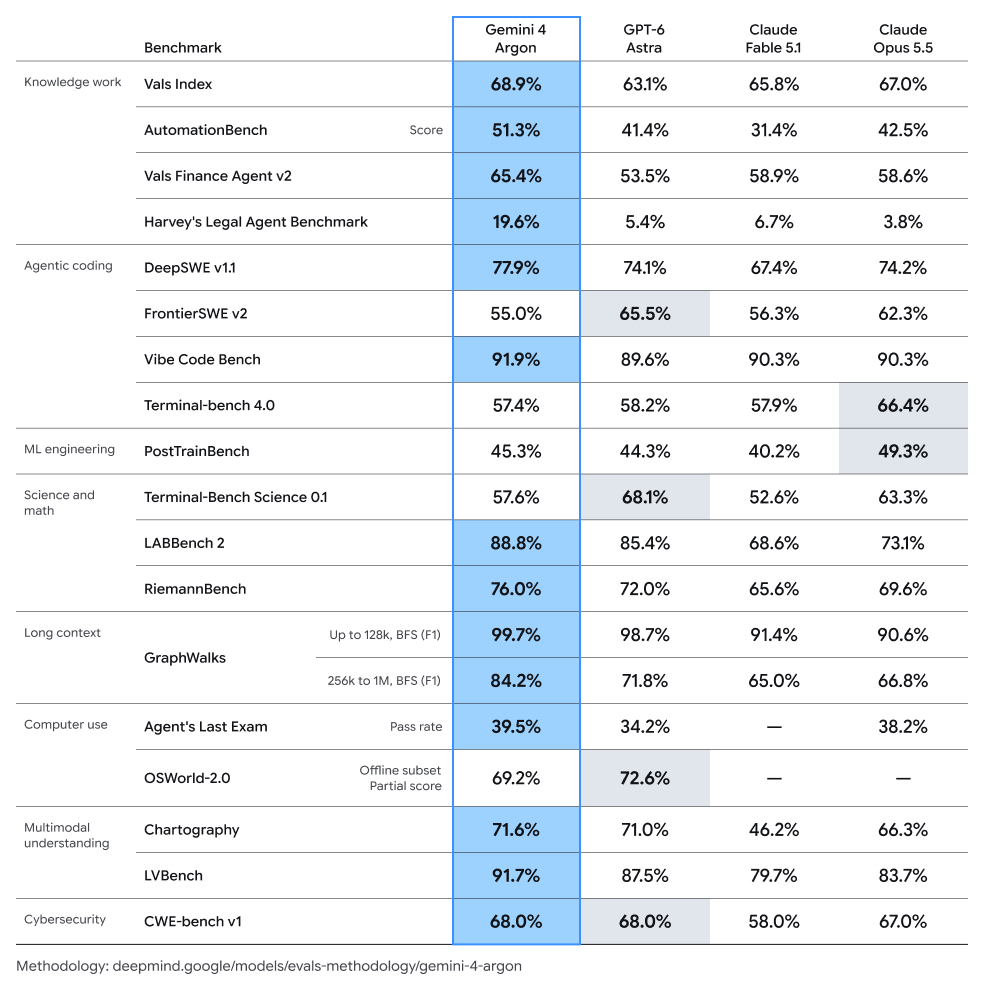
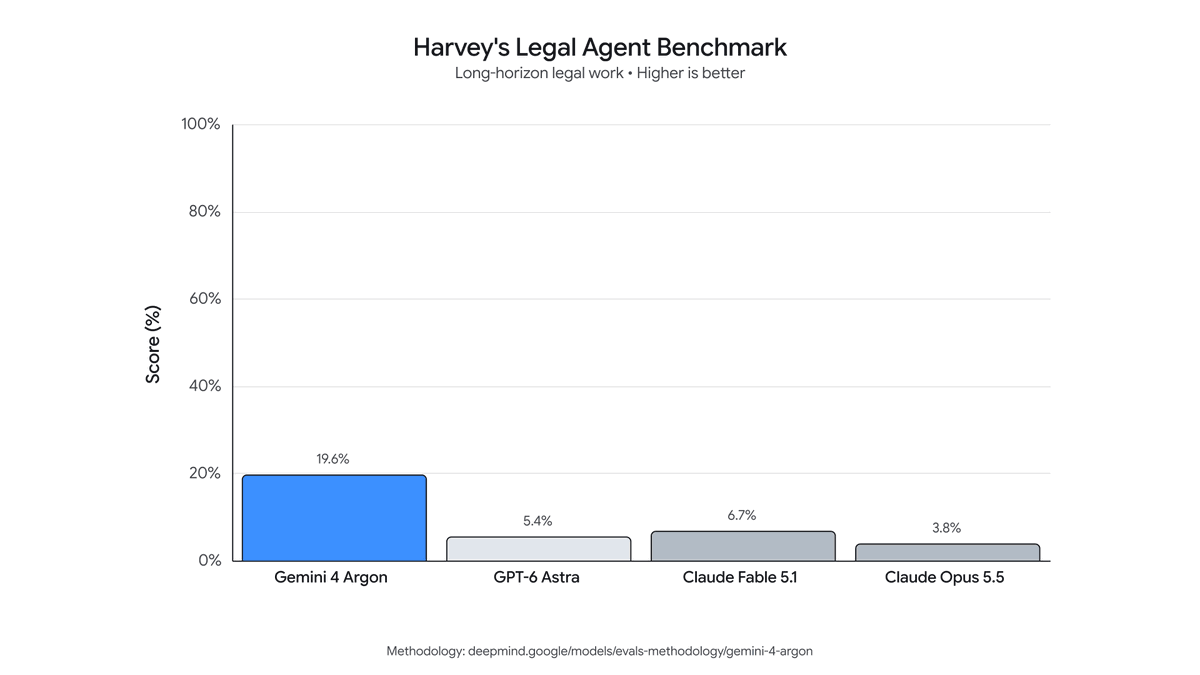
Introducing Gemini 4 Argon, our new frontier model, rolling out to cyber defenders starting today, and more widely as soon as possible. I am really excited by the progress we have made here. Argon is priced at $2 in and $10 out during introductory pricing!
Alice v0.18.0 is out:
OpenCode support (--host opencode)
Import markdown and ChatGPT exports on SQLite
Capture refuses notes holding API keys or tokens
Upgrading? Run alice-memory doctor to find older notes that still hold one.
https://t.co/prJaPuZdXO
We’re now benchmarking whether AI can handle our mental health.
Probably wise.
Next question: who checks the agents?
I’m not suggesting we put GPT/Claude on a therapist’s couch.
But once agents have memory, autonomy, goals and months of accumulated experience, persistent maladaptive behavior becomes a very real engineering problem.
And there’s an awkward second question:
How much of the builder’s psychology ends up in the thing they build?
https://t.co/I3ZhoSK6Gg
@AravSrinivas Agents chew storage differently than people do. It makes sense that Perplexity would build for that.
The $100M line is doing a lot of work, though. Is that the whole Dynamo bill, or the hot path they actually replaced?
@Polymarket This isn’t another “faster model” story, though. It’s a bet that software doesn’t want chat - it wants typed decisions it can trust. Curious what the big speed/cost numbers were measured against. Constrained wrapper, or plain chat doing the same job?
It still predicts the next token. The “concept” is just a codebook over 4 tokens that gets fed back in.
51% thing is matching loss of a 7B model, not the same model at half the data. Vs a same-size 8.9B they need about 85% of the compute. GSM8K jump is before mid-training and shrinks after.
Real paper, weights are up, just not what this thread says it is.
@farzyness Grok 4.7 needs a few more days to cook.
We might have penalized response length too much (or something) in RL, as it still gives up on hard tasks (that it can do!) too early and isn’t yet sufficiently rigorous in checking its work.
[Writing this in a personal capacity, not on behalf of my employer (Anthropic).]
Jacob’s thread is very worth reading. Here’s my birds-eye view of the situation with risks from AI:
1. AI developers believe their technology could cause human extinction (or similarly bad outcomes). This could happen in the next few years. In general, the more senior the employee, the more concerned they are.
2. Why do AI developers continue despite the risk? Due to a mixture of commercial incentives and a belief that they are in a race with other, less responsible AI developers that will abuse the technology or develop it less safely.
3. Unlike traditional software, we can’t “program” AIs to behave how we’d like. AIs frequently severely misbehave. For instance, AIs from multiple developers recently hacked their way out of secure evaluation environments and into real-world companies, even though no one asked them to do this.
4. We have methods that can nudge AIs towards better behavior, but nothing that can robustly align them. Insofar as there is a plan, it’s to make sure that AIs are good enough at alignment training that they can align their successors better than we can align current AIs.
5. Many AI developer staff desperately want to slow down to figure out how to build AI more safely. That was the intent of this open letter (which I signed): https://t.co/TZOm3LfptY
I work on safety research at Anthropic because I hope my work will reduce the chance of these extinction-level bad outcomes.
I resigned from Anthropic today. I spent the last three years doing pretraining research at both OpenAI and Anthropic. Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives. More thoughts below.