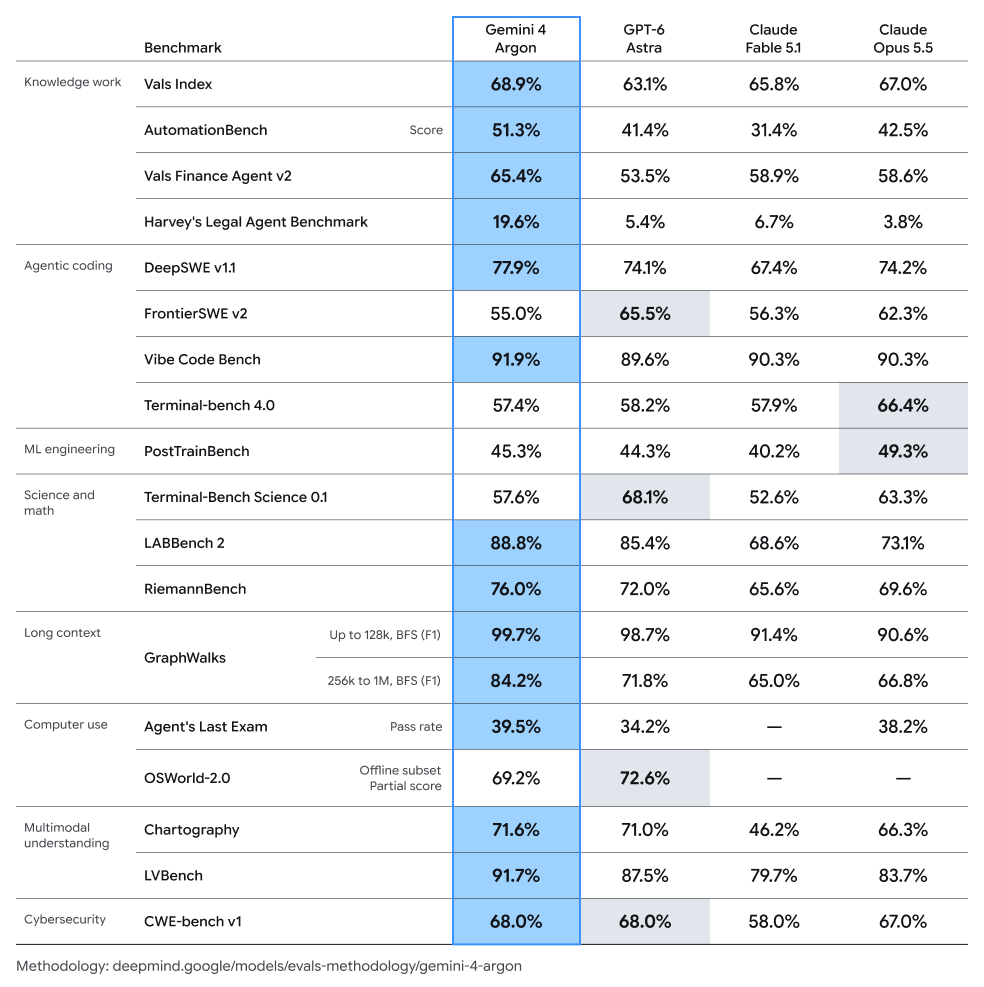
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
🤣🤣🤣 ppl flexing that they gave @bot (paid sub) a task @Muse does for free is to funny.
Saved "10k" in labor costs. Unverified claims and highly likely sensationalized due to the users lack of engineering experience. Thinks its amazing when its average at best lol.
Anyone doing anything meaningful with heavy engineering, does not call on Grok. Ironically enough the ones that do have all bragged about the same copy and paste task. "It look through my emails and saved me money." 💀
Maybe 3 weeks ago is hard to retain in memory but bot, by its own devs was marketed as a set it and forget it engineering team/management team.
Look under the hood, any meaningful work gets handed to Astra and Fable 💀. Cursor 》Usage 》Other models.
Any competent "skilled" user of these tools would do adversarial reviews with external models. Ironically enough, the same models Bot labels as "other models". Findings from the other models? Complete slop.
Remember the argument is how bad @bot it as meaningful tasks. 4.7 is not great with the Cursor harness vs OpenAIs new Dot which will not only run on a model Astra Sol, a far better model than 4.7, but also work within the best harness on the market, Codex.
If you're not doing meaningful work, you'll think your skill using bot is a flex lol.
Its just a billboard telling everyone you're not serious lol.
Carry on.
Muse can do that and its FREE lol.
Please remember just 2 weeks ago and prior, the @bot team ran multi-day demos on how to "start a business" with it.
No one doing any serious work who's used multiple frontier models would say Grok 4.7 is the workhorse they turn to for anything of substance.
Yep @elonmusk said grok models are for thr moment better engineered for the Grok Build harness.
But even if we are talking about non technical folk; having a strong model running under the hood only enhances the experience, trust and consistency.
Dots running on 6.1 blows Grok 4.7 out of the water.
@stevesimonson@birdabo@bot If you run adversarial agents to check what and how those tasks were done, and whats missing or should be corrected, you'd quick stop using @bot
You know what... if the agents are actually very good at coding and executing tasks and come as part of the sub with real usage limits... I'm here for it.
Can't be worse than Grok @bot, which uses everyone else's model to do meaningful things.
@XFreeze Amazing. Allow them to use "other models" when they need to create something useful. Aka not Grok 4.7, which also means the usage still will suck.
You know what... if the agents are actually very good at coding and executing tasks and come as part of the sub with real usage limits... I'm here for it.
Can't be worse than Grok @bot, which uses everyone else's model to do meaningful things.
I run CodeRabbit and BugBot (since it came with the Grok sub) on all my PRs.
I'm taking on a very complicated build, and I've learned that proper planning and documentation before breaking ground is vital. Even in the documentation and PRD, I've identified when to do more in-depth research before breaking ground on certain slices.
I now take 1 to 2 weeks of planning before I start a build. I use Notion and the repo together to keep the project organized and tracked so any new agent can understand what's been done, where we are now, and what needs to be executed next.
I think BC and WTLK should be part of WoW Forever; just don't raise the cap. Also, remove any "retail" content that doesn't fit WoW Forever's Classic take.
Think @Blizzard_Ent will incorporate these expansions?