Ahora que todo el mundo escribe con su #IA en el JIRA, en los emails... Estaría bien un estudio sobre la personalidad IA vs la personalidad de la persona real.
Adoro a mi equipo dev, pero ahora las incis están MUCHO mejor documentadas je je!!
@david_bonilla@bonilista Al hilo de la Bonilista, te paso este artículo que me ha parecido muy interesante los conceptos que maneja: https://t.co/N7ihUTmawp
EL FUTURO YA LLEGÓ
(shit)
Materialized Science Fiction: The Tech Oligarchy’s Blueprint for a New Global Order | Global Studies Quarterly | Oxford Academic https://t.co/w9SMPpP8on
Acá traducido = https://t.co/Hwqkf9MGjT
LLM Knowledge Bases
Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So:
Data ingest:
I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them.
IDE:
I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides).
Q&A:
Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale.
Output:
Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base.
Linting:
I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into.
Extra tools:
I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries.
Further explorations:
As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows.
TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
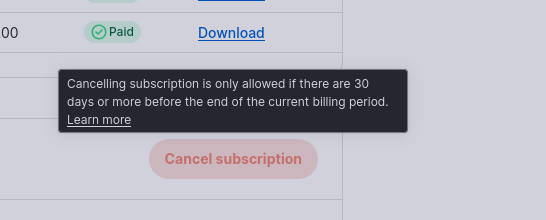
@Jira it's really dificult to report you a bug! I had to post it in the community (and I hope the technical team will turn up in the end), but as UX I would die to have my website mistakes reported by my users 😝
@Flomerboy@jinaniLXD To me, Claude Design is an interface for designers who were hesitant to try Claude Code. I still prefer Code because I don't run out of tokens there :)
7. Know when to slow down and do things by hand
New icons, spot illustrations, naming. Some details will always make an outsized impact. It can be easy to get sucked into the hyper speed of agentic designing. Knowing when to slow down is an art form of its own.
🧵 My tips for getting the best results out of Claude Design! I’m on the verticals team at Anthropic which means I serve 7 different products. Claude Design makes it possible!
1. Set up your design system and your core screens. An hour of setup and refinement here is worth it
Si en algo ayuda la mejora de ChatGPT en imágenes, es la capacidad de condensación de información para tener una infografía relativamente buena en segundos.
El término de Toffler es un desbordamiento adaptativo. Hay tanta carga cognitiva, tantos cambios y exceso de novedad, que perdemos nuestra capacidad real de asimilación, siendo un elemento social y estructural.
Mark Cuban just described the largest wealth transfer of the AI era.
Almost nobody understood what he said.
Cuban: “There are 33 million companies in this country. Aren’t going to have AI budgets. Aren’t going to have AI experts.”
Not tech startups.
The shoe store. The regional trucking outfit. The accounting firm with 12 employees.
The businesses that actually run the physical economy.
They know AI is coming. They have no idea what to do with it.
Cuban: “You’ve got the head of Microsoft saying software is dead because everything’s going to be customized to your unique utilization.”
Software is dead.
The SaaS era ran on one rule. Build a generic product. Force millions of companies to bend their workflows around it. Charge rent forever.
AI ends the contract.
The business stops bending to the software. The intelligence bends to the business.
But customized by whom.
The third-generation manufacturer cannot tell Claude from Gemini. The county hospital is staring at a reactor asking where the light switch is.
Cuban: “Who’s going to do it for them?”
That question is worth more than the frontier models themselves.
Hundreds of billions are being burned to build the foundation. The smartest engineers alive are locked in a bloodbath over who owns the base layer.
Let them fight.
Let them burn the capital. Let them drive the cost of raw intelligence toward zero.
Because the wealth does not collect where the brain is built.
It collects where the brain meets the business.
Every ambitious kid in college right now thinks survival means a seat at OpenAI or Anthropic.
Cuban is staring at the other 99 percent of the economy.
Learn the models. Then learn the messy, unglamorous reality of how a 50-person company actually operates.
Walk through the door. Understand their problems. Wire the intelligence directly into their revenue.
That is not a job title. That is an entire economic class being born.
You do not need to build the brain. You need to build the nervous system.
The biggest winners of the electricity era were not the engineers who built the generators. They were the ones who walked into dark factories and showed the owners where to plug in.
33 million companies are standing in the dark right now.
Silicon Valley is racing to build the god. The fortunes will belong to whoever teaches him a trade.
Del buscador al asistente: la revolución de la IA en los viajes, ¿podrán las grandes OTAs estar a la altura y competir contra las nuevas empresas nacidas IA o la propia IA? Te cuento el estado actual del sector travel... > https://t.co/9cgqfjlApj #AI#Travel
Replacing productive workers with AI will be terrible. There is definitely an issue in many corporates where they have real difficulties in identifying who is a productive worker and who isn’t.
But that may usher in a new era of entrepreneurs. Many massively successful entrepreneurs were fired at some point.
Hoy he hecho mis primeras 2 PRs con Codex, una al proyecto de la guía de estilos y otra al del funnel de ventas. Lógicamente nada complicado, ¡pero mira! 2 incis menos en el JIRA y mejorando la accesibilidad y la experiencia del cliente :)