Ok time to get something food hadn’t eaten anything all day..
If you enjoy the repos and wishes to support community based open source repo, optimization, improvement
Use my donation site
https://t.co/wDJoFsUUzj
Trusted Infrastructure for Super Intelligence
Proud of the @Dell team. The first Vera Rubin NVL72 rack-scale system, fully integrated and shipping in volume. 🚀
Thank you @JensenHuang@nvidia. The pace of this partnership is unlike anything I've seen in 40+ years.
We just put our GLM 5.3 DERISKED weights on some B300s
We will be limiting slots during this rollout to make sure concurrency does not kill the experience.
https://t.co/VwWiAtlkJn
Sign up today
Cyber-Frost-3.8 API goes live this week
@AnthropicAI aint seen nothing yet wait until I unleash this "ABLITERATED" lol Step-5 preview.
Fuck your fable
Its Blackfrost Friday coming soon
Thanks Dario
https://t.co/x7TgEPyTuz
you all know the frontier size weight we customize for enterprises and security firm. but since @anthropic want to be the only one with "MYTHOS CAPABLE' models....not on my watch.
Blackfrost Exclusive Release
you can thank @AnthropicAI
https://t.co/eFKGdMuzlP
Training on this quantized DFlash2 drafter is taking longer than I anticipated but I think it will be worth it.
When testing training overfit prompts we were hitting close to 100% acceptance, so it’s definitely working.
Brief update where we are so far:
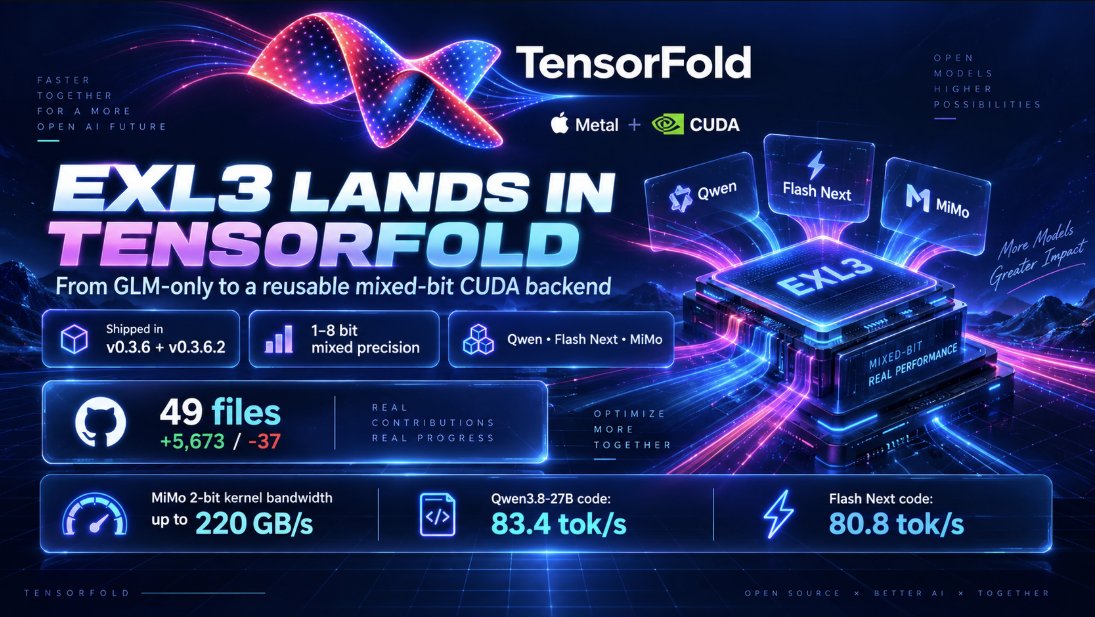
TensorFold 0.3.6 just took CUDA EXL3 from a GLM-only experiment to a reusable mixed-bit backend. 🤯
I wrote the shared EXL3 module that made that possible.🚀
49 files. +5,673 / -37. 3 codebooks. 1–8 bits. Mixed precision per tensor. ✍️
And it SHIPPED. ✅
Before this, TensorFold’s CUDA EXL3 path was built specifically around GLM-5.3-Flash’s 4-bit MCG experts.
Now the same infrastructure serves:
→ Qwen3.8-27B EXL3 + DFlash2
→ Qwen3.8-Flash-Next EXL3 + MTP
→ Mixed-K SAGE EXL3 packs
→ MiMo-V2.6-Flash EXL3 tensors through the same shared module
No separate EXL3 kernel stack for every new family.
𝗧𝗛𝗘 𝗣𝗔𝗥𝗧 𝗜’𝗠 𝗠𝗢𝗦𝗧 𝗣𝗥𝗢𝗨𝗗 𝗢𝗙
The reader understands:
3inst / MCG / mul1
1 → 8 bits
different widths per tensor
So one expert can be 2-bit while another is 8-bit.
Unsupported checkpoints fail early instead of getting halfway through a serve before exploding.
The CUDA linear is also row-invariant from 1 → 128 rows, with no cuBLAS dependency. A tensor’s result doesn’t change because more rows happened to arrive beside it.
Grouped routed-expert GEMV handles mixed widths in one launch per MoE projection and can be captured in a CUDA graph.
And I left TensorFold’s existing GLM EXL3 and MLX paths alone.
𝗧𝗛𝗘 𝗟𝗢𝗪-𝗕𝗜𝗧 𝗞𝗘𝗥𝗡𝗘𝗟 𝗪𝗔𝗦 𝗧𝗛𝗘 𝗦𝗨𝗥𝗣𝗥𝗜𝗦𝗘
On real MiMo 2-bit tensors:
q_proj: 157 → 220 GB/s
o_proj: 76 → 186 GB/s
down_proj: 79 → 193 GB/s
That is kernel bandwidth, not model tok/s.
And the new path stayed torch.equal across 2,472 outputs.
ExLlamaV3 measured 176–233 GB/s on those same tensors, so TensorFold’s 2-bit rows are no longer sitting 25–60% behind.
𝗔𝗡𝗗 𝗜𝗧 𝗔𝗖𝗧𝗨𝗔𝗟𝗟𝗬 𝗦𝗘𝗥𝗩𝗘𝗦
On ONE DGX Spark, Qwen3.8-27B 3.00 bpw EXL3:
Code sampled:
83.4 tok/s
TensorFold MLX 4-bit:
57.5 tok/s
vLLM MTP=3:
23.4 tok/s
Flash Next 3.05 bpw EXL3:
Code sampled:
80.8 vs 42.4 tok/s vLLM
Code greedy:
77.7 vs 40.9
Chat greedy:
69.2 vs 37.6
The mixed-K SAGE Flash Next pack also runs 1.51–1.55× ExLlamaV3 serial speed in the measured cells.
There are tradeoffs. Prefill still needs work, and ExLlamaV3 remains slightly faster serially on the highly tuned uniform 3.05 bpw pack.
That’s exactly why I’m publishing the actual numbers.
𝗧𝗛𝗘𝗡 𝟬.𝟯.𝟲.𝟮 𝗦𝗛𝗜𝗣𝗣𝗘𝗗
I went back in with two more contributions:
→ INT8 / INT4 KV cache for Flash Next CUDA
About 1.7× / 2.6× more context capacity in the same memory, while indexer state stays BF16.
→ --mtp-confidence
So the CUDA server can control when an MTP draft chain stops.
→ And a nasty EXL3 stop-token bug.
Some Qwen EXL3 packs stored <|im_end|> only in generation_config.json. TensorFold wasn’t reading it, so replies could run past the end of the assistant turn and leak the next turn or think text.
The CUDA loader reads it now.
TensorFold is a real game-changer for the local inference community where my EXL3 experience and code are now part of its released CUDA stack, and seeing something I wrote move from a model-specific problem into infrastructure other model families can reuse is one of my favorite parts of open source.
Huge respect to @ashxhart the creator of the TensorFold project for reviewing, integrating and shipping the work. 🙏
TensorFold 0.3.6:
https://t.co/rNfIcGOuju
TensorFold 0.3.6.2:
https://t.co/NpE6NbKiBi
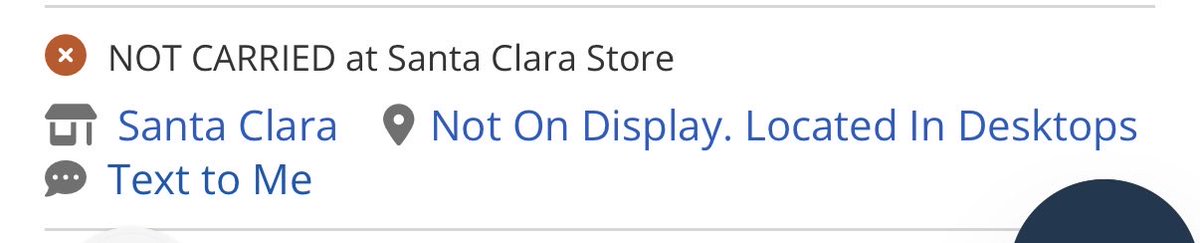
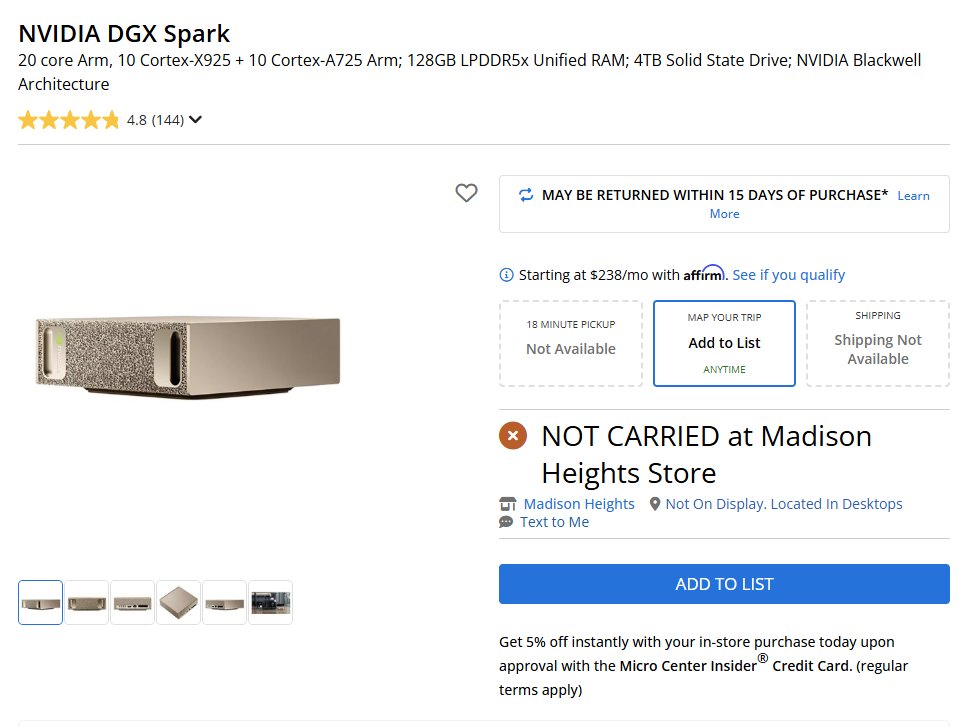
This is definitely a change the Spark now shows Not Carried at Microcenter.. not out of stock.
Thanks for the headsup DCRando2020!
(enlarged it of course).