@SachaMori and @Somjit77 will present their work on spectral temporal contrastive learning on Sat Dec 16, in the 2 poster sessions of the SSL theory and practice workshop in room 217-219
https://t.co/HhSO73EpuB
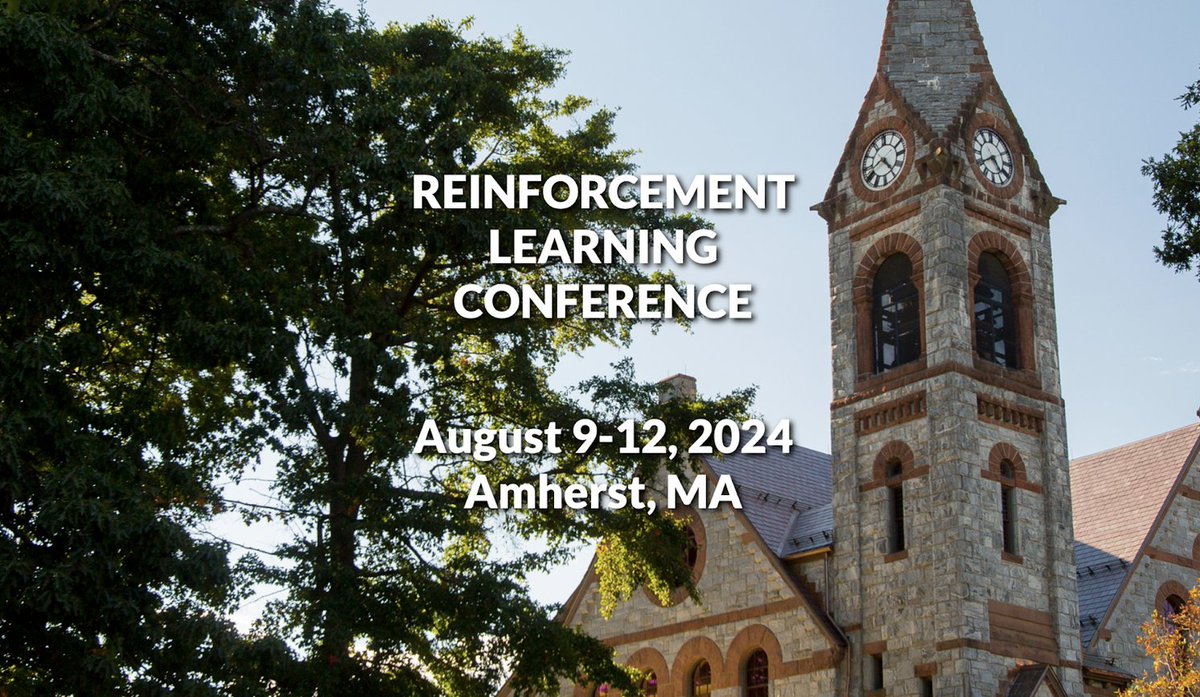
Thrilled to announce the first annual Reinforcement Learning Conference @RL_Conference, which will be held at UMass Amherst August 9-12!
RLC is the first strongly peer-reviewed RL venue with proceedings, and our call for papers is now available: https://t.co/QiZcJYM1MR.
I am thrilled to endorse this opportunity. Working with @khimya has been an inspirational journey and she is a fantastic mentor and amazing to work with. Don’t miss this chance and help spread the word!
Happy to share that ReLo has been accepted to #NeurIPS2023 🎉 Much thanks to the reviewers and my amazing collaborators @Somjit77@pedro_mbraga@SamiraEKahou.
Will be my first, first author paper I'm presenting, so looking forward to it!👀
See you at New Orleans!
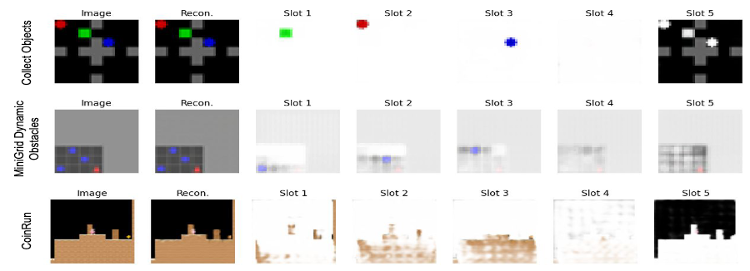
Excited to announce that our work “Discovering Object-Centric Generalized Value Functions From Pixels” has been accepted at #ICML2023! Shoutout to my amazing collaborators @gopeshh1, @khimya, and @SamiraEKahou for their hard work on this project.
Paper: https://t.co/NgSziuhg8P
Model your agents via conformal predictions!
Our work on “CAMMARL: Conformal Action Modeling in Multi-Agent RL” has been accepted at the CVPR 2023 Workshop on Multi-Agent Behaviour. Shoutout to my mentor @SamiraEKahou!
Arxiv link coming soon!
GitHub: https://t.co/DbTpo8pp8V
6/6 Additionally, our analysis of the learned slots and discovered GVFs provides easy explainability of the method. We’re excited about the potential applications of this work in reinforcement learning and look forward to sharing our findings at #ICML2023.
Excited to announce that our work “Discovering Object-Centric Generalized Value Functions From Pixels” has been accepted at #ICML2023! Shoutout to my amazing collaborators @gopeshh1, @khimya, and @SamiraEKahou for their hard work on this project.
Paper: https://t.co/NgSziuhg8P
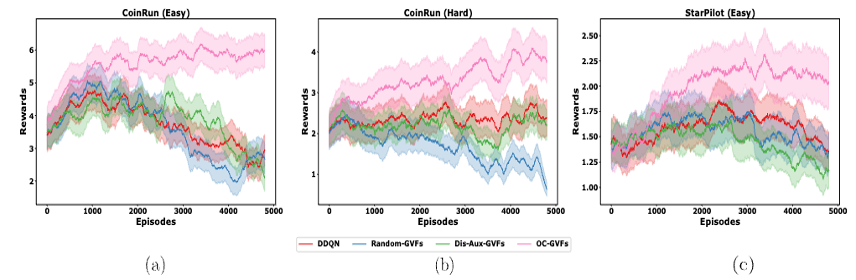
5/6 Our approach achieves improved results over current baselines in environments with non-stationary rewards and Procgen environments with changing levels of difficulty.
Together with @umaivodj and @MarlosCMachado, I am looking to recruit a postdoc for Fall'23 to work on:
- Deep Reinforcement learning
- Representation learning
- Explainability
- Privacy/Security
See full description here:
https://t.co/6iXp72Gmm8
@Mila_Quebec@AmiiThinks@etsmtl