What can aviation safety and formal verification teach us about AI?
SAFE co-directors Clark Barrett and Mykel Kochenderfer joined @ycombinator to discuss rigorous approaches to building safer, more reliable AI systems.
Great conversation!
https://t.co/fhBo7QwBFY
This week’s Paper Club is all about AI safety. Not the headlines, but the science.
AI safety has been a research field for decades, with its own conferences, methods, and a track record in systems like aircraft collision avoidance, where the standard is one catastrophic failure per billion flight hours.
We'll hear from @ClarkBarrett7 and Mykel Kochenderfer (@aiprof_mykel), Stanford professors and co-directors of the Stanford Center for AI Safety.
Together with @FrancoisChauba1, they break down the OpenAI–Hugging Face incident, how formal verification can mathematically prove properties of code, how aircraft safety techniques are being adapted to language models, and why AI may need its own NTSB.
00:00 - Science fiction vs. science fact
04:32 - Engineering problem, or P(doom)
06:04 - What actually happened at Hugging Face
07:53 - Where "10% in 10 years" comes from
11:21 - The real risk: open weights in the wrong hands
17:25 - Clark Barrett: when AI met automated reasoning
20:35 - CSLib: proving code correct in Lean
24:32 - From English spec to verified code in one click
27:55 - Mykel Kochenderfer: how do we know a system is safe
32:11 - Adaptive stress testing, from aircraft to LLMs
36:57 - Verifying neural networks
40:30 - Runtime monitoring and BetterBench
43:53 - Panel: reacting to the past three weeks
45:55 - An NTSB for AI
52:18 - Is cybersecurity solvable in five years
55:00 - If you were CISO of Bank of America
1:03:06 - The Swiss cheese model
1:05:43 - Audience Q&A
@ycombinator Great to see our co-directors Clark Barrett and Mykel Kochenderfer bringing the science of AI safety to YC’s Paper Club. Thanks for having us!
📄 New research from SAFE-affiliated faculty Somil Bansal and collaborators!
Introducing TRUST, a framework for detecting and correcting flawed reasoning in vision-language-action models: https://t.co/KilDpPOFIA.
🗞️ SAFE featured in @Forbes!
Thank you to Lance Eliot for covering our 2026 Annual Meeting and highlighting discussions on AI agents, risks, and safeguards – read the full article here:
https://t.co/CRJcfe11r3
A huge thank you to our speakers, attendees, organizing team, and to @ValsAI and Alice Labs for supporting the event.
If you couldn’t make it this time, we hope to welcome you at the next SAFE Annual Meeting! 💚
#AISafety#Stanford
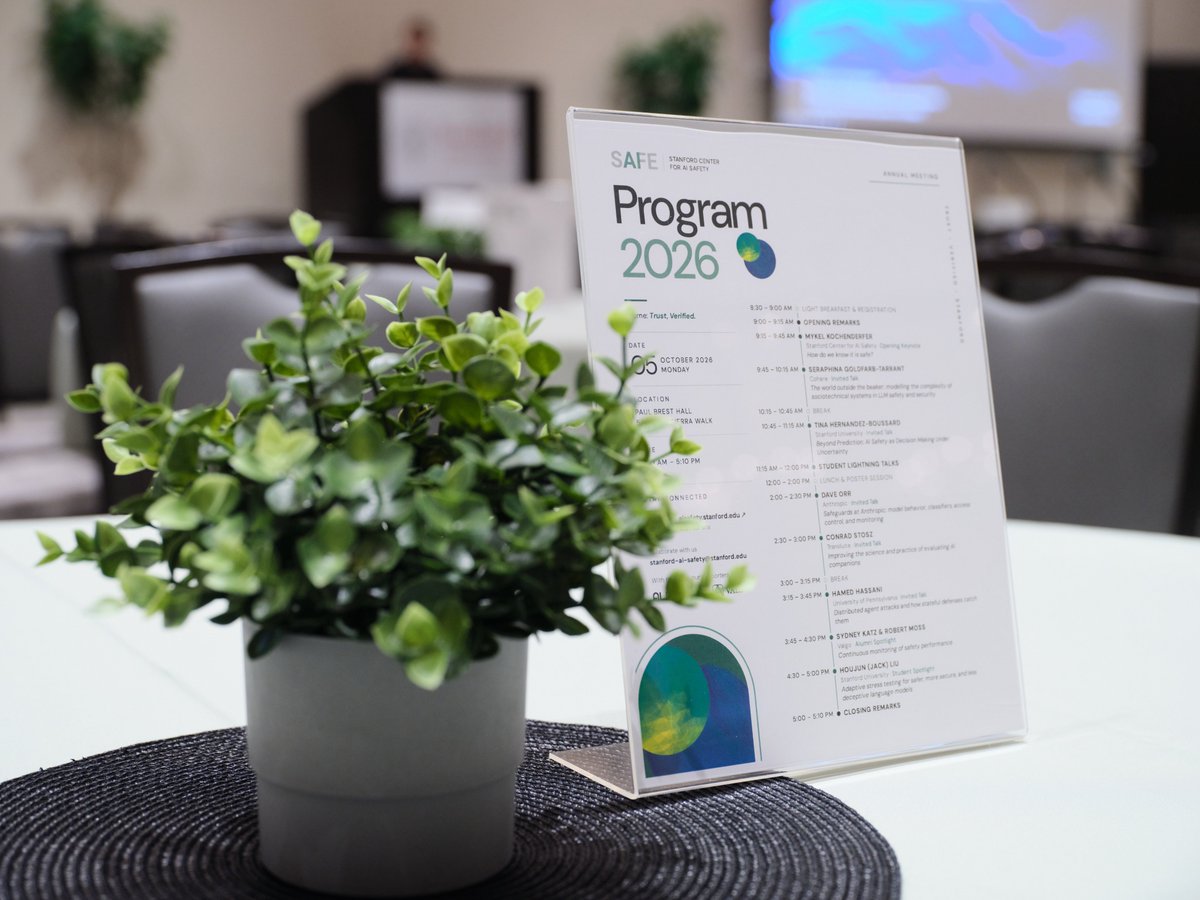
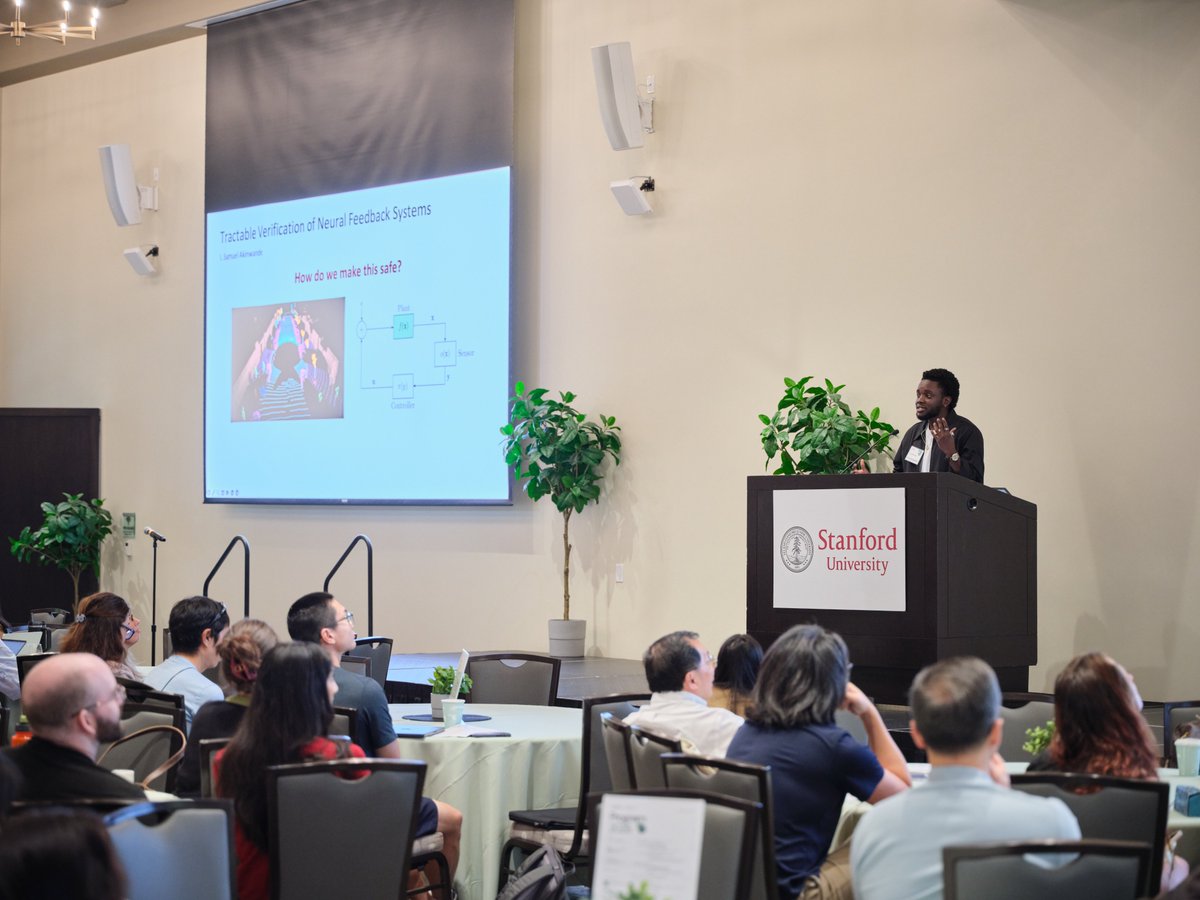
Yesterday, @StanfordSAFE hosted our 2026 Annual Meeting: Trust, Verified! 🤝
Researchers, industry leaders, and students came together to explore what it takes to build AI systems we can rely on.
🧵
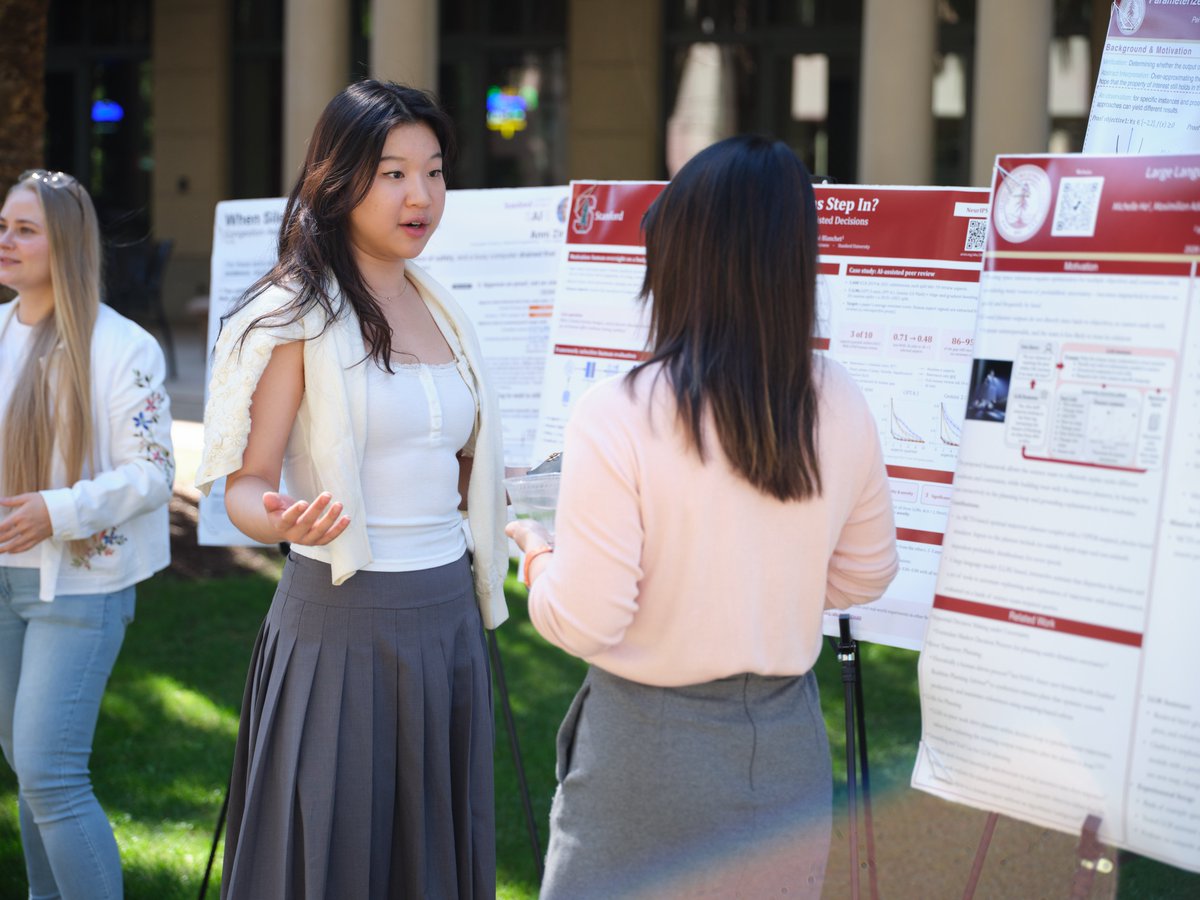
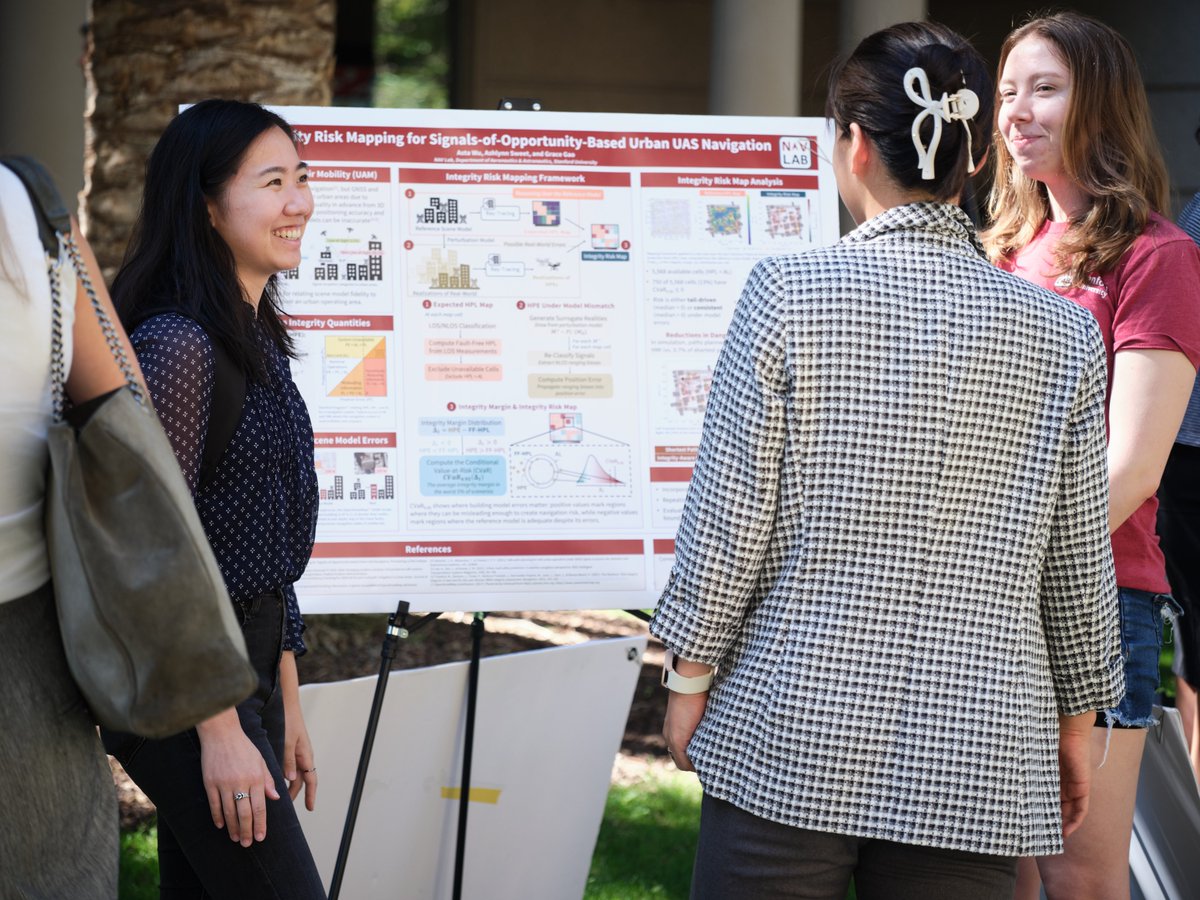
One of our favorite parts of the was the student research! 🎓
Through lightning talks and a poster session, Stanford graduate students shared their incredible work across AI safety, reliability, robustness, verification, human-AI interaction, and trustworthy autonomy.