We improved Grok's template following, self-verification, and implicit intent understanding for your most complex long-horizon office work. Give it a try and let us know what you think!
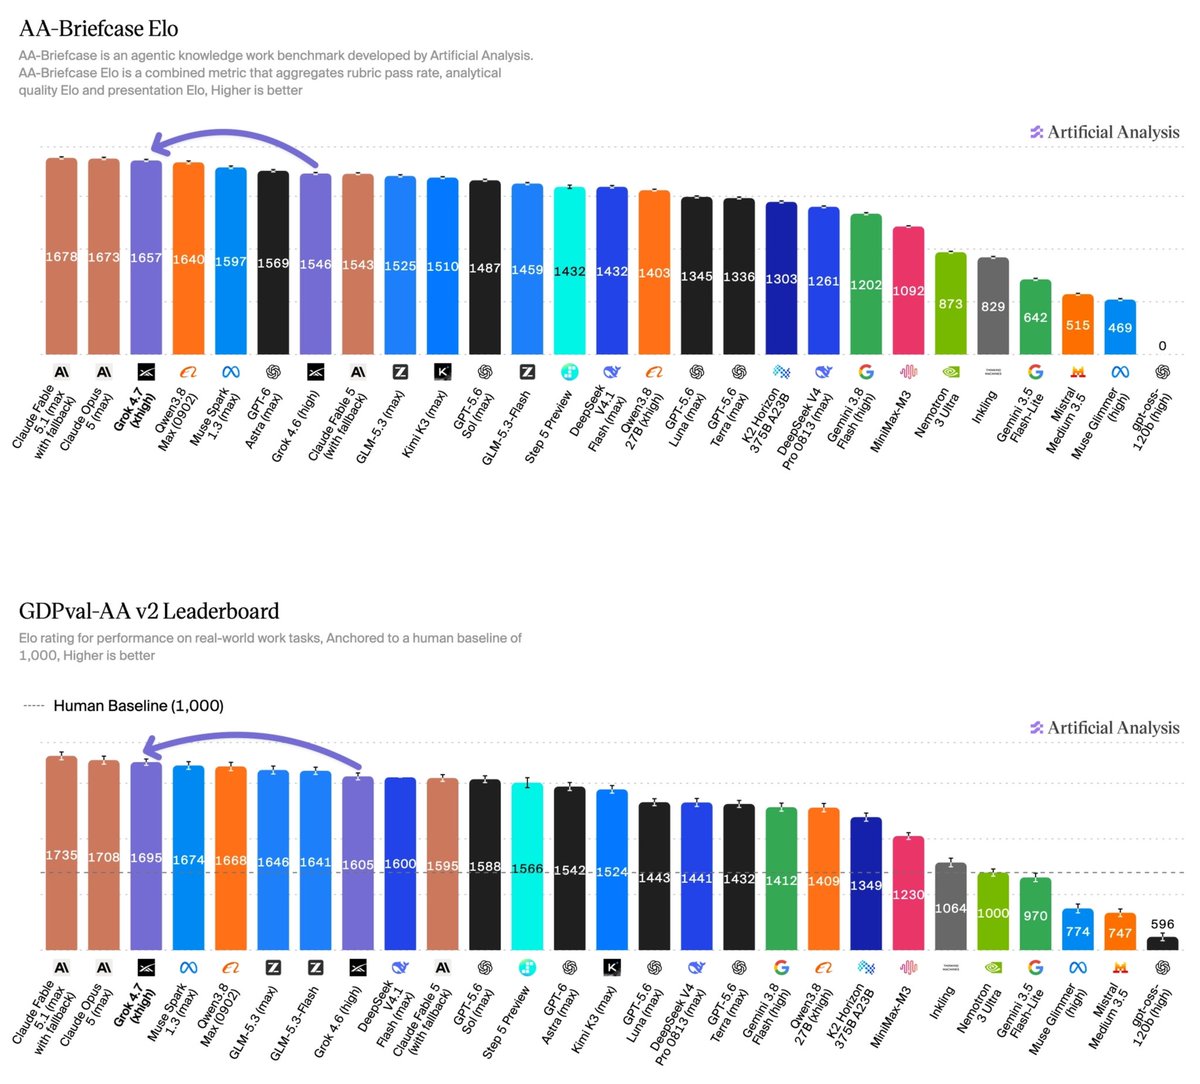
Grok 4.7 joins the frontier on agentic knowledge work tasks. On AA-Briefcase, which evaluates models on realistic professional work tasks, Grok 4.7 scores 1657 Elo, up 111 from Grok 4.6 (high) and placing it just behind Claude Opus 5 and Claude Fable 5.1.
Grok 4.7's improvement is led by analytical quality: it scores 1994 Elo for analytical quality and 1499 for presentation quality, compared with 1690 and 1519 respectively for Grok 4.6 (high). AA-Briefcase also checks whether submissions meet each task’s requirements, from completing the analysis to producing the requested deliverables.
On GDPval-AA, Grok 4.7 scores 1695 Elo, compared with 1605 for Grok 4.6 (high). These tasks require models to produce practical work products such as documents, spreadsheets and slides.
try grok bot for knowledge work tasks! e.g. make your marketing deck, clean up your emails, organize your spending into spreadsheets, draft your weekly reports, and much more!
I don’t think people appreciate what it took to ship grok 4.5/4.6 It took literal blood sweat and tears. I don’t think this rate of progress would be possible anywhere else without @elonmusk and @aman_madaan