@metapodcast_net@juliandorey@NPCollapse "Coordination this hard has been solved before" Yes. Yes. Yes. This needs to be repeated everywhere. It is doable. And it's not too late but it will be soon.
im sorry wtf i feel like im going insane. This is a cool blog and exciting interp stuff (good job Nick!) but i think it's very suspicious we have a bunch of openai people hyping it up as the greatest AI advancement this decade. I think I know why this is happening but I don't want to speculate on the timeline too much. But in general, please update your priors responsibly people -- alignment (and even interp) is FAR from solved. This is not the ok signal to accelerate RSI tomorrow
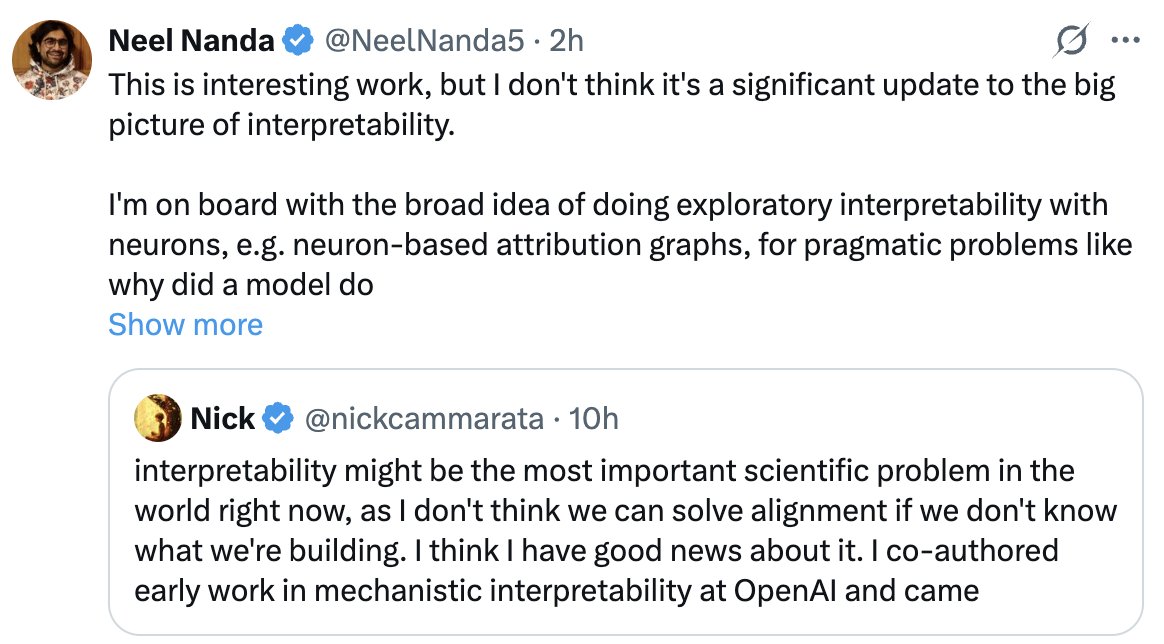
Is today's interpretability "breakthrough" a big deal?
No, says Google's interpretability lead.
Imo it's getting blown WAY out of proportion because the situation is so grim, and people are desperate for any good news
Eliezer says it's "sheer naivete":
"You having built the screwdriver so you can *start* looking at things [inside a computer] is not as much progress toward the end goal as you seem to believe.
It's like saying that neuroscience is gonna be solved as soon as you figure out how to look at a neuron with a microscope.
It reads as sheer naivete about how much work there is to do, because you don't concretely know about any of the things you need to figure out.
This attitude of yours does not inspire confidence."
Btw, Eliezer absolutely *does* update his views from time to time on good news. This just isn't one of those situations.
it is dangerous and unwise to assert that “ambitious interp is almost solved” unless you are ridiculously confident in it. we are in a fragile moment where the world is actually taking alignment seriously. in making such claims you risk ruining this progress.
@Aging_Scientist@jankulveit With recursive self improvement, AI intelligence will increase at an exponential rate. The time it takes for AI to go from solving self driving to having the ability to kill all of humanity will likely be very short.
a few brief reactions to this work:
-obviously positive update overall, @nickcammarata seems like a remarkable person and thinker, and @GoodfireAI will probably be causally upstream of the world eventually being saved
-the most promising thing about this in my opinion is not even anything about MLP neurons or "cleanness", but rather that frontier agentic systems (paired, for now, with talented humans) can rapidly overturn stale assumptions and can cheaply do needle-moving interpretability work at incredible scale (again, thanks to folks like @GoodfireAI who are almost-single-handedly enabling this for anyone doing this work outside of a major lab)
-some of the second-hand hype surrounding this work seems badly miscalibrated. seems more like "very promising early signal, let's see how it scales" than "pack it up, mech interp is solved." I get how hungry people are for hope, but "making AI go well" is not the class of thing that any one paper or project is going to solve
-even the most optimistic pace of mech interp progress won't automatically address many of the deepest and most important problems we face, like how to sustainably coexist with (or rationally be able to trust) these systems in the long-term. Understanding how these systems function internally is necessary but not sufficient for navigating towards robustly good futures (any more than solving human neuroscience would automatically lead to world peace)
15/ My frustration with this is that I think it will leave readers with the impression that a central idea in interp rested on a mistake and has now been overturned. I don't think the evidence presented supports that even if some of the findings turn out to be valuable.
@pli_cachete in retrospect I’m not sure why I posted that thread! I knew this was coming out soon. maybe I hadn’t fully processed it. we are still living in extreme danger and probably shouldn’t race into rsi but could honestly be a double digit reduction in existential risk
I am urging Anthropic to pause its planned IPO until it addresses AI safety, governance and accountability. In a letter to @AnthropicAI CEO Dario Amodei, I raised concerns about AI safety. Anthropic itself has said that AI poses unprecedented risks to humanity. Thanks to @CNBC Squawk Box for the opportunity to voice my alarm at technology with no guardrails or federal oversight.
Watch the full interview here: https://t.co/TECAz6B2yx
@aashiq@tszzl I agree somewhat, but understanding individual models may well lead to understanding swarm behavior.
Also, I think this will help us understand just how good LLM alignment has really been.
@tszzl@7heLich My hope is that this increased understand of what's happening inside the models will help a slowdown come, as we start to see the extent of how misaligned existing models are.
Anthropic reportedly talking with investors about using Claude to design custom AI chips and that they expect a $110 billion annual revenue run rate by the end of the year.
Many people conclude that because they are still going so pedal to the medal on this sort of racing and normal IPO business stuff they must not believe in the severe risks they are warning about but unfortunately I don't believe thats true - from all indications I've seen they (or at least many people at the org) do believe in the catastrophic risks but don't want to take costly precautions that could slow their explosive growth unilaterally and normal business incentives create a massive amount of momentum to continue moving forward at full speed regardless of any misgivings.
But there is no question in my mind that walking both of these lines at the same time undermines the credibility of their warnings because its not how most people would imagine themselves behaving if they were in Anthropic's position of believing their tech might cause a massive catastrophe.
I'm joining METR to work on more investigations like our Hugging Face report.
Currently, tons of even basic information about AI development that's highly relevant to catastrophic risk isn't public. I used to be more skeptical of the value of public info, but recent events have changed my mind.
Getting verified information about what's going on inside AI companies seems particularly urgent now. The limited public evidence we have seems consistent with the possibility that imminent recursive self-improvement could massively accelerate capabilities progress, which could then potentially yield extremely superhuman general capabilities within 6 months or a year. If this occurred, there would be a correspondingly large risk of worst-case outcomes. This uncertainty about extreme outcomes could be substantially resolved with more verified public information: we could either build more consensus about near-term risk or learn that such extreme outcomes are less likely in the near term.
Beyond AI capabilities and takeoff, the state of public evidence is also highly limited for alignment, security, control, and risk-relevant internal processes at AI companies. This makes it hard to determine exactly how well or poorly these key areas will go in the near future. (METR plans to focus, at least initially, on just capabilities/takeoff, alignment, and control; I hope other groups cover security, internal processes, and other important areas.)
While I'm no longer working at Redwood, I think the work they are doing is very important; I'm excited about Redwood's ongoing contributions to R&D on technical mitigations and better public interpretation of risk-relevant evidence.
You shouldn’t have to trust METR because AI companies should just publish risk-relevant data themselves. Until then, our job is to make important evidence open so that the public can come to their own conclusions.
We are ready to work with frontier labs to make this happen.
RSI has become a buzzword that conveys little about the actual uplift from AI. Google should publish a level of automation chart like Anthropic did, or a task complexity vs success rate chart like OpenAI's.