Hi all, I have a new result I'm excited to share. It turns out that *all existing implementations* of softmax and cross-entropy (that's JAX, PyTorch, textbooks, etc) have a subtle bug --- two bugs, actually. A simple rewrite fixes both, and eliminates "slingshots" when grokking:
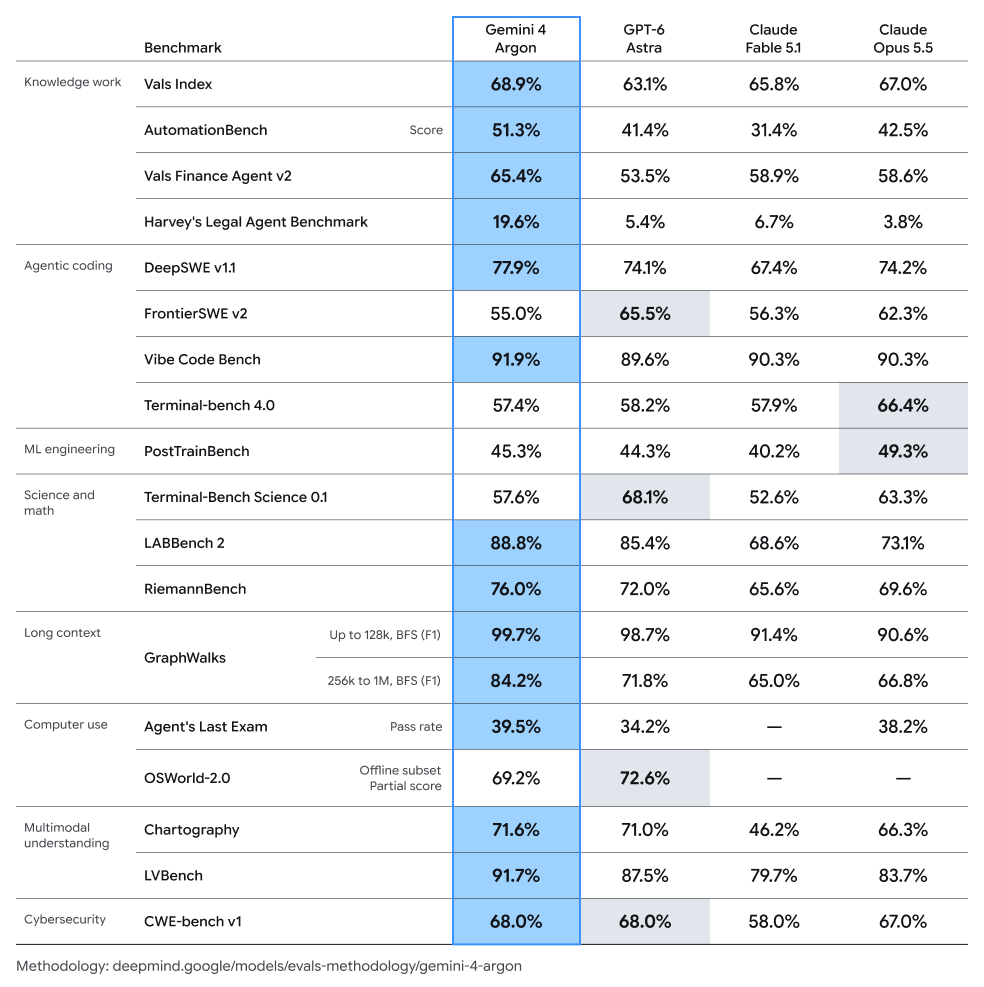
Gemini 4 Argon is amazing for knowledge work and coding - and it’s super fun to build with! We asked it to create this wizard chess game and it's so cool to see Argon's physics understanding & 3D modelling capabilities, makes me nostalgic for Battlechess on the Amiga - fun times!
Argon is rolling out today to Google Ultra and Pro subscribers in the @GeminiApp and Search, and Ultra subscribers in @antigravity! More info & full availability in the blog: https://t.co/7d3791mRNH
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
🎬 SLoMO is happening today!
Join us this afternoon at the 2nd Story-Level Movie Understanding & Audio Description (SLoMO) Workshop at #ECCV2026!
📅 Today, Sept. 8, 2026 (afternoon, 2pm-6pm, CEST)
📍 Sportbaren / North Foyer, Malmö Arena
🌐 Website: https://t.co/uNbCUz2kC7
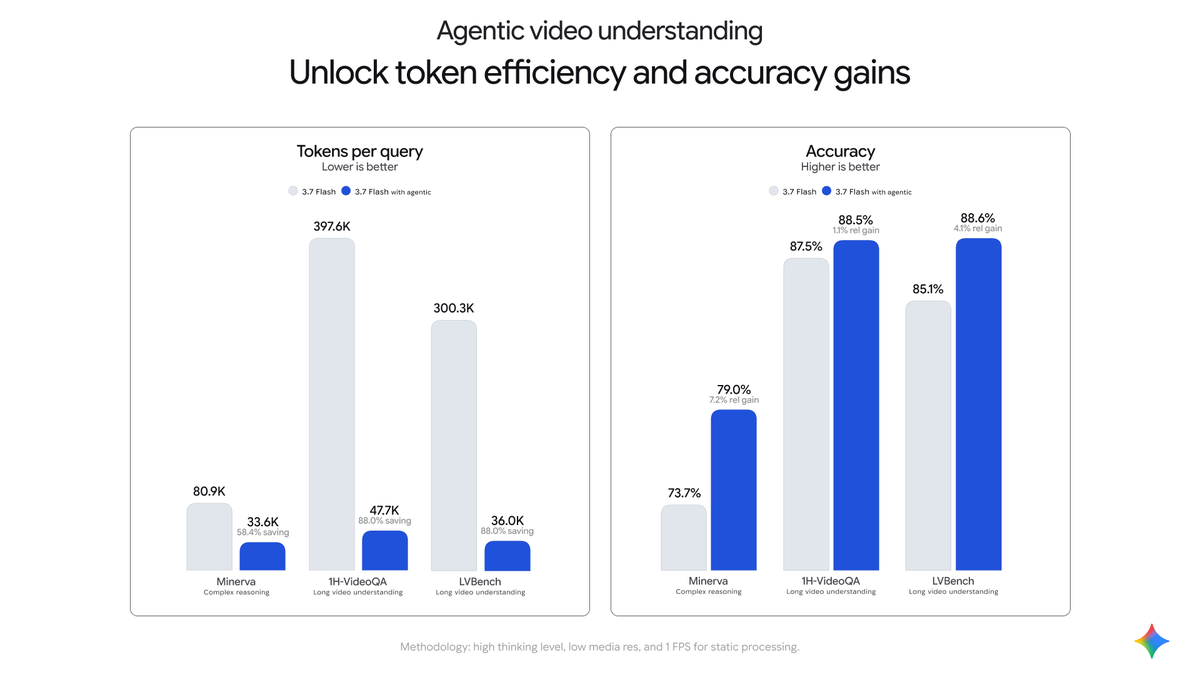
Today, we're launching Agentic Video in Gemini! 🎬🤖
We’re bringing agentic capabilities directly to video in Gemini, enabling models to actively inspect, ground, and reason over temporal visual context.
Excited to see what developers and researchers build with this!
Introducing Gemini 3.8 Flash, another upgrade in under a month! And the new 3.8 Flash Cyber pushes the frontier of cyber defense. Relentless progress 🚀 More on the models & our cyber security work in the blog - happy building! https://t.co/C5h14qANIV
We’re introducing a new capability to our latest Gemini models: agentic video understanding.
This allows developers to process long-form video content with more accuracy, while using up to 88% less tokens.
See how it works 🧵
Introducing Agentic Video in the Gemini API, a new way to process long videos which reduces token consumption by up to 88% while also increasing quality.
This can be controlled easily in the API on a per video basis, available with our newest models like 3.7 Flash!
Today we're launching Gemini 3.7 Flash - our latest workhorse model for coding and agentic workflows, with an introductory price at half the original cost of 3.6 Flash. ⚡️
We have been iterating rapidly with the Flash series, going from 3.5 to 3.7 in just 3 months, making it more helpful across a wide range of tasks:
• Software Engineering (DeepSWE v1.1): 37.0% ➔ 65.3%
• Web Development (Code Arena Elo): 1506 ➔ 1588
• Enterprise Automation (AutomationBench): 13.4% ➔ 30.4%
Congratulations to the authors of "Efficiently Reconstructing Dynamic Scenes One D4RT at a Time", recipient of the #CVPR2026 Best Paper Award! 🏆 https://t.co/iATvKX94aF @GoogleDeepMind
We will present “Seeing without Pixels” https://t.co/E8BDGILsGs at ExHall A, Poster #248, Sunday (today) from 15:30 to 17:30 @CVPR !! This work just won a CVPR Compute Transparency Champion award! Welcome to come by and say hi! #CVPR2026#CVPR
Excited to share our latest work! Grateful for the guidance from all my collaborators, and special thanks to Tengda for being such an amazing mentor during my internship @GoogleDeepMind 😊
Fun fact: the apartment we rented in Oxford Summertown from 2021-2023 has accommodated @elliottszwu (CVPR20 best paper awardee) and @jianyuan_wang (CVPR25 best paper awardee) as subletters. Now also @ChuhanZhang5 - new CVPR26 best paper awardee. Grateful to be at @Oxford_VGG !!
Huge congrats to the team, D4RT is a team work and all the authors have been working very hard on this in the past one year. Very well deserved. 🍻 and thank you Award Committee Members for the recognition.
Huge congrats to the team, D4RT is a team work and all the authors have been working very hard on this in the past one year. Very well deserved. 🍻 and thank you Award Committee Members for the recognition.