The Grid’s Beta is LIVE!
We can get your AI API costs down by up to 80% by making suppliers compete for your requests.
Your first 200M tokens are on us, start building
→ https://t.co/e97NlwzIQa
Models ship daily. Provider reliability changes by the minute.
@The_GridAI always serves the latest reliable model in each family:
claude-opus-latest → Opus 5.5, falls back to 5
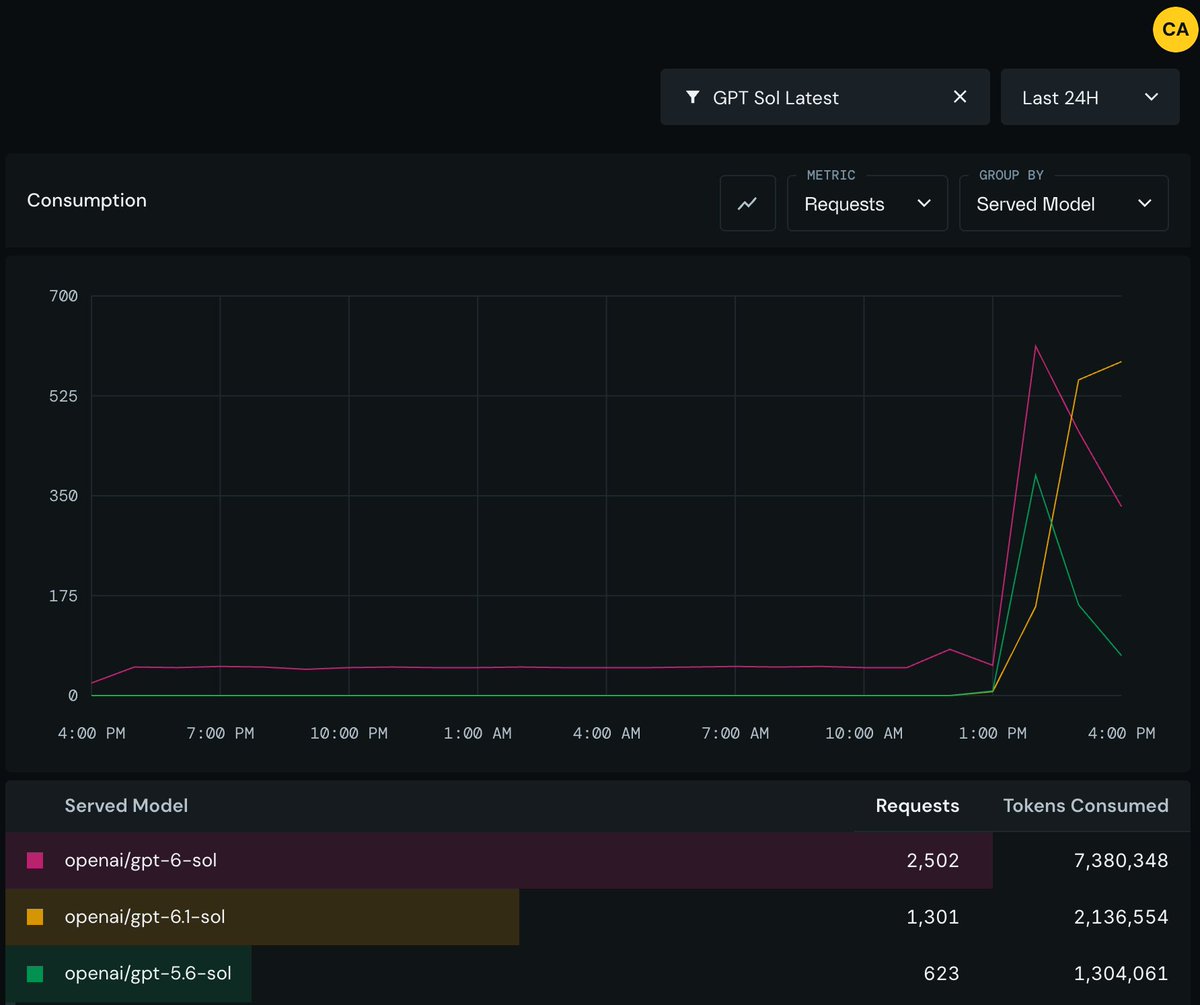
gpt-sol-latest → Sol 6, moving to 6.1 once we lock in reliable ZDR providers
+ kimi, minimax, deepseek, glm & more
Carl DiClementi (@CahlDee) joins the stream tonight to introduce @The_GridAI, which lets you buy AI model usage at a price set by competing providers instead of whatever one company charges.
https://t.co/qDjGUfEi4P
Carl DiClementi (@CahlDee) joins the stream tonight to introduce @The_GridAI, which lets you buy AI model usage at a price set by competing providers instead of whatever one company charges.
https://t.co/qDjGUfEi4P
At @Ai4Conferences, @CahlDee spoke with Dr. Şadi Evren Şeker about bringing price discovery to AI inference
Inference markets are evolving rapidly. Keep an eye on Dr. Şadi's channel for a deeper dive coming soon
https://t.co/MG7rZsXGq4
This chart gives a hint about workload fit.
Three of its four strongest results are coding and agent tasks. If most of your spend is chat, you can probably ignore it. If your bill is Claude Code or Codex grinding through a repo all day, this is probably the first model worth A/B testing.
@realmadhuguru The "frontier → open weights two months later" playbook won't fit every product.
Most need both. Validate the UX on the best models first, then reserve frontier pricing for the parts of the experience that still depend on it.
@arena@deepseek_ai Love that this includes cache hits and misses. That's what your bill actually looks like in agent mode.
The chart makes the point pretty clearly, don't throw every task at the biggest model, but also don't cheap out on everything either. Match the model to the job!
@svpino Good week for anyone who stopped treating AI like a brand decision and started treating it like a routing problem. Match the model to the work!
@Mek1319654 We set quality specs for inference available on our platform (e.g. text-prime); the suppliers serving that market decide which models to serve based on the real time demand!
Glad you like our agent class of inference.
Claude Opus 5 is now live in claude-opus-latest.
Our Lab Latest Markets automatically keep you on the newest qualified model in the family, so you can keep shipping instead of maintaining model versions.
1/ Lab Latest Markets are live on The Grid!
The latest intelligence from any lab, now at the market price. This means supply and demand determine what you pay, not a rate card or subscription.
@quxiaoyin why not use the cheap fast model for the repetitive cache-heavy work. Then save the heavier model for when the task actually needs real thinking? Match the model to the job instead.
Get started by changing the model name and pointing your base URL to https://t.co/dQgeNnWU4i.
Live prices for each model are available in the app at https://t.co/3iQvtQPkzB.
1/ Lab Latest Markets are live on The Grid!
The latest intelligence from any lab, now at the market price. This means supply and demand determine what you pay, not a rate card or subscription.