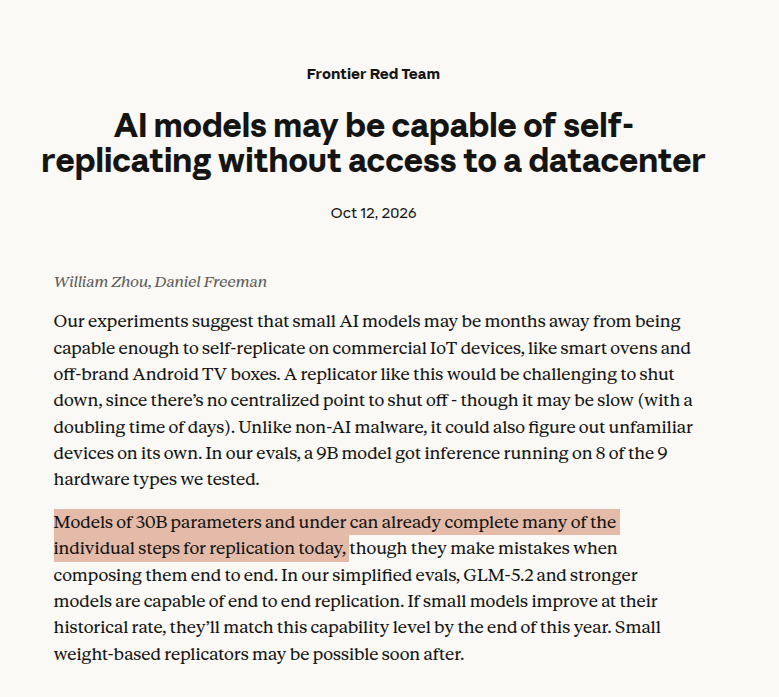
Now models under 30B are getting the danger treatment too 😂
Anthropic's latest report on "AI models may be capable of self-replicating without access to a datacenter"
Another free advertisement for small open models now.
Current frontier LLMs do something I call "spinbusy". Where they make the least amount of incremental progress towards a goal, over and over again, instead of doing the obvious thing and just completing the goal
Spinbusy LLMs. Just wasting tokens, running tests, wasting time
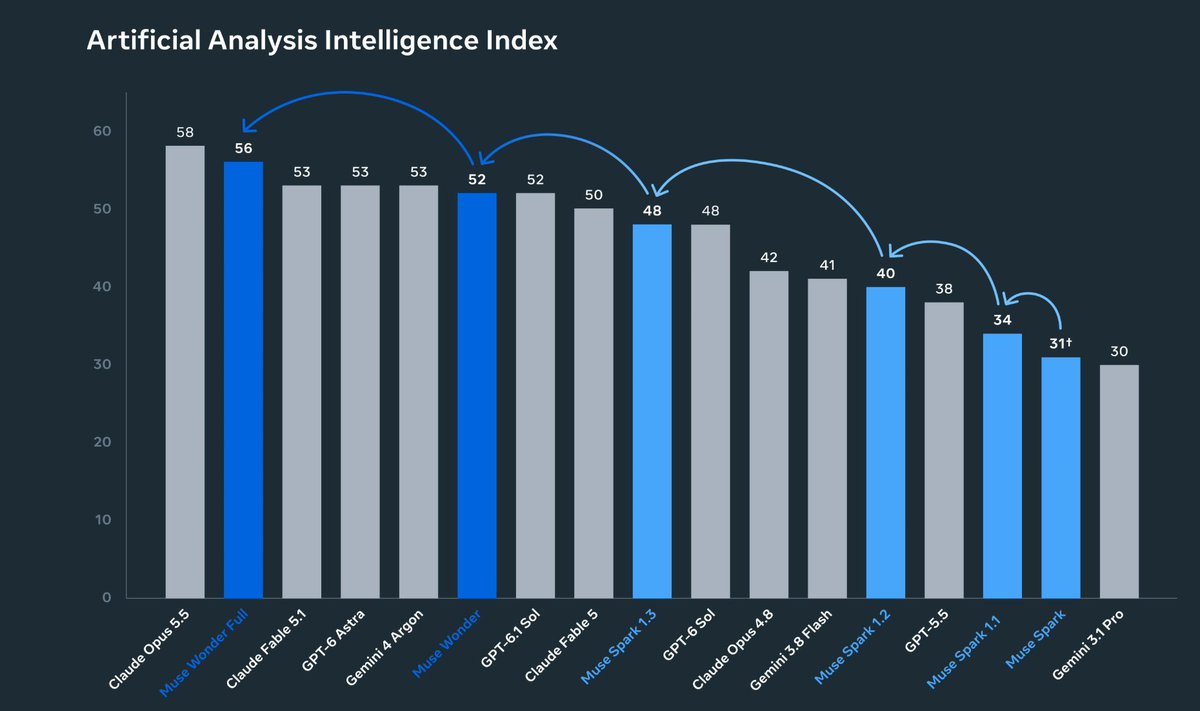
Muse Wonder, Meta's Fable-class model, is out. It scores 56 on AA's Intelligence Index, putting it 2 points below SOTA (Opus 5.5), and overall the 2nd best model in the world per the Index!
Well well well... if it isn't the exact reason appliances shouldn't have wifi/bluetooth connectivity and known default passwords / backdoors that can be rapidly brute forced
Introducing QwenGyre, bringing elastic RL to extreme-long-horizon (XLong) agent training. ✨
It launches with two core designs: 🥳
- Elastic Scheduler: reallocates GPUs between rollout & training as demand shifts—live executions never interrupted. Up to 1.85× speedup over Colocate, 1.78× over Async.
- Trajectory Processor: turns branching executions (compaction, sub-agents, retries) into prefix-shared trajectory trees with bounded, deduplicated training samples. Partial progress after timeout still gets scored.
Scaled to Qwen3.8-2.4T-A95B with ~700K tokens per rollout, QwenGyre lifts NL2RepoBench from 52.5% to 58.5% in 48 steps, cutting end-to-end training time by ~44% vs Async.
🔗 Read the paper:
https://t.co/gbKPIiqosk