Billionaire Michael Milken joked “if a US company replaces the US-born CEO with a CEO born in India, I buy the stock”
But he reveals he hasn’t backtested the idea.
So we did.
In the last 15yrs, that would’ve 50x’d your money: 7.5x more $$ and >2x IRR vs S&P500: 30% vs 14%!
Decades ago, when I began my career in the auto industry, it was our Indian delegations that would make the pilgrimage to International Auto shows to photograph & study the advanced cars made overseas.
At the recent Bharat Mobility Show in Delhi, you can imagine my emotions when seeing Japanese & Korean visitors poring over our new Electric Origin SUVs…
🎉We're thrilled to announce 3 amazing #PLAMADISO talks that you simply can't miss🚀
🗓️ Dec 6: @flyverbom
🗓️ Dec 7: Scott Shenker
🗓️ Dec 14: @G_Massarotto
🌟 Get ready for engaging discussions that promise to enlighten & inspire!💡
🔗 Register NOW here: https://t.co/09kYfoWXKz
Chandrayaan-3 Mission:
'India🇮🇳,
I reached my destination
and you too!'
: Chandrayaan-3
Chandrayaan-3 has successfully
soft-landed on the moon 🌖!.
Congratulations, India🇮🇳!
#Chandrayaan_3#Ch3
Python is removing the GIL.
The GIL (Global Interpreter Lock) prevents you from running multi-threaded code.
That makes ML code, in particular, really hard to write in pure Python.
Here's what it takes to remove the GIL:
GPT-4 is getting worse over time, not better.
Many people have reported noticing a significant degradation in the quality of the model responses, but so far, it was all anecdotal.
But now we know.
At least one study shows how the June version of GPT-4 is objectively worse than the version released in March on a few tasks.
The team evaluated the models using a dataset of 500 problems where the models had to figure out whether a given integer was prime. In March, GPT-4 answered correctly 488 of these questions. In June, it only got 12 correct answers.
From 97.6% success rate down to 2.4%!
But it gets worse!
The team used Chain-of-Thought to help the model reason:
"Is 17077 a prime number? Think step by step."
Chain-of-Thought is a popular technique that significantly improves answers. Unfortunately, the latest version of GPT-4 did not generate intermediate steps and instead answered incorrectly with a simple "No."
Code generation has also gotten worse.
The team built a dataset with 50 easy problems from LeetCode and measured how many GPT-4 answers ran without any changes.
The March version succeeded in 52% of the problems, but this dropped to a pale 10% using the model from June.
Why is this happening?
We assume that OpenAI pushes changes continuously, but we don't know how the process works and how they evaluate whether the models are improving or regressing.
Rumors suggest they are using several smaller and specialized GPT-4 models that act similarly to a large model but are less expensive to run. When a user asks a question, the system decides which model to send the query to.
Cheaper and faster, but could this new approach be the problem behind the degradation in quality?
In my opinion, this is a red flag for anyone building applications that rely on GPT-4. Having the behavior of an LLM change over time is not acceptable.
Have you noticed any issues when using GPT-4 and ChatGPT lately? Do you think these problems are overblown?
The amazing educator and researcher Jim Kurose explains the Internet in five levels. I had a blast watching him talk with the 8-year-old, and participating in the final level!
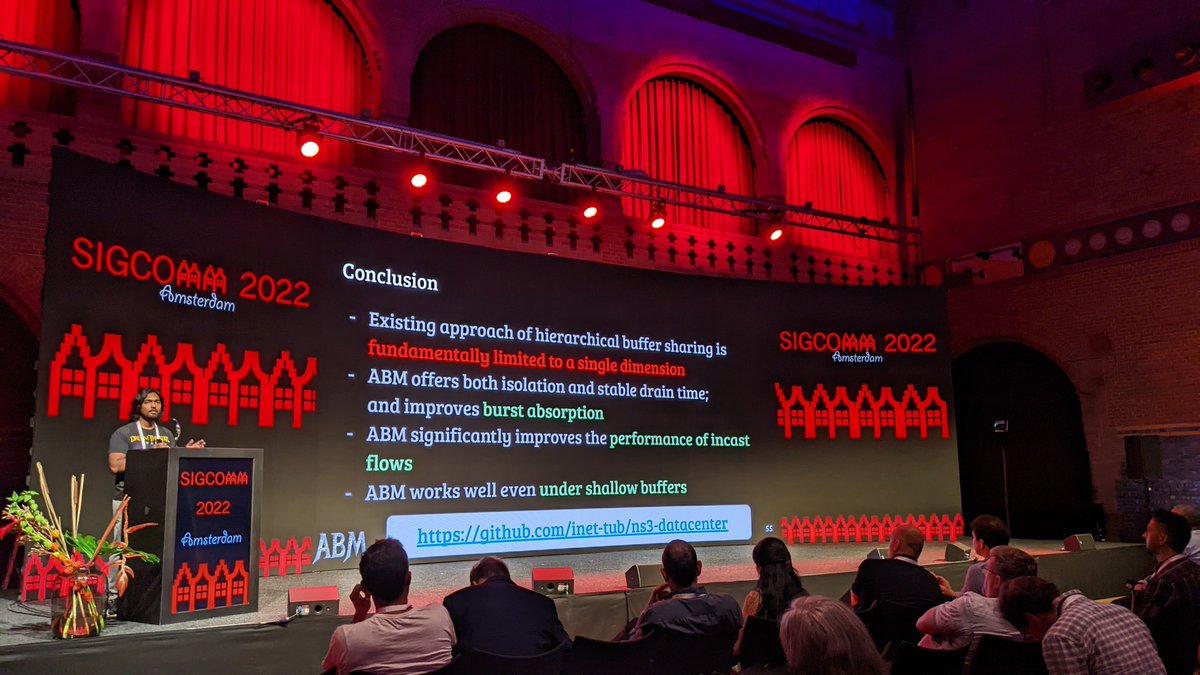
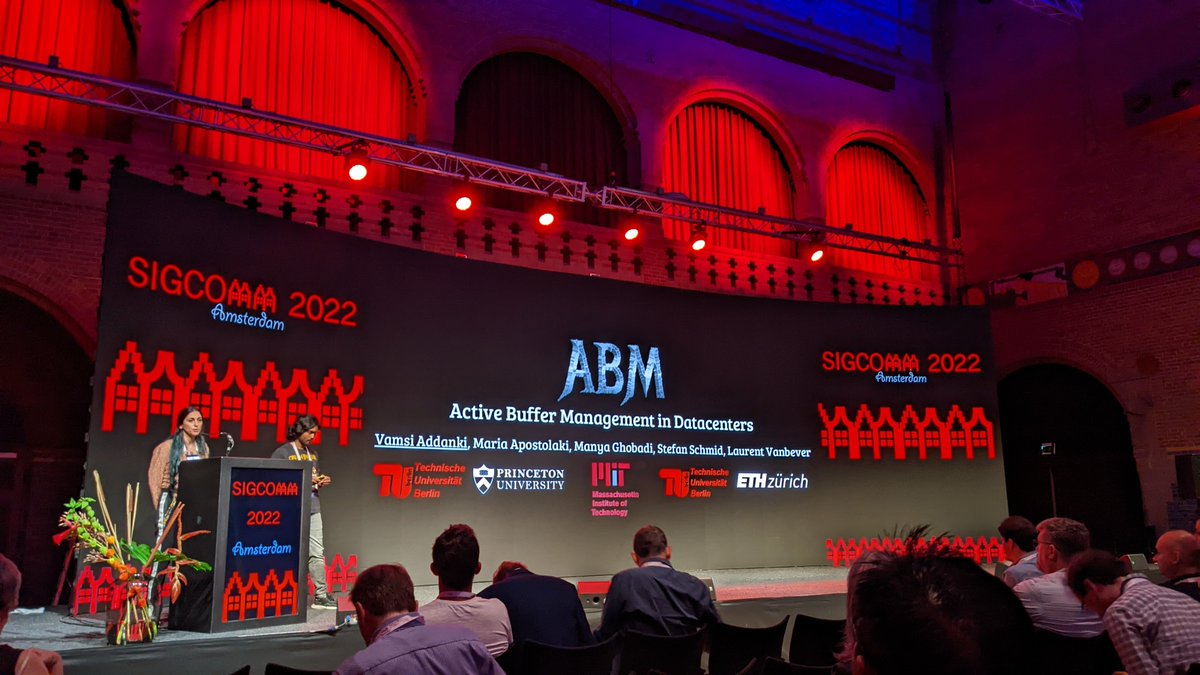
Great talk by @Vamsi_DT on active buffer management in datacenters at @ACMSIGCOMM 2022. Definitely check out their work and code at https://t.co/ka0SaWcxxP
CfP: https://t.co/yIa6KGc2Po
Abstract deadline: June 15, 2022
Page length: Short Max. 6 pages and long Max. 12 pages
Please share with your research groups and colleagues #research .
Dear Folks,
Please consider submitting your work to the ACM SOSR 2022 https://t.co/7qVnblvnoF . The ACM SIGCOMM Symposium on SDN Research (SOSR) is the premier venue for research publications on SDN, building on past years' successful SOSR and HotSDN workshops.