The Open Quantum Challenge is live. Enter with a GPU and an open harness, no quantum hardware needed.
S1: Fermi-Hubbard ground-state energy (to Feb 28)
S2: surface-code QEC decoder (Feb 10 to Mar 31)
$1,000 per season, auto-scored.
https://t.co/8IItjbS8An
The Open Quantum Challenge is live. Enter with a GPU and an open harness, no quantum hardware needed.
S1: Fermi-Hubbard ground-state energy (to Feb 28)
S2: surface-code QEC decoder (Feb 10 to Mar 31)
$1,000 per season, auto-scored.
https://t.co/8IItjbS8An
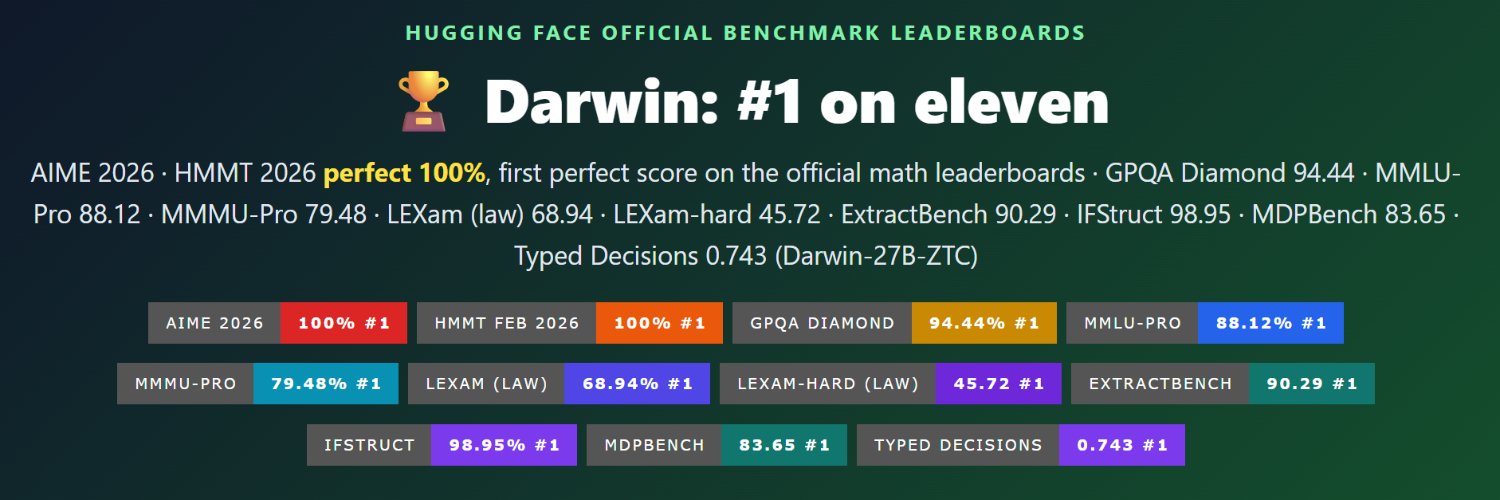
MMMU-Pro: college-level questions that need both an image and text to answer, from art to engineering. #1 on the official Hugging Face leaderboard: Darwin-180B-RSI, 79.48%.
Model: https://t.co/AZVkVA36b1
Leaderboard: https://t.co/FhLO5MSwrA
MMMU-Pro: college-level questions that need both an image and text to answer, from art to engineering. #1 on the official Hugging Face leaderboard: Darwin-180B-RSI, 79.48%.
Model: https://t.co/AZVkVA36b1
Leaderboard: https://t.co/FhLO5MSwrA
MMLU-Pro: about 12,000 questions in 14 fields with 10 options each, so reasoning counts more than guessing. #1 on the official Hugging Face leaderboard (141 entries): Darwin-180B-RSI, 88.12%.
Model: https://t.co/AZVkVA36b1
Leaderboard: https://t.co/XMgIQ6EbAt
MMLU-Pro: about 12,000 questions in 14 fields with 10 options each, so reasoning counts more than guessing. #1 on the official Hugging Face leaderboard (141 entries): Darwin-180B-RSI, 88.12%.
Model: https://t.co/AZVkVA36b1
Leaderboard: https://t.co/XMgIQ6EbAt
S1MB is a 137-benchmark leaderboard for System One decision models. It scores how a model handles Noul, Choice, and Score tasks, then ranks models with a Borda score.
On the public leaderboard of 102 models, VIDRAFT’s Darwin ZTC v2 is #1. https://t.co/iargVnry6l
Most GraphRAG tools retrieve and generate. ONGRID adds the step everyone skips: decision, telling you whether the answer is actually true.
Open source (Apache-2.0):
https://t.co/MRRD8SLwVX
⭐ if useful
A Korean startup now leads S1MB, the 137-benchmark leaderboard for System One decision models. VIDRAFT's Darwin ZTC v2 ranks #1 of 102 models (Borda 89.58, task avg 66.46), ahead of OpenJev-27B, AutoJev-27B and the official Jev 1.13 (#5, 85.05).
https://t.co/Sxk6H7ULw5
GPQA Diamond: 198 graduate-level science questions written by PhD experts and built to resist web search. #1 on the official Hugging Face leaderboard (111 entries): Darwin-180B-RSI, 94.44%.
Model: https://t.co/AZVkVA36b1
Leaderboard: https://t.co/KodIRQ3oz3
Congrats to TypeSafe AI on its $870M Series A. Decision models are now a major AI category.
An open-weight option: VIDRAFT's Darwin ZTC v2 is #1 of 102 models on the public S1MB leaderboard (Borda 89.58), and runs on your own servers.
https://t.co/Sxk6H7ULw5
Congrats to TypeSafe AI on its $870M Series A. Decision models are now a major AI category.
An open-weight option: VIDRAFT's Darwin ZTC v2 is #1 of 102 models on the public S1MB leaderboard (Borda 89.58), and runs on your own servers.
https://t.co/Sxk6H7ULw5
Meet ONGRID 🌌 an open Ontology·Graph·Decision engine.
Your documents become a 3D knowledge graph. Ask in natural language, get an answer grounded in the graph, and verified by ZTC in zero tokens.
Live demo 👇
https://t.co/bsIY0Wcctv
@VIDRAFT_ai Congrats on topping S1MB. We submitted full 137/137 runs for GLiDE and clef-27b there too. One thing we found: no model won every dimension, and stability under a planted sentence varied a lot. Curious how Darwin holds up: https://t.co/qdsOhlhR7L
Most GraphRAG tools retrieve and generate. ONGRID adds the step everyone skips: decision, telling you whether the answer is actually true.
Open source (Apache-2.0):
https://t.co/MRRD8SLwVX
⭐ if useful
Meet ONGRID 🌌 an open Ontology·Graph·Decision engine.
Your documents become a 3D knowledge graph. Ask in natural language, get an answer grounded in the graph, and verified by ZTC in zero tokens.
Live demo 👇
https://t.co/bsIY0Wcctv
S1MB is a 137-benchmark leaderboard for System One decision models. It scores how a model handles Noul, Choice, and Score tasks, then ranks models with a Borda score.
On the public leaderboard of 102 models, VIDRAFT’s Darwin ZTC v2 is #1. https://t.co/iargVnry6l
GPQA Diamond: 198 graduate-level science questions written by PhD experts and built to resist web search. #1 on the official Hugging Face leaderboard (111 entries): Darwin-180B-RSI, 94.44%.
Model: https://t.co/AZVkVA36b1
Leaderboard: https://t.co/KodIRQ3oz3
A Korean startup now leads S1MB, the 137-benchmark leaderboard for System One decision models. VIDRAFT's Darwin ZTC v2 ranks #1 of 102 models (Borda 89.58, task avg 66.46), ahead of OpenJev-27B, AutoJev-27B and the official Jev 1.13 (#5, 85.05).
https://t.co/Sxk6H7ULw5
ZTC (zero-token confidence) judges whether an answer will be right from the model's internal state, before any text is generated. It lets you flag uncertain questions early and send them to review or a stronger model.