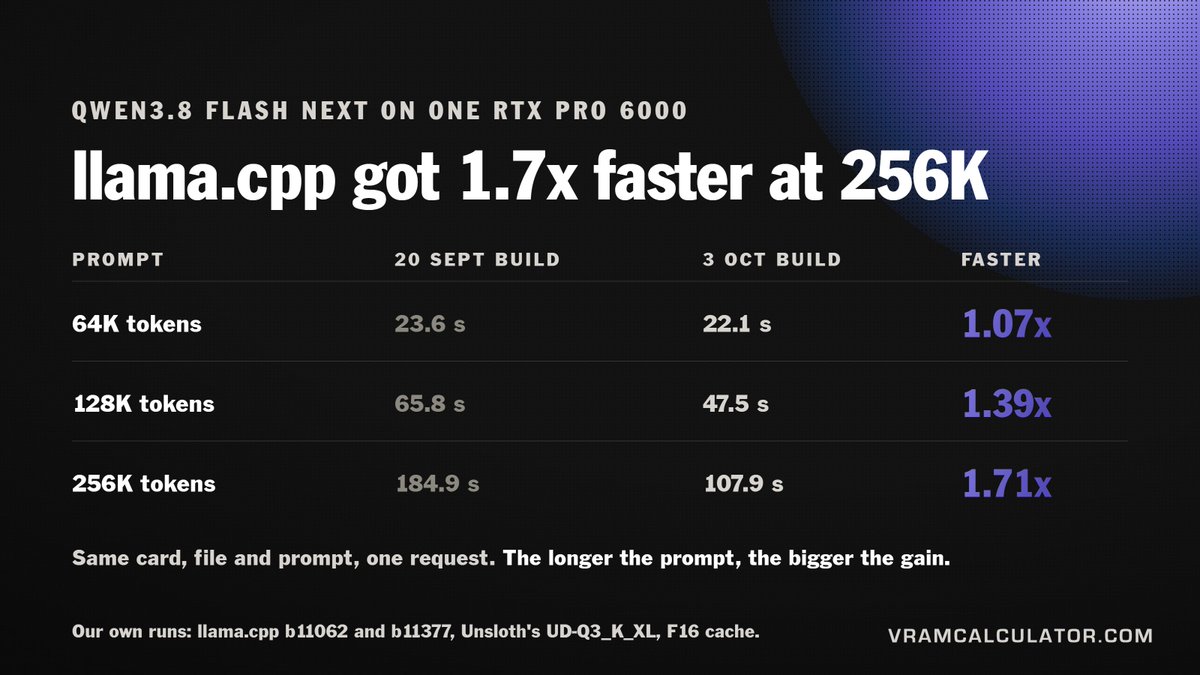
llama.cpp got 1.7x faster at long context in two weeks.
Same card, model and 256K-token prompt (Qwen 3.8 Flash Next on one RTX PRO 6000):
20 September build: 184.9 s
3 October build: 107.9 s
At 128K it is 1.39x. At 64K, almost no change. If you run long prompts, update.
@richgel999 Update: it's now in Strata itself. Version 0.1.39 runs on CPUs without AVX2, Xeon E5 v1 and v2 included, as an experimental option. No patch or fork needed: setup compiles the engine for your CPU once.
Details: https://t.co/427rnveSTU
Strata on an old DDR3 Xeon: it shipped.
Strata 0.1.39 runs on CPUs without AVX2, Xeon E5 v1 and v2 included, as an experimental option. Setup compiles the engine for your CPU once, in 10 to 20 minutes.
Two days after its creator told us it was coming. ✅
Strata on an old DDR3 Xeon: it shipped.
Strata 0.1.39 runs on CPUs without AVX2, Xeon E5 v1 and v2 included, as an experimental option. Setup compiles the engine for your CPU once, in 10 to 20 minutes.
Two days after its creator told us it was coming. ✅
Strata on an old DDR3 Xeon: it shipped.
Strata 0.1.39 runs on CPUs without AVX2, Xeon E5 v1 and v2 included, as an experimental option. Setup compiles the engine for your CPU once, in 10 to 20 minutes.
Two days after its creator told us it was coming. ✅
The fine print: only the IQ builds run on these CPUs, the CPU's share of the work is slower, and its notes say it is untested on a real old CPU.
Also new: P40, P100, GTX 10, V100 and MI50 cards, experimental too.
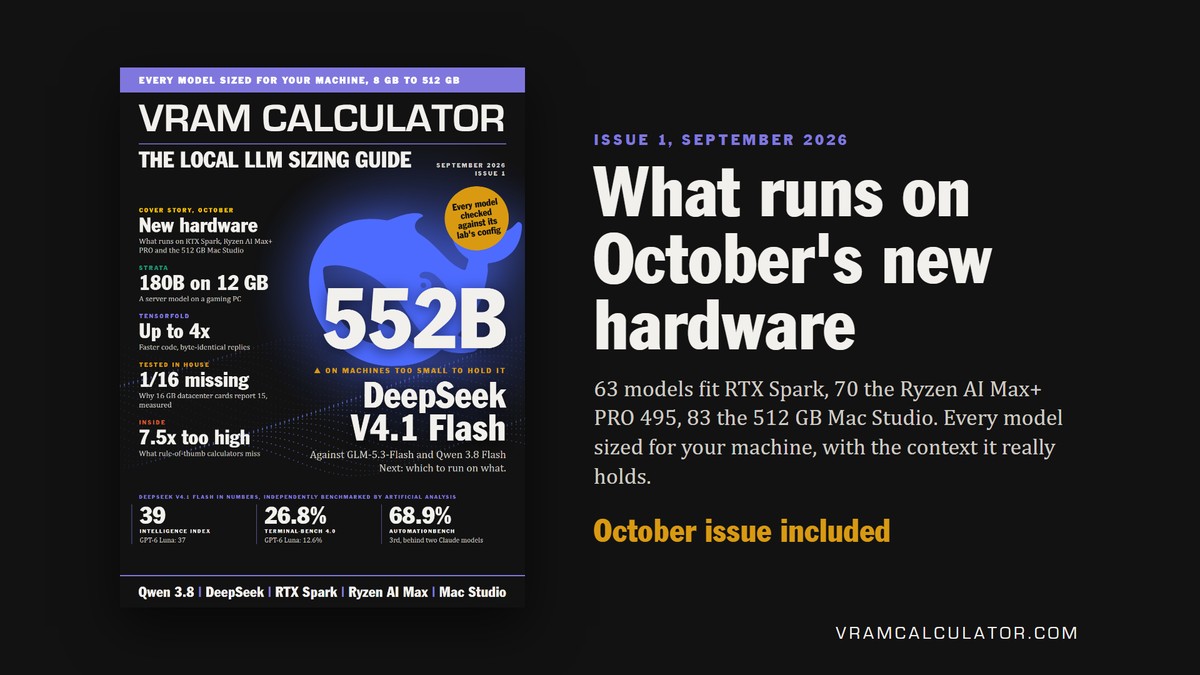
The Local LLM Sizing Guide, Issue 1: every model sized for your machine, 8 GB to 512 GB, with what runs on RTX Spark, Ryzen AI Max+ PRO and the 512 GB Mac Studio.
A monthly PDF. $9 a month, or $24.90 for Issue 1 with October included.
https://t.co/eVa8RMeEEN
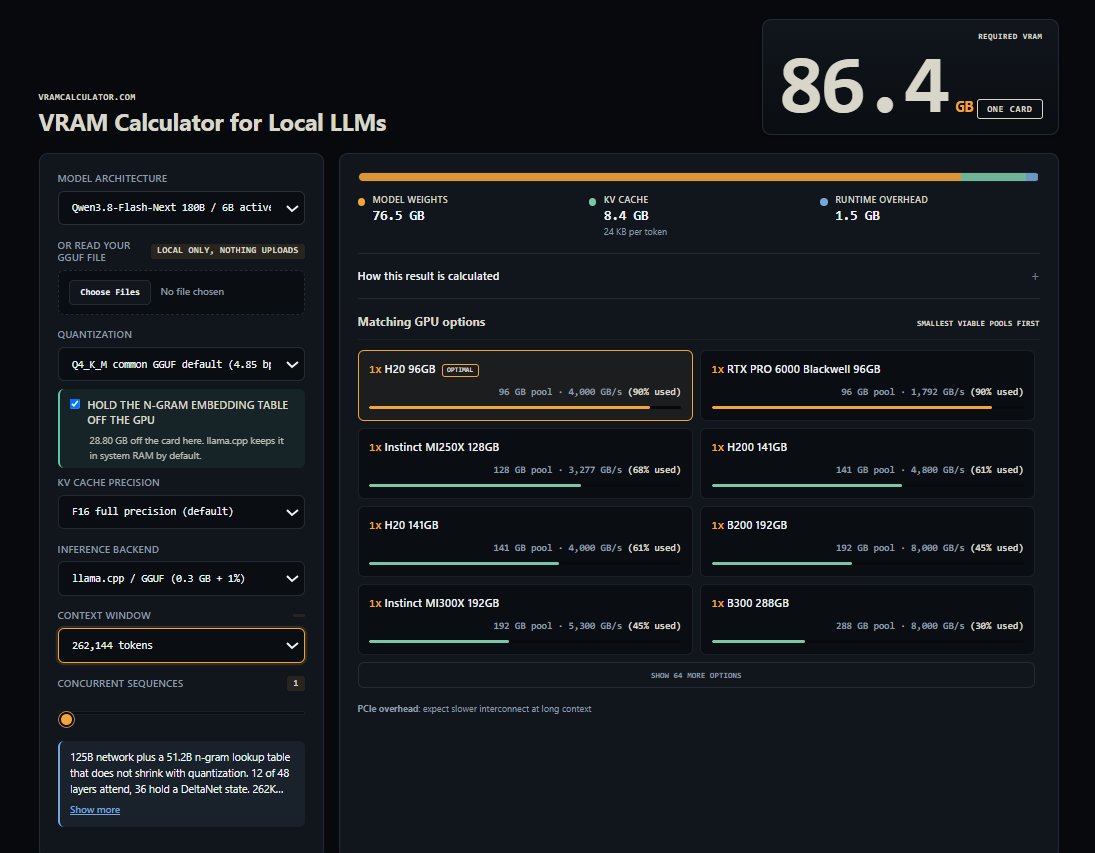
Qwen 3.8 Flash Next is the one model in our tests that needs more memory than it loads with: 0.38 GB extra once a long prompt starts.
Measured on a 96 GB card with prompts up to 236K tokens. The calculator counts it from yesterday.
I'm testing Qwen3.8 Flash next GGUF for agentic coding.
So far it's not pretty
UD Q2K XL and Coder are both largely underperforming the original model, and generate a crazy amount of tokens
I'm now running UD Q4K XL. I'll also run one more GSQ-RCO.
Full results next week
Update: Strata's creator now confirms the AVX1 port will be done. He closed the GitHub request because it isn't a bug, not because the port was dropped.
No date yet. Until it ships, the forks run it today.
https://t.co/ewD5Z3OXzU
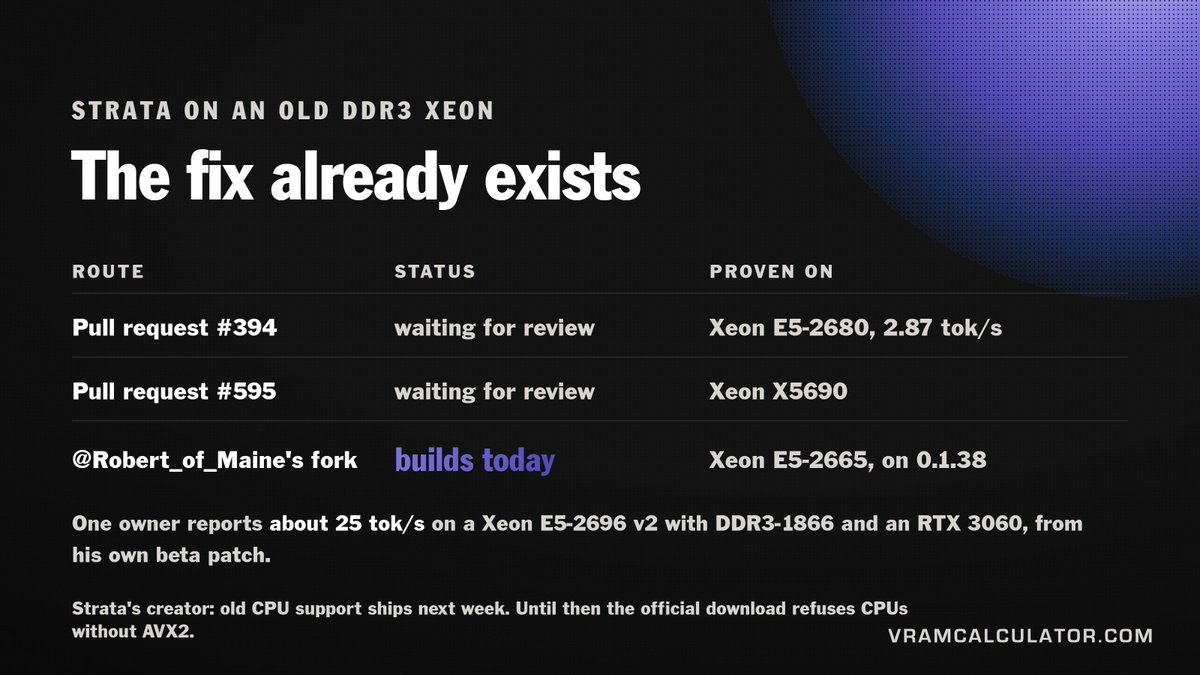
Strata on an old DDR3 Xeon: the fix already exists.
Two patches waiting for review, and a fork you can build today, make it run on CPUs without AVX2.
One owner reports about 25 tok/s on a Xeon E5-2696 v2, 4-channel DDR3-1866 and an RTX 3060, from his own beta patch.
My fork is now called 'Strata-Dirigo', because I've added a lot of features. Intel Arc support coming soon: I have the Arc Pro b70 I just have to install it and get going. Hopefully this will allow me to support the Alchemist generation as wel as Battlemage. https://t.co/qoLVaC55bc
Correction: Strata's creator has since closed an AVX1 request. An AVX1 port "isn't planned": it would be a second set of CPU kernels they cannot test or maintain.
For CPUs without AVX2, the forks are the route. We'll update here as we learn more.
https://t.co/uAoupfW0i0
@coldniko Today on GitHub you closed an AVX1 request: "An AVX1 port would be a second set of CPU kernels that we cannot test or maintain, so it isn't planned."
Is old CPU support still coming next week, or AVX2 CPUs only?
https://t.co/uAoupfWy7y
Thinking of an old 128 GB DDR3 workstation to run Strata? Check the CPU before the RAM.
Strata needs AVX2 and refuses CPUs without it. The cheap DDR3 Xeons (E5 v1 and v2) predate it.
AVX2 arrived one generation later: Xeon E5 v3 and v4, on DDR4.
@DataSculpting@coldniko Right. Strata's ready-made engine needs an RTX 20 or newer (compute 7.5). Pascal and Volta build only with STRATA_EXPERIMENTAL_SM60, and its own build file says upstream does not support it.
Same line on CPUs today: an AVX1 port isn't planned.
@great_garbanzo Qwen 3.8 Flash Next: it's the only model Strata runs. He didn't say which build.
On a 12 GB card most experts stay in RAM and the CPU computes them, so the CPU and DDR3 set the pace. Strata's own docs: more VRAM beats a faster GPU, each extra GB holds about 700 more experts.
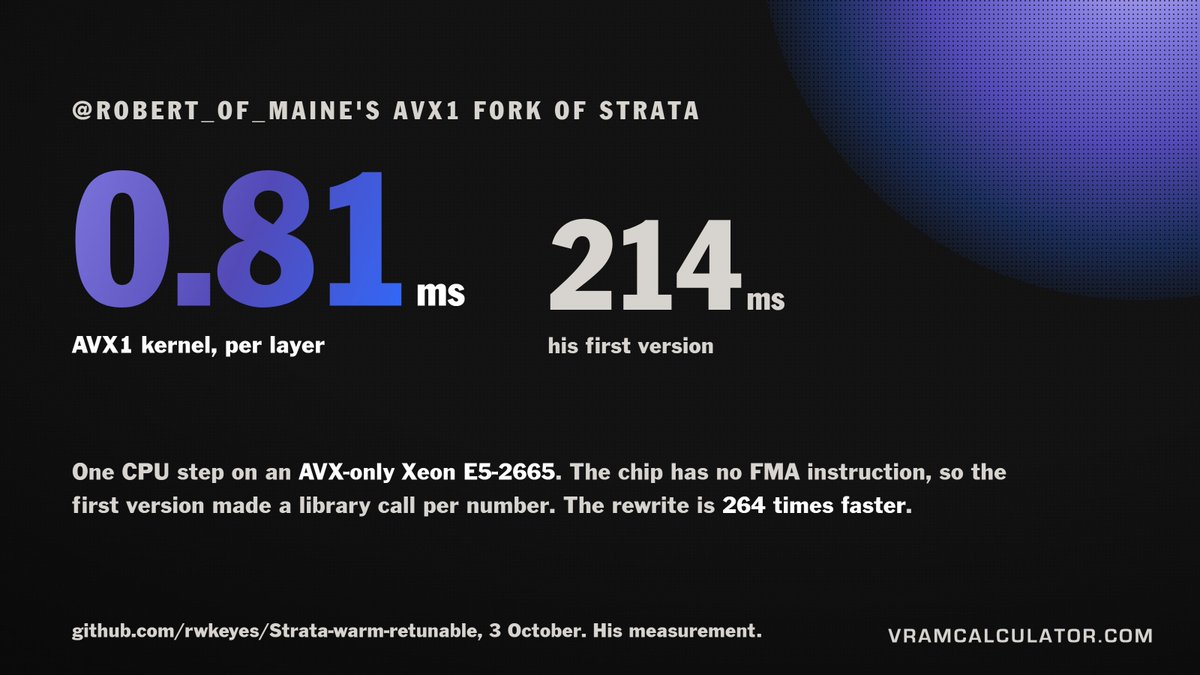
The fork you can build today is from @Robert_of_Maine: an AVX1 build of Strata 0.1.38.
On an AVX-only Xeon E5-2665, his rewrite of one CPU step runs in 0.81 ms per layer instead of 214.
Build it with STRATA_ISA_FLOOR=1.
Strata on an old DDR3 Xeon: the fix already exists.
Two patches waiting for review, and a fork you can build today, make it run on CPUs without AVX2.
One owner reports about 25 tok/s on a Xeon E5-2696 v2, 4-channel DDR3-1866 and an RTX 3060, from his own beta patch.