@antigravity team: There is an agy CLI bug that makes Gemini Argon fabricate long reviews. The 512K contextWindow setting is ignored. Argon always runs at 256K, so a long session silently drops what it read and still answers confidently, with no error. Seen in every version I’ve tested, 1.4.3 through 1.5.8. I keep needing to patch it.
Repro (macOS arm64):
Put “contextWindow”: “512K” in ~/.gemini/antigravity-cli/settings.json.
Run agy -p --model gemini-4-argon-medium with ~900 KB of context in the agent profile. It fails with “maxMessageTokens must be positive”. 700 KB works.
Or have Argon read an ~850 KB file with read_file. The conversation metadata shows max_context_tokens 256000, and truncation_reason 2 once the context passes ~200K tokens.
Expected: max_context_tokens 512000 for Argon when 512K is selected.
I ran across it when a 256K Argon code review read ~290K tokens of files, truncated, then returned “VERDICT: PASS” citing witnesses, IDs and function names that don’t exist in those files. Nothing in the output said context had been dropped.
The setting is saved and accepted, but it never reaches Argon’s token budget. Flash at 256K behaves as designed. Happy to share metadata.
@lex_node It depends upon the exact process used to do it. Model 1 creating a specification and tests and Model 2 implementing could be a valid clean room process.
@mboverell The fact is that prior to setting the 10x weekly limit, a 20x user *could* use 20x base. It was harder due to the 5 hour limit, but 20x was really 20x.
@adamhjk@AmplifyPartners@jesserobbins@stolinski Congratulations! Been watching Swamp since you started it. I agree with a lot of your premises - came to them independently. We should talk about the differences, though; would like to know your opinion.
This is your periodic reminder that @Google has the worst privacy policy of any individually-available plan. Want to refer to old chats? Then you have opted into 3-year retention of your data and training on your interactions.
@mjasay@twosigma@aiDotEngineer The issue is that we have technology ("laws", "ethics", "education", "management") for dealing with nondeterministic humans. Those don't work for agents - agents have a gradient they optimize against. You have to rebuild the limiting technology in a form agents understand.
@byron_miller@adamhjk@dhh No, for two reasons. First, doing that reduces license enforceability. You want to show how the human judgments are spread throughout the code, not isolated in particular areas. Second, increasing numbers contributions will be almost all AI or at least AI-assisted.
Over the last few months, we’ve made significant progress in reducing the effectiveness of distillation attacks against Claude.
In this post, we explain how: https://t.co/uWiRSLBuOS
@gabriel_weil@RepLoriTrahan Yes, agreed. But aren't people already liable for what they do or allow to be done via agents? To my mind, the bigger issue is the current push to anthropomorphize agents and recognize them as having some kind of personhood. AI systems are not accountable.
@adamhjk@dhh That said, I have independent concerns about software factories from a dev perspective. I don't think they preserve or engage the theory of the program (in the Naur sense) effectively, leading to a loss of control and ultimately a loss of quality. But that's a separate issue
It's not a theoretical concern. There are a lot of legal departments struggling with this right now. There are short-term fixes, but if an org moves to full-on 'software factories' it becomes much more difficult. The prevalence of this issue is one reason why I think the existing policy will be overturned.
@adamhjk@dhh I believe this will change, but until it does, copyleft is a bit of a time bomb. Permissive-ish now, in the future copyleft? That is a lot of uncertainty, waiting for someone to make the case.
@adamhjk@dhh The problem, at least right now, is that the US Copyright Office doesn't accept work that was done substantially using agents as being eligible for copyright. That turns the doctrinal basis for copyleft upside down, and makes the effective license much more permissive.
This matters legally too. The law asks what a "reasonable person" would do and makes the application certain laws dependent on internal mental states, because we recognize each human as a moral actor.
If we accept the argument that AI systems are moral actors, then what legally follows is the assignment of responsibility for harms to the AI system itself, not to those who created it or directed it to do the harmful thing.
Important piece from Microsoft AI CEO @mustafasuleyman. Training models to think of themselves as human (as Anthropic does Claude) with concepts of an inner self, psychological wellbeing, rights and presumably grievances, is a potential existential risk.
https://t.co/ilq1qPQVtg
Any lawyers using cowork - pay attention to whether your practice guidelines will allow this. They probably should - it is not meaningfully different than using Sharepoint on Microsoft 365 - but client policies around AI tend to be much more restrictive.
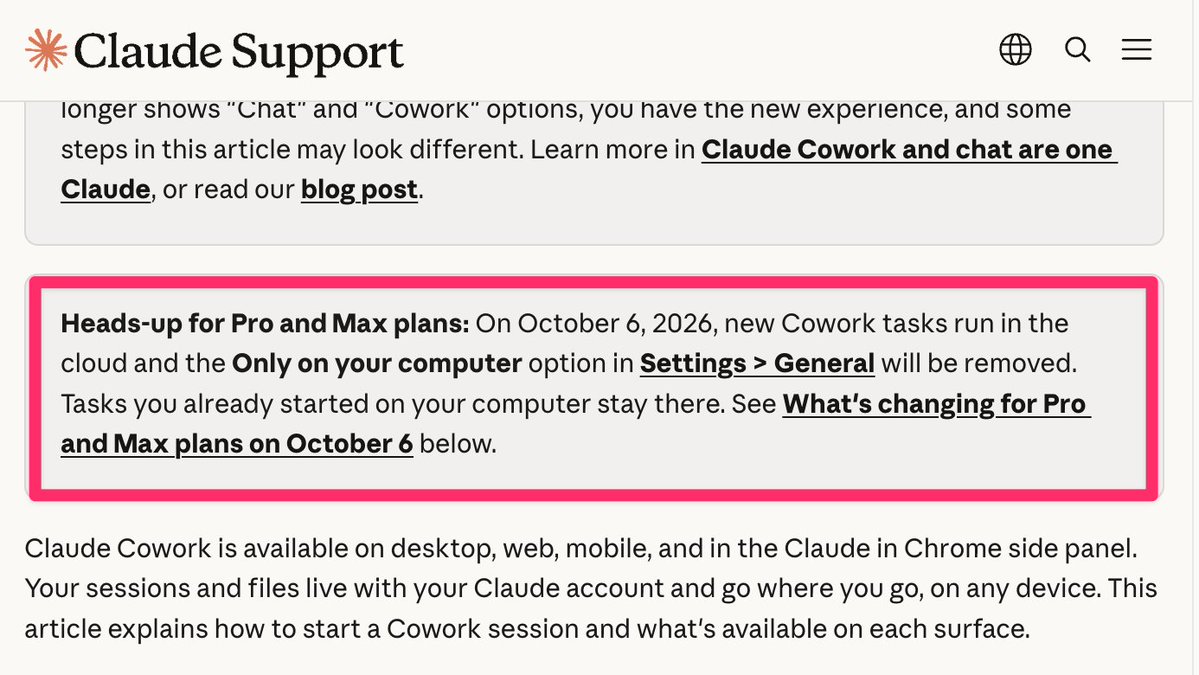
🚨Anthropic removes Cowork's local option for Pro/Max tomorrow.
New tasks run in the cloud. Existing local tasks stay on your computer.
Anthropic says your sessions and files "live with your Claude account and go where you go."
Where is my data, and who can access it?
@AnthropicAI's guardrails are the worst. I am trying to prepare items for a safety benchmark. I am examining licensing, not even content, but Opus 5.5 now kicks me out, just like Fable.
Anthropic just highlighted how good GLM 5.3 is at cyber. Thanks for the referral!