🎟️ 2 free tickets to VapiCon 2026, Nov 11-12, SF. Reply with the speaker problem breaking your voice pipeline. We pick 2 winners on Oct 26. #VoiceAI#VapiCon2026
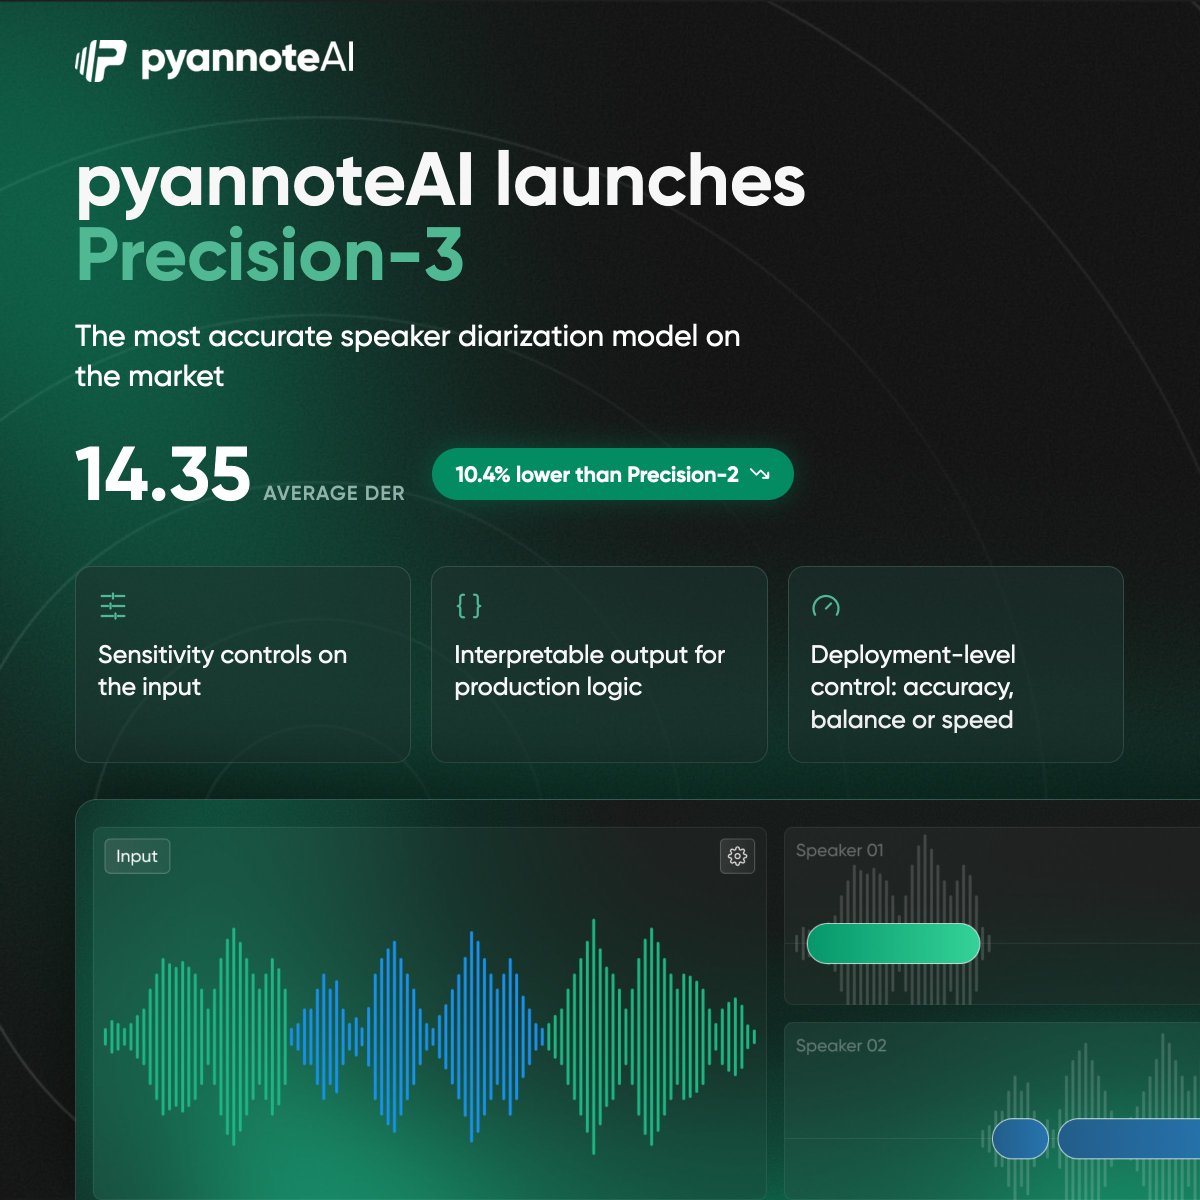
Haven’t worked with voice AI before, but following the @pyannoteAI Precision-3 release was surprisingly easy!
The diarization improvements & tunable speech & crosstalk sensitivity were interesting to learn about.
The upcoming Precision-4 features look exciting too. Can’t wait!
Speaker diarization (pyannoteAI), Transcription (Gladia), Compute (Modal): three layers of one Voice AI stack.
Oct 14, Paris. Panel + live demo of how they fit together.
https://t.co/h9XVYwfno8
Already running pyannote in production? On October 8 at 5 PM CEST, we'll show what changes when you switch to Precision-3: the new input parameters, per-frame probabilities in the output, and the migration steps.
Join live or get the recording ➡️ https://t.co/1NZzczCn5q
Last call: Paris Voice AI Meetup, Oct 14.
pyannoteAI x Gladia x Modal on running diarization, transcription, and infrastructure in production. Panel, Q&A, drinks.
https://t.co/h9XVYwfno8
Only two days after Precision 3 official release, first customers feedback is coming in.
💬 "1.8x speed improvement which puts it faster than our stt"
🗨️ "speaker over-splitting has gone down"
🗯️ "turn attribution is noticeably better"
So proud of the @pyannoteAI team!
Many of our customers run workloads with speaker attribution, with the strictest demands on both quality and speed.
We partnered with the team at @pyannoteAI to deliver both: some of the highest-quality diarization models on the market, with 3.2x higher throughput and 9.6x lower latency.
Precision-3 is live. Diarization error down 10.4% vs Precision-2 (14.35 vs 16.02 DER across 15 benchmark datasets), with most of that gain coming from better speaker attribution: the model gets the wrong speaker 18.7% less often.
New in Voice AI : I am heading to lead Developer Relations at @pyannoteAI 🎉
Pyannote builds the speaker intelligence layer for voice AI: their own diarization models that get millions of downloads ( 5M last month)
Behind that number is a community: researchers, engineers, people building meeting tools and dubbing pipelines etc. Taking care of them is my job now 💚
A big big thank you to @paw_lean for sharing about this opportunity - and rooting for me! You’re a true community person in and out 💜
If you're building with voice, come say hi 👋🏻
3 big Circleback updates this month:
• a free plan with unlimited meetings
• import your past meetings from other apps
• an API for all your Circleback data
here's what's new from our team retreat on a ranch
@juliarturc@n0mad_0@neilzegh Amazing work @juliarturc. We @pyannoteAI witness first hand that a lot of companies are currently training their own full duplex models as we provide them with extremely precise diarization of conversational training data. You should do a video about diarization by the way!
La voix est en train de redevenir le canal le plus puissant de l’IA… et une startup française mène la révolution. 🔥
Vincent Molina, explique comment Pyannote reconnaît des voix jamais entendues à l’entraînement, pourquoi leur modèle surpasse les standards actuels, et comment il s’intègre dans des pipelines audio aux côtés de Whisper.
👉 https://t.co/liaREi7SEp