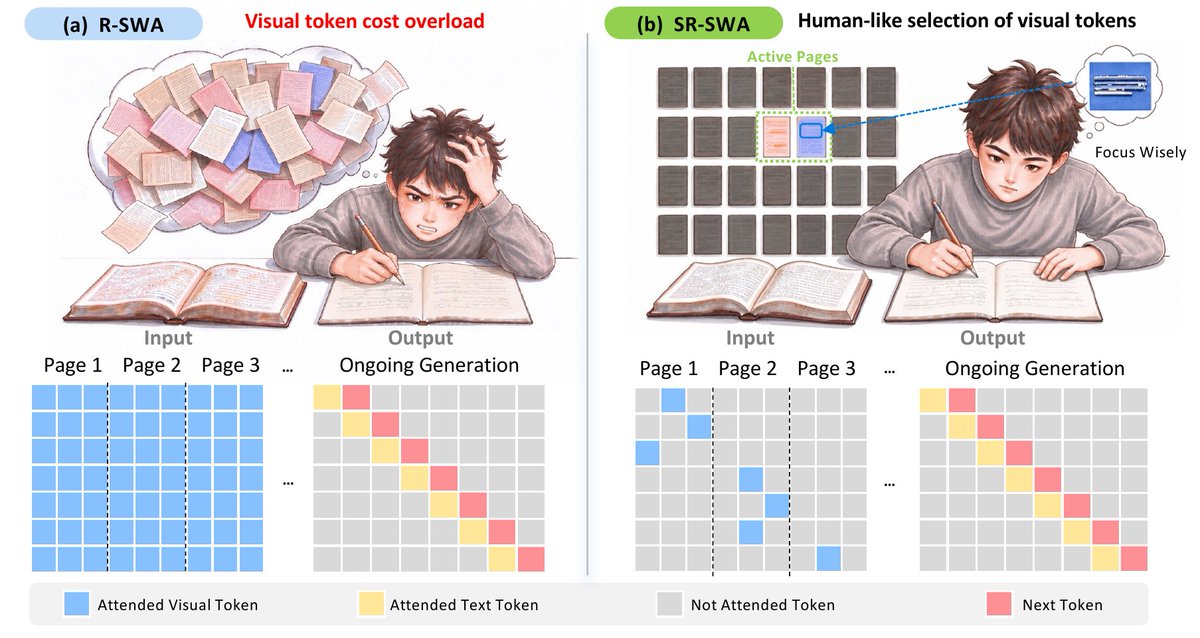
Baidu just open-sourced Unlimited OCR 2: a 3.3B model (MIT license) whose new SR-SWA attention keeps memory and per-step latency nearly flat no matter how long the document gets. Hundred-page contracts and archives in one pass, runnable locally.
via @Baidu_Inc#OCR
https://t.co/VG75ZZcdhS
Unlimited OCR 2 is here, and it's open source. 📖 ✨
Longer documents can mean a lot more attention computation. Our new SR-SWA mechanism keeps that in check by condensing text-visual attention interactions into a fixed-size set of working references.
Here's what it delivers:
- Document parsing at virtually any length, within a finite context window
- Nearly constant per-step decoding latency and memory footprint as documents grow longer
- State-of-the-art performance on MPDocBench and MarathonDocBench, covering documents from dozens to hundreds of pages
Check out the model here ↓
Hotel check-in, corporate reception, patient check-in, wayfinding: one kiosk, set up per site. 22-inch touch screen, face camera with liveness checks, optional ID reading, metal body. #SmartKiosk https://t.co/mQoaZvrSge
Physical Superintelligence says its AI research system solved 5 long-standing open problems in quantum information theory (Nos. 2, 12, 27, 38, 43), each with a paper and a Lean-checked proof. Machine-verified math makes AI science claims checkable. via @psipbc#AIResearch https://t.co/4IanRA9UcK
Today Physical Superintelligence PBC is announcing solutions to five long-standing problems in quantum information theory.
https://t.co/LjmLz0mCtF
Thread 👇
Fern 0.1, the first model from new lab Mirendil, holds up to 10M tokens in context: ~0.5M lines of code or days of agent traces at once. Why it matters: AI R&D agents can audit data and debug training runs end to end, no chunking. via @mirendil#LLM https://t.co/ua6yLyvSwS
Introducing Fern, Mirendil’s first model: pretrained from scratch, with up to 10 million tokens of context.
That’s ~0.5M lines of code or days of an agent’s work - all in context at once.
Built for high-volume agentic work in AI R&D: auditing training data, debugging training runs from logs, and reading agent traces end to end. Fern’s next-token prediction keeps improving as context grows to 10M tokens.
Fern 0.1 is Mirendil-Base after a short round of post-training. It’s the first and smallest of three models, with two larger ones now being pretrained.
We’ll ship frequent updates and make the model available soon.
Kimi K3.1 Pro hits 76.8 on the Browser Use Benchmark of real web-agent tasks, second only to GPT-6.1 Sol and ahead of Opus 5.5, Grok 4.7 and Sonnet 5.5, at ~$2 a task. Chinese models are now a real option for browser agents. via @browser_use#AIAgents
https://t.co/bTxu4TvsTv
Kimi K3.1 Pro is a beast at browser use 🤯
76.8 on the Browser Use Benchmark. Only GPT-6.1 Sol scores higher.
It beats Opus 5.5, Grok 4.7 and Sonnet 5.5, and it's cheaper than Opus at ~$2/task.
Best Chinese model we've ever tested, by a lot. Next best is DeepSeek V4.1 Flash at 70.6.
Moonshot cooked.
OpenAI's internal models produced 3 results now under expert review: local smoothing proved in all dimensions, the Exponential Time Hypothesis refuted in Lean, and Yang-Mills/QCD existence proofs. If they hold, AI is doing science. via @danintheory#AI
https://t.co/dxVPw1ndxn
We are announcing three new discoveries in mathematics, computer science, and physics about harmonic analysis, complexity theory, and quantum field theory.
https://t.co/9BX8HWQDTJ
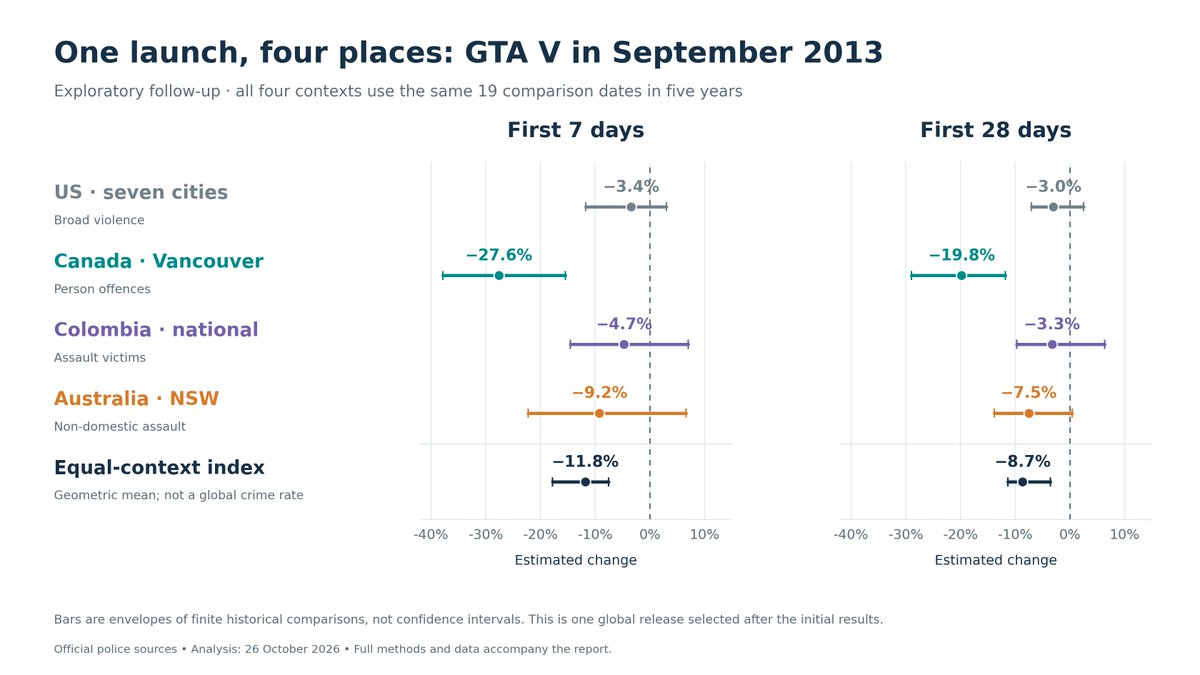
Ethan Mollick had GPT-6 Pro revisit a known study: it pulled fresh crime data and extended the analysis. GTA V's 2013 launch lined up with a dip in violence worldwide; other games are murkier. AI that replicates research is already useful. via @emollick#AIResearch https://t.co/EI6QphcAe8
I had GPT-6 Pro revisit the cool finding that violent video games reduce crime, as people stay home playing them. It downloaded fresh crime data & extended prior work.
Yes, GTA V's 2013 launch was linked with a dip in violence internationally. Other games are more ambiguous.
Runway just launched App Studio: describe the creative app you wish existed and it builds it, generating images, video and audio with Runway's models and your Brand Kits. No code needed, so any team can ship its own creative tool. via @runwayml#GenerativeAI https://t.co/vpJWW9lfYO
Introducing Runway App Studio.
Build the creative app you wish existed, just by describing it. It generates images, video and audio with Runway’s models and your Brand Kits, ready for you or your whole team. No code required.
See examples in the thread below.
FDA-cleared AI can now estimate breast cancer recurrence risk from a scan patients already have: TumorSight Risk reads an existing breast MRI alongside pathology. Why it matters: clearer risk answers without another test. Built by @SimBioSys on NVIDIA tech, via @nvidia#MedicalAI https://t.co/pTdrUufJHD
After a breast cancer diagnosis, one of the hardest questions is whether it will come back.
@SimBioSys is helping doctors and patients better understand that risk. Powered by NVIDIA technology, its FDA-cleared TumorSight Risk analyzes an existing breast MRI alongside pathology and clinical information to estimate the risk of cancer returning at five and ten years.
For women with HR-positive, HER2-negative early-stage breast cancer, those insights can be available before surgery, giving them and their doctors more information as they talk through treatment options.
AI can help give patients and their doctors more information when the decisions ahead feel most difficult.
Cursor's new Agent SDK: define agents as code, prompts in Markdown and tools in TypeScript, then deploy on hosted infra or your own. Built-in evals score every change, so agents get tested like real software. via @cursor_ai#AIAgents https://t.co/1uyjkkW46c
The Agent SDK is now available.
Define agents as code, with prompts in Markdown and tools in TypeScript. Deploy them on our hosted infrastructure, or run them on your own.
Built-in evals let you measure every change and make your agents better over time.
More than 25,000 nonprofits now use Claude, most of them small local teams. Anthropic's new Claude for Nonprofits plugin, built with about 30 of them, adds fundraising, marketing and hiring skills grounded in each team's context and AI policy. via @claudeai#AI https://t.co/awqZGHUdm2
More than 25,000 nonprofits now use Claude. Most are small, local teams.
We’re expanding Claude for Nonprofits with a plugin built with around 30 of them, adding skills for fundraising, marketing, and hiring grounded in each team’s context and AI policy: https://t.co/LWHcr1CT20
OpenAI's GPT-6.1 Terra matches GPT-6 Astra on Agents' Last Exam at one-tenth the price per token, and finishes tasks 3x+ faster. Cheap, fast computer-use agents just became practical for everyday work. via @OpenAI#AI https://t.co/GDrIcXFejv
GPT-6.1 Terra: delivering fast and capable computer use at a lower price.
GPT-6.1 Terra understands what’s on screen, takes action across apps, writes naturally, and is a more capable model for your whole workday with the efficiency to take on more of it.