15s of MiniMax-H3 video + audio, generated in ~72s on one RTX 5090.
Our baseline took ~26 minutes. We wrote up how LightX2V got it down to 72s 👇
768×1344, steady-state benchmark. MP4 export and network transfer excluded. https://t.co/0sMSdJfcIQ
🚀 Excited to release RealtimeWAM! The first one-step asynchronous World Action Model with superior task performance.
⚡ ~12 ms action generation with a 6B model on a single H100 GPU — ~25× faster! ⚡
✨ Supports any MoT-based WAM (e.g., Fast-WAM and Faster-WAM), with less than 1% success-rate loss on diverse benchmarks (e.g., RoboTwin 2.0 and LIBERO-Plus).
🧩 Algorithm–system co-design: few-step distillation, blockwise asynchronous inference, and efficient kernels—all implemented in LightX2V.
🙌 Welcome to check it out, try it, and share feedback!
📄 Paper: https://t.co/aE80M7nM9H
🤗 Model weights: https://t.co/qzpOuBNbk1
⭐ Code: https://t.co/h6KnAkbkiZ
SenseNova U1 with NEO-Unify just dropped 👀
• 🚫 No VE / VAE
• 🔗 End-to-end pixel–word modeling
• 🧠 Native multimodal reasoning (efficient & unified)
Moving from “multimodal integration” → “true unification”
Strong signal toward the next paradigm.
https://t.co/iTEyHh0N5m
The infra behind SenseNova U1 is built on LightLLM and LightX2V. 🛠️
By leveraging these engines, U1 delivers exceptional throughput and low-latency performance for its pixel-word modeling.
Deep dive into the inference infra here: https://t.co/mJInjTtp1E
SenseNova U1 with NEO-Unify just dropped 👀
• 🚫 No VE / VAE
• 🔗 End-to-end pixel–word modeling
• 🧠 Native multimodal reasoning (efficient & unified)
Moving from “multimodal integration” → “true unification”
Strong signal toward the next paradigm.
https://t.co/iTEyHh0N5m
🚀 Day0 Support for Qwen-Image-2512!
Thrilled to collaborate with @Alibaba_Qwen to deliver the 4-step distilled version and inference solution for the latest model, achieving 4-step inference without quality loss.⚡️
Model: https://t.co/VwiWRdNYyT
Repo: https://t.co/SATQr3KA7m
🎁 A New Year gift from Qwen — Qwen-Image-2512 is here.
🚀 Our December upgrade to Qwen-Image, just in time for the New Year.
✨ What’s new:
• More realistic humans — dramatically reduced “AI look,” richer facial details
• Finer natural textures — sharper landscapes, water, fur, and materials
• Stronger text rendering — better layout, higher accuracy in text–image composition
🏆 Tested in 10,000+ blind rounds on AI Arena, Qwen-Image-2512 ranks as the strongest open-source image model, while staying competitive with closed-source systems.
👉 Try it now in Qwen Chat: https://t.co/941HmITJ2W
🤗 Hugging Face: https://t.co/mP4AFvdvH1
📦 ModelScope: https://t.co/Jq34O0RGQw
💻 GitHub: https://t.co/A9yvJZ6TJc
📝 Blog: https://t.co/mr4UVRvQlT
🤗 Hugging Face Demo: https://t.co/MrnQEn44zx
📦 ModelScope Demo: https://t.co/NCvu7M4Z6k
✨API: https://t.co/9N3jB1f8Ll
🎆 Start the New Year with better images.
🚀 Introducing Qwen-Image-Edit-2511 — a major upgrade over 2509, delivering significantly stronger consistency and more powerful real-world image editing.
✨ What’s new in 2511:
👥 Stronger multi-person consistency for group photos and complex scenes
🧩 Built-in popular community LoRAs — no extra tuning required
💡 Enhanced industrial & product design generation
🔒 Reduced image drift with dramatically improved character & identity consistency
📐 Improved geometric reasoning, including construction lines and structural edits
From identity-preserving portrait edits to high-fidelity multi-person fusion and practical engineering & design workflows, 2511 pushes image editing to the next level.
👉 Try it now:
🎨 Qwen Chat (Image Edit): https://t.co/r2Zcg4OjGc
SekoTalk creates a MV🎤based on a character and the music produced by @minimax_ai@Hailuo_AI 's latest Music 1.5
🤩Watch the full 3.5-min performance👇
Try it yourself (✨limited free✨)👉 https://t.co/RZoikwB8DN or https://t.co/mKBAXhiQCd
Explore more👉https://t.co/VDQldMmrlc
#PhasedDMD distilled the Wan2.2-T2V-A14B model into a 4-step version with better camera control and motion dynamics—now open-sourced! 🔥 #wan22
👉 [Model] https://t.co/zbzy1ZShnV
👉 [Code] https://t.co/DrQJ6wUThz
📊 See 18 minutes of comparisons: https://t.co/0hUsZQqy37
@multimodalart Thanks for the great work @multimodalart ! Excited to see the LoRA getting such positive response. The LoRA was extracted by KJ from our released checkpoint (https://t.co/8vlgIVNyk8) - would be wonderful if the repo could note the source.
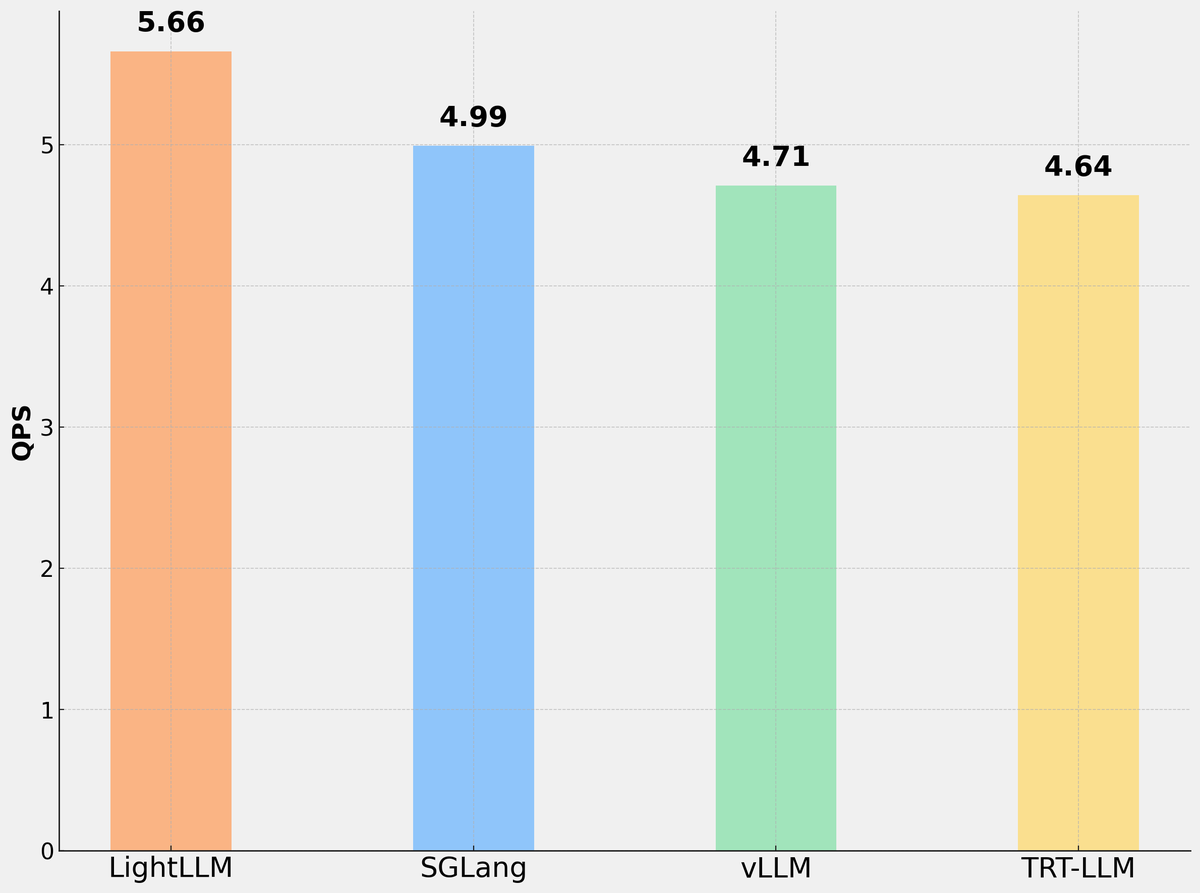
@NVIDIAAIDev 🚀 We’re excited to announce LightLLM v1.0.0! This release delivers higher throughput than SGLang for Deepseek-R1, setting a new benchmark in performance.
📖 Learn more: https://t.co/q4afDu8EtE
💻 GitHub repo: https://t.co/fVJkvWRbZv
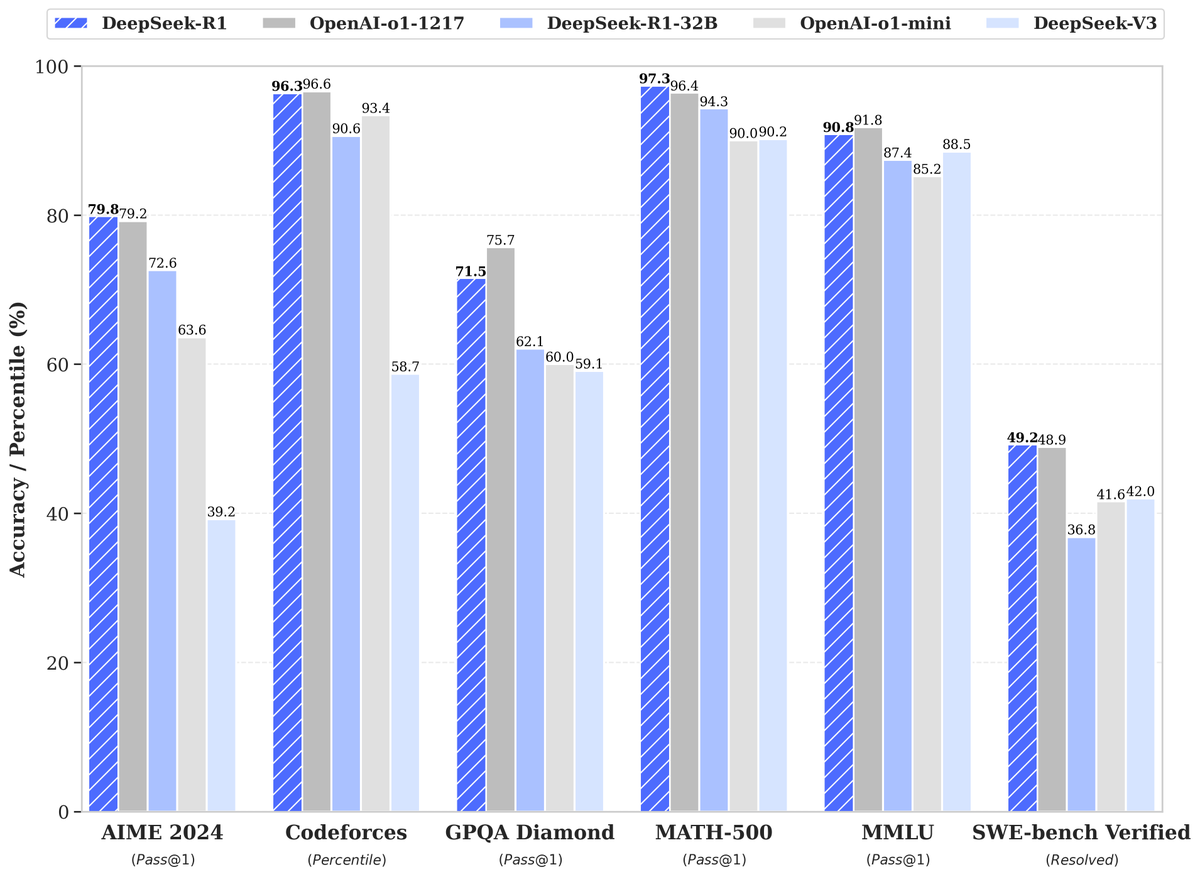
🚀 DeepSeek-R1 is here!
⚡ Performance on par with OpenAI-o1
📖 Fully open-source model & technical report
🏆 MIT licensed: Distill & commercialize freely!
🌐 Website & API are live now! Try DeepThink at https://t.co/v1TFy7LHNy today!
🐋 1/n
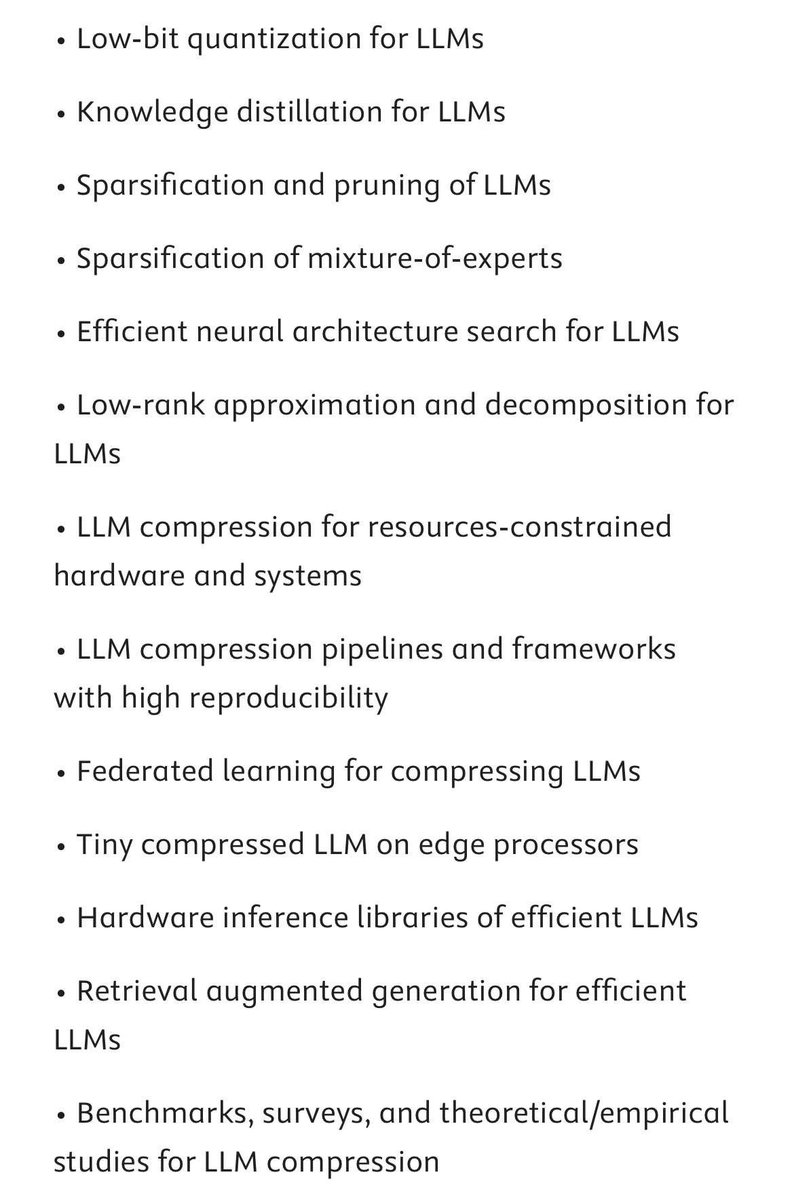
💡Excited to announce our Special Issue on "Model Compression in the Era of Large Language Models" in Neural Networks journal! We welcome submissions on LLM compression about algorithms, hardware, benchmarks, survey, etc. More info: https://t.co/1ii1vZQTYs
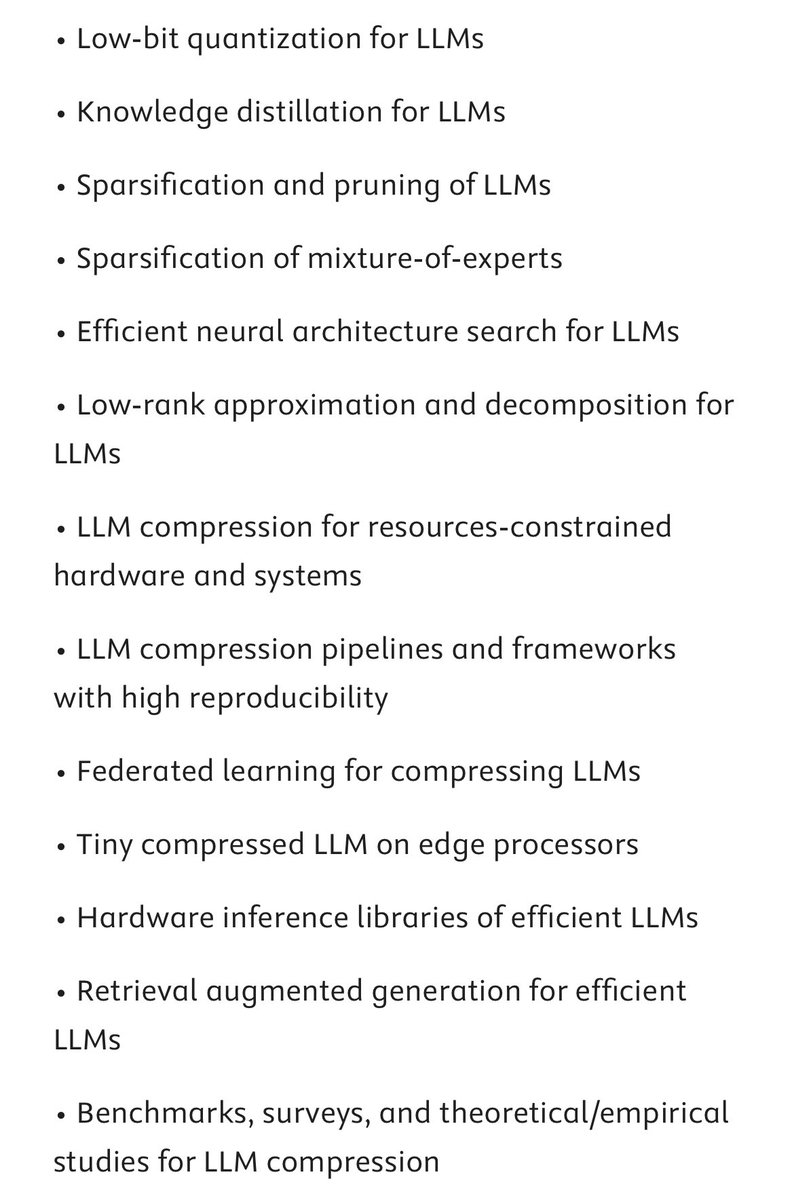
Excited to announce our Special Issue on "Model Compression in the Era of Large Language Models" in Neural Networks journal. Welcome submissions on LLM compression about algorithms, hardware, benchmarks, survey, etc. More info: https://t.co/RZfRk8gp97