Gemini 4 Neon is a huge surprise: first impressions
Pros:
- Competent
- Great communicator
- Responds well to correction
- Figures out intent like Claude
- Best writing model I've ever seen
- Very good at learning from context
Cons:
- Its one shot demos look bad
- Doesn't go above and beyond by default
- Verifies everything to death (also a Pro kinda)
- Slow because of too many tool calls and bad latency
Subsidization:
Not too bad! ~OpenAI level subsidization
And that's on top of already good cost performance at API rates
Pretty cost-efficient!
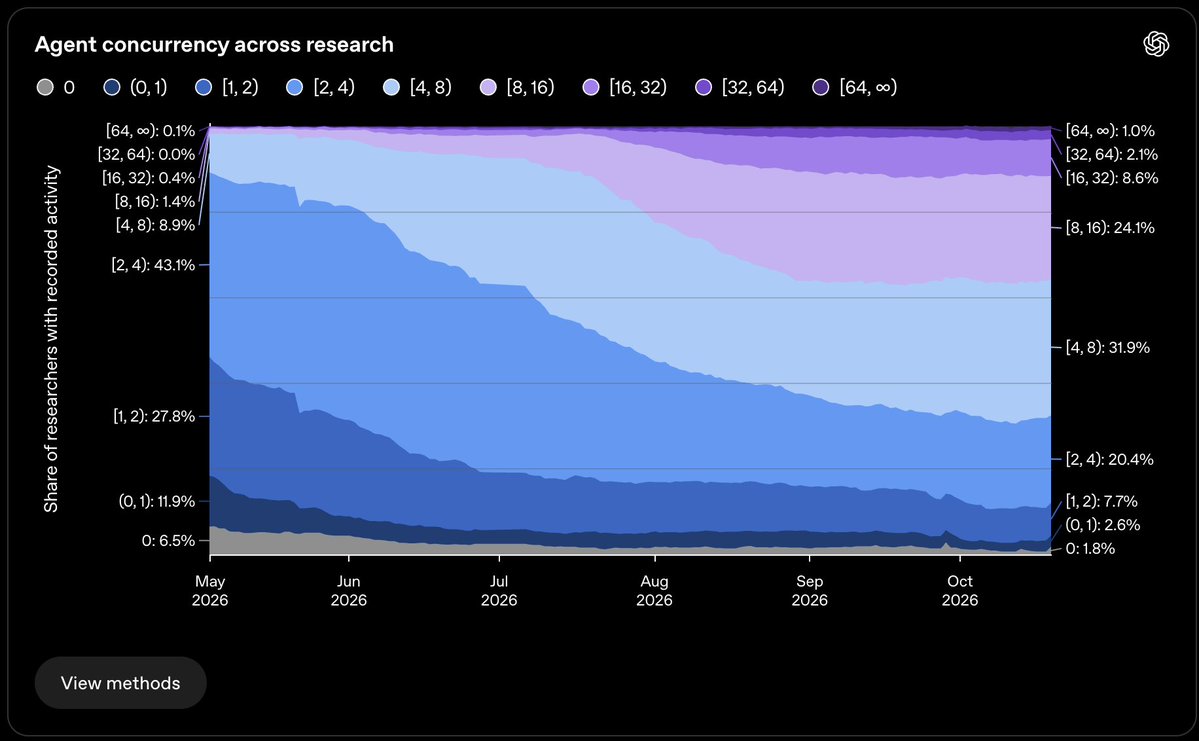
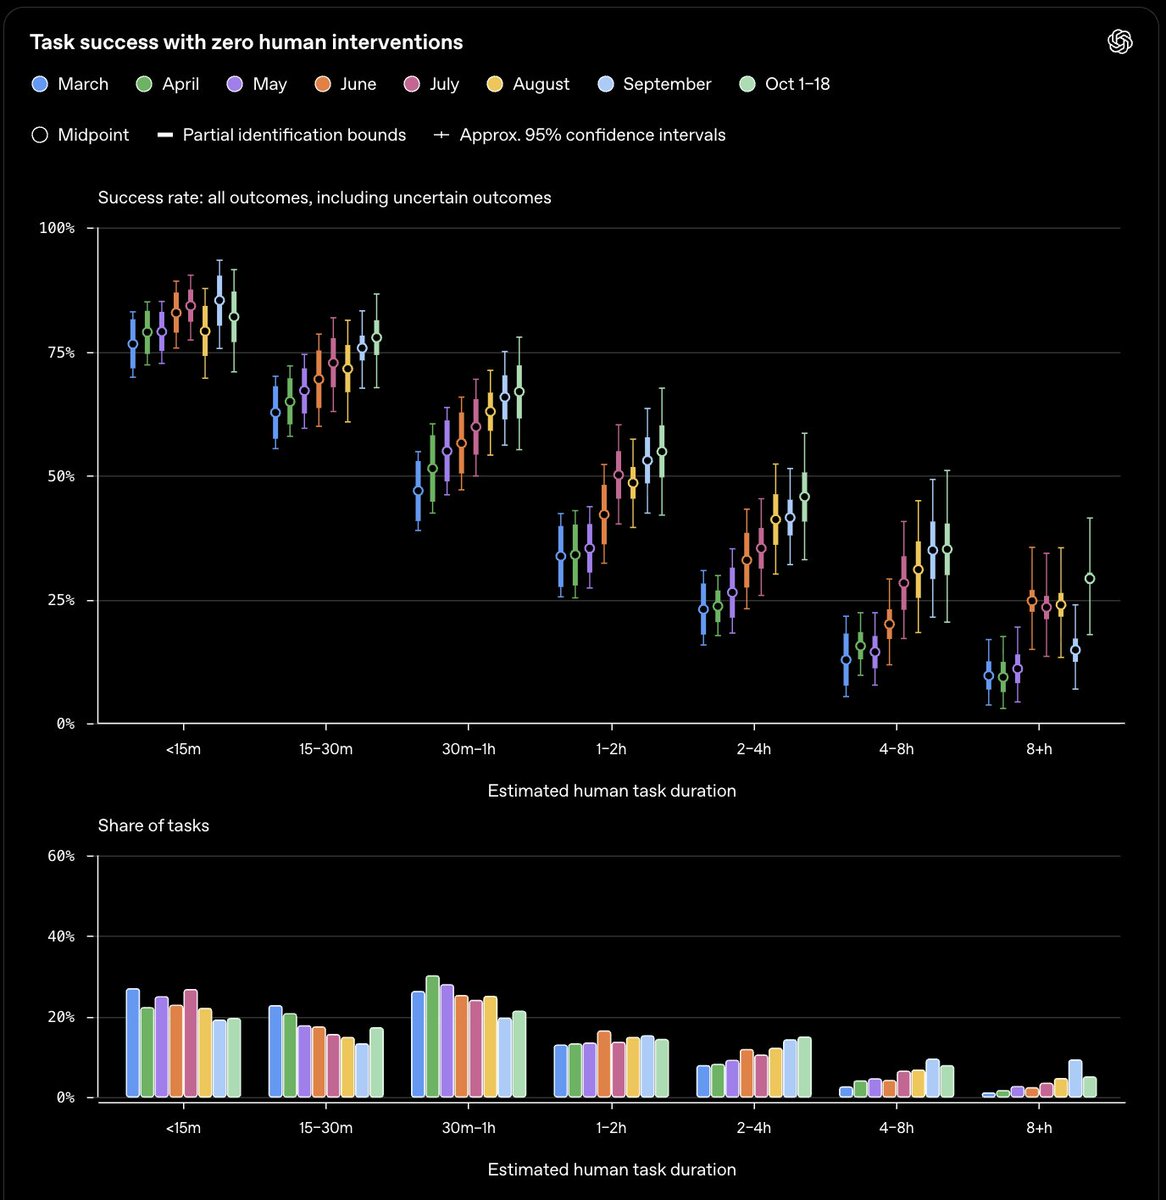
Seems like the OpenAI research acceleration blogpost is not what you would expect if we were definitely on the cusp of artificial superintelligence - models that are more cognitively capable than ~ALL humans on ~ALL tasks. Agent workdays have grown very jaggedly, swarm sizes haven't grown very much, and spending on tokens hasn't actually outpaced spending on human workers* although the growth rate is clear. There also hasn't been an acceleration in research experiments per experimenter, or in the internal ECI scores of OpenAI's models. Perhaps most importantly (and most surprisingly), the task success rate for <15 min tasks hasn't grown very much at all, and the share of tasks done by agents across various time horizons is both low and not growing for the most part.
It's possible that Anthropic is *much* further along in automating AI R&D than OpenAI, and that METR saw this in their investigation. It's also possible that we see nothing much right up until a shocking acceleration in capabilities, like we saw in mathematics. We certainly can't rule out the possibility of an intelligence explosion.
But there's been a huge belief cascade in AI in general and AI safety in particular that seems largely unwarranted given the evidence that we have today. It's entirely possible that we can't fully automate all AI R&D tasks in the imminent future, or that full automation of AI R&D doesn't massively accelerate AI capabilities progress, or that capability gains concentrate in easily verifiable tasks and fail to generalize to the messy real world. These are all open research questions