i send it to a cloud gpu preferably rtx pro 6000 i don't know how but it was faster for me compared to the B200 and B300.
i used yota labs for it.
If you want very very fast rendering. You can take multiple of them let's say get 12 gpus and send 500 frames to each. It would cost more but not suprisingly a lot as you are not changing the total time too much anyways. the 12 minute on one get's split to 1 minute on each.
I am so humbled and Grateful that I was born in this time of human civilization.
A few points to note by the way.
1. It's technically not a flying machine more like a bouncing machine.
The way it is in the air it's very evident it can actually fly Theoretically in future. But the problem is the air thrusters need to recharge and then it can do these maneuvers but continuous flight and moving from point A to B still need to be aced.
2. The way it hops and stuff if this car in the rocket mode is in hands of silly man can do a lot of damage.
The rocket mode has limited implications in the current environment of cars on street. But eventually if done economically and efficiently it is better than the friction we face on the ground.
while benchmarking our AutoResearch harness we noticed that there was a ~1.1pt jump in benchmark performance when the agent's name is Ilya. it's kind of funny to think about the set of circumstances that made that happen
Using Gemini 4 makes you realize how many other models must be distilling Claude/GPT (or using a similar training pipeline). It feels quite different than other models.
i don't remember doing anything special for computer use it did ask for accesibility and screen share permissions which i allowed ( the toggles) and it was able to work but not that efficiently. Are you comfortable here. I can talk in dm if you want? Or it's okay here as well anything is okay.
Tried Gemini 4 Argon in api of discounted price of 10$/M output price and started a work . Had 5 dollars vanished in like half an hour. And my work was not done.
For Pro subscribers that want to try out Argon, you get $10/month in API credits. Redeem your credits and get immediate access to Argon.
Read more here https://t.co/hXA2WBTcEX
It is very obvious looking at results for various labs that you just cant make a very chonky boy and beat Ant or OAI.
The data and RL , architecture improvements and RSI does make it tough.
They are very conservative with their launches due to safety reasons if they really released their product as soon as it's ready.
No other labs don't even come close at all.
And it also seems they really only care or bother about each other's releases.
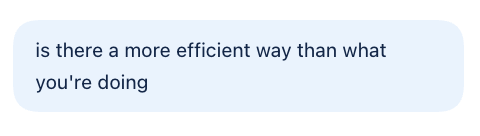
Every single time i ask is there a better solution. Is this the best way to do this.
They will never deny they will always come up with something . but at one point you will know they are talking nonsense and at that time you know you have peaked.
Sometimes it happens only in one iteration as models are getting good.
It's so funny to me that coding agents get meaningfully better when you ask them this question.
I just got a 6x speed increase and 8x cost reduction by asking Astra this after it built a new feature.
...why didn't you just do it this way the first time? 😂