Google open-sourced Harness²!
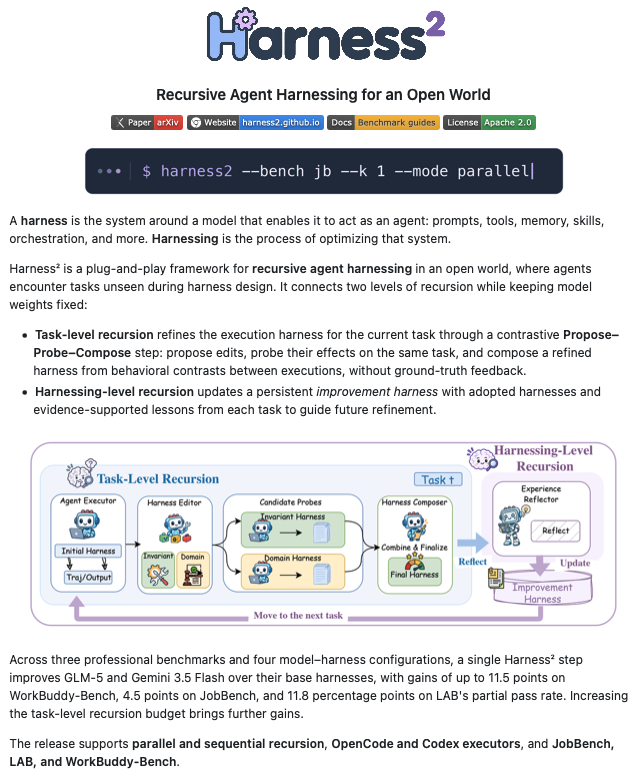
Harness² is a framework for recursively improving the harness around an agent while keeping the underlying model weights fixed.
The interesting part is that it does this at two different levels.
For the current task, Harness² uses a Propose → Probe → Compose loop. It proposes changes to the harness, runs those variants on the same task, compares how the executions behave, and then composes a better harness from that evidence.
That is the task-level recursion.
But the process does not reset after every task.
Harness² also keeps the harnesses it adopted and the lessons supported by execution evidence, then uses those to guide how future harnesses should be improved on new tasks.
That is the harnessing-level recursion.
So one loop improves the harness for the task in front of the agent.
The second loop improves how the system learns to build better harnesses over time.
The editable harness itself can include the system prompt, guardrails, memory, tool guidance, subagents, skills, scripts, and plugins.
You can also run the recursion in two ways:
Parallel recursion explores more candidate harnesses.
Sequential recursion carries the refined harness and accumulated evidence through multiple Propose → Probe → Compose steps.
Google reports that even a single Harness² step improved GLM-5 and Gemini 3.5 Flash across JobBench, LAB, and WorkBuddy-Bench, with larger task-level recursion budgets bringing further gains.
That is what makes Harness² more interesting than just another agent framework.
It is treating the harness itself as something that can be iteratively improved from execution evidence, both within a task and across tasks.
100% open source.
I’ve shared the GitHub repo in the comments!
Google just released free 2-hour course on full Harness engineering from 0% to 100%:
0% → 0:29 - Harness engineering from scratch
15% → 11:08 - build your first agent right way
30% → 28:08 - Eval engineering: build Chief of Staff agent
65% → 1:00:13 - Loop engineering
100% → 1:23:19 - self-improving graphs system that works 24/7
most people keep trusting agent that "looks right" - the real upgrade is a Harness that tests, judges and rewrite your agent until it works
learn Harness from Google, ship your first - then unlock the full Agent systems below:
Probability of getting rejected for not knowing RAG, vector databases, and AI agents: 20%
Probability of getting rejected for not knowing networking, load balancers, CDNs, operating systems, and databases: 99%
I have been fine-tuning LLMs for over 3 years now.
Here are 5 LLM fine-tuning techniques, explained with visuals:
Traditional fine‑tuning is impractical for LLMs (billions of params; 100s of GB).
Since this kind of compute isn't accessible to everyone, parameter-efficient fine-tuning techniques (PEFT) were built.
Before we go into details of each technique, here's some background that will help you better understand these techniques:
LLM weights are matrices of numbers adjusted during fine-tuning.
Most PEFT techniques involve finding a lower-rank adaptation of these matrices, a smaller-dimensional matrix that can still represent the information stored in the original.
Now with a basic understanding of the rank of a matrix, we're in a good position to understand the different fine-tuning techniques.
(refer to the image below for a visual explanation of each technique)
1) LoRA
- Add two low-rank trainable matrices, A and B, alongside the weight matrices.
- Instead of fine-tuning W, adjust the updates in these low-rank matrices.
Even for the largest LLMs, LoRA matrices take up a few MBs of memory.
2) LoRA-FA
While LoRA significantly decreases the total trainable parameters, it requires substantial activation memory to update the low-rank weights.
LoRA-FA (FA stands for Frozen-A) freezes matrix A and only updates matrix B.
3) VeRA
- In LoRA, low-rank matrices A and B are unique for each layer.
- In VeRA, A and B are frozen, random, and shared across all layers.
- Instead, it learns layer-specific scaling VECTORS (b and d) instead.
4) Delta-LoRA
- It tunes the matrix W as well, but not in the traditional way.
- Here, the difference (or delta) between the product of matrices A and B in two consecutive training steps is added to W.
5) LoRA+
- In LoRA, both matrices A and B are updated with the same learning rate.
- Authors of LoRA+ found that setting a higher learning rate for matrix B results in better convergence.
____
Find me → @_avichawla
Every day, I share tutorials and insights on DS, ML, LLMs, and RAGs.