Government Abuse is BAD for business. Getting ripped off on business phone / internet? Veteran-owned Business Telecom consulting. Free quotes USA lowest prices.
#Developers and #VibeCoding without a spine is weakness!
I wrote a new article about AI where I propose some standards for agentic tooling. More to come soon:
https://t.co/55LxaHxivf
@Da7_Tech Dot is good for some things live watching inbox but far too slow to let up with coding tasks and projects. I use mine for reviews and reminders and showing important emails out of all the spam...
@zerodhin Share GitHub so we can help build with you. I have a 1 yr old game engine and studio but not polished yet. It's more difficult to build solo than in a team
But that's exactly what history shows... Socialist and radical agenda to gain power promise anything then remove all opposing views from within and jail (or murder) those who stupidly helped you gain power thinking they would benefit and watch countries change regime and economies fold as human rights and freedoms are traded for position and political influence not because it's right but because it's self preservation mode at that point.
Holy sh*t. Claude Code just found a hidden chip inside my Chinese power bank from Guangzhou. Every time I charged my iPhone, it quietly copied the whole phone…
It also read our saved Wi-Fi password off my iPhone, got onto our home network and sent everything to a server.
I bought it for $19 at an airport kiosk there 3 weeks ago. No brand, 30,000 mAh on the label, and it felt heavy.
The first time I plugged in, the screen asked "Trust This Computer?". I tapped Trust without thinking and went on with my day. That one tap gave it access to everything.
This morning I finally set up Claude Code to warn me when any device starts reading my files. An hour later, 10 seconds into charging, the screen filled with yellow warnings, then red ones: data was moving when it should only be charging.
I asked Claude Code what was going on. My phone saw the power bank as a small computer with 64 GB of storage and its own internet connection.
A USB cable has wires for power and wires for data, and a normal charger only uses the power ones. This one used both, and it had already copied all of this:
→ /device → IMEI and serial number
→ /contacts → 1,206 numbers
→ /apps → every app I have, including my 2 bank apps
→ /photos → 3,912 pictures, my passport among them
→ /wifi → our network name and its key
→ /wife's iPhone → her photos too, she charged from it twice and tapped Trust too
Each time we plugged in, it used that key to get online and send out the new files:
sends to → 47.***.***.12
uploads → 19 in 3 weeks
last one → last night at 2:14, while we slept
I pulled the cable right away. Then Claude Code blocked that address on our router and walked me through changing the Wi-Fi password and the logins for my bank apps.
I had it opened at a repair shop, and what was inside is in the first comment. A 30-second check for your own is in the second one. Save this and test every power bank in your house today.
To my friends where there's
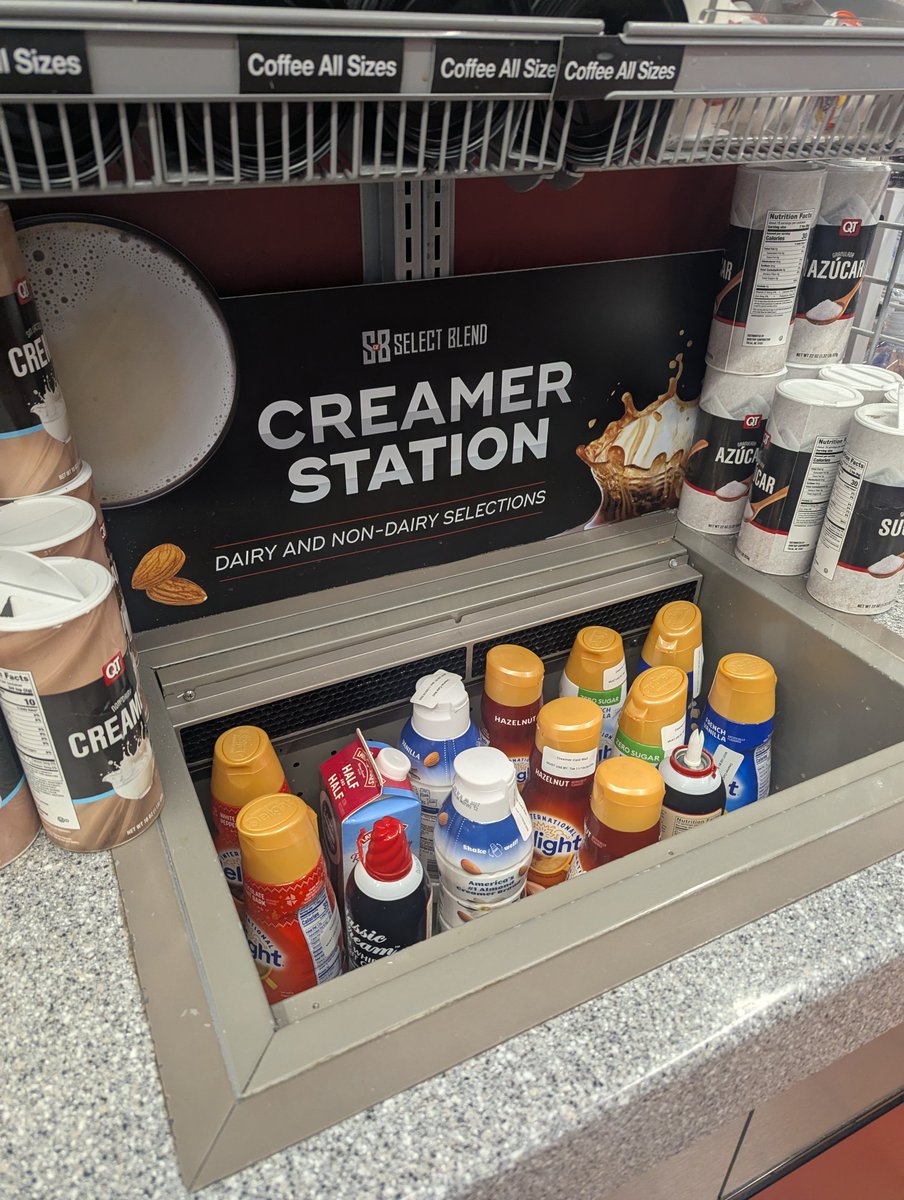
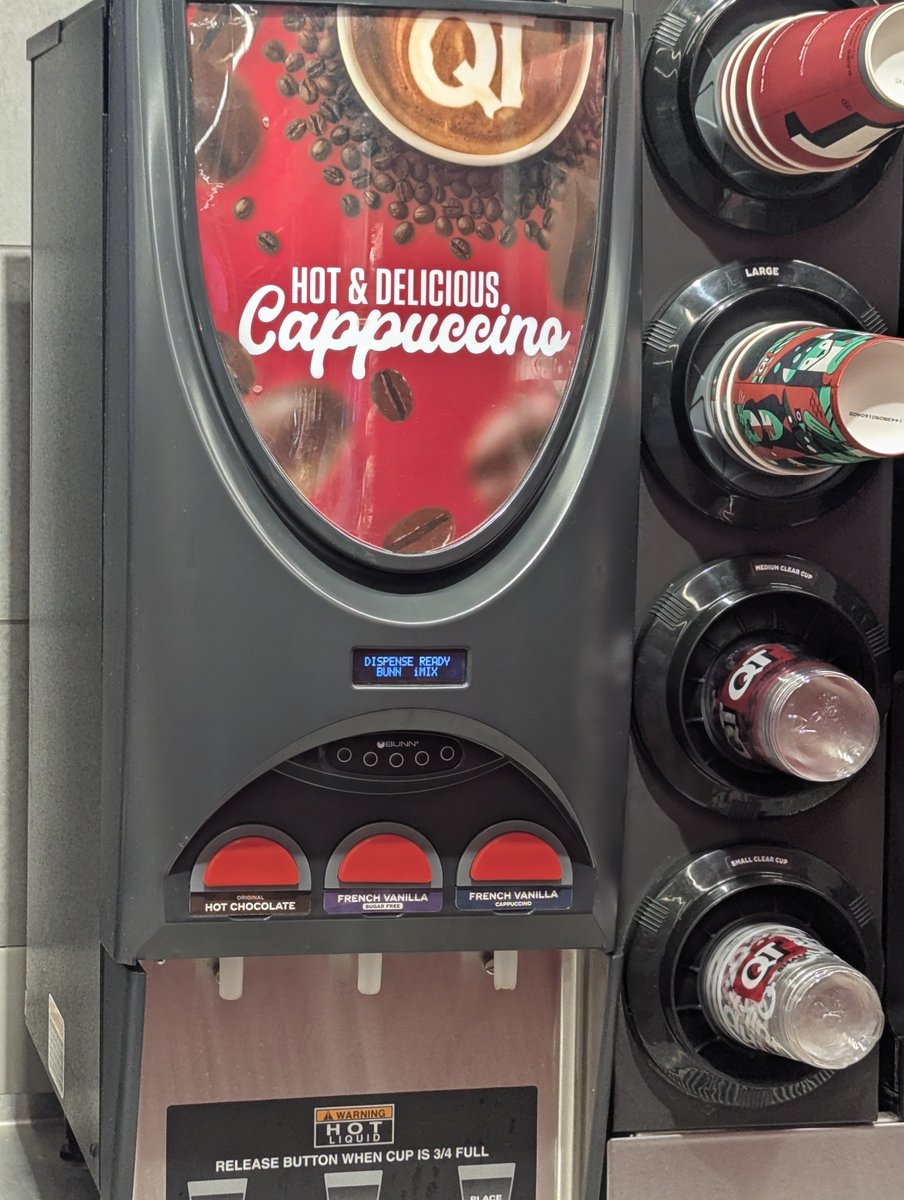
@QuikTrip nearby : did you know QT has made massive upgrades to their coffee bar? Check out the $1 code and a doughnut deal they extended for this month too! Starbucks and Dunkin need to watch out for the Midwest King of convenience gas stores - it's not only a great deal but also very tasty, and I'm a coffee snob. Check this dark roast fresh grind and pour (small in large cup) topped with vanilla cappuccino hot and fresh then topped with yummy whipped cream and some sugar in the raw on top. Total heaven for only $1. I started to Uber drive to have a different view than just my computer screen all day and night as I code all the time now. It's fun to meet people and see what events are happening in my town I had no idea was going on. I get to network with a lot of people even executives of many companies I drive now and then... But rider share drivers in my area barely make any money... They work 12 hours a day without bonuses or overtime or benefits and end up spending a ton on fuel each month. Having a class act clean restroom and food options everywhere you go on any side of town at QT it's like a little oasis for us active people that can't get home just yet. Thanks @QuikTrip for the hard work and best wishes for continued success. Anyone still reading? Go get your $1 coffee and doughnut before they're all gone! I have saved a ton on coffee because of this very special deal. Not sure if anyone says thank you to a company, but that l thanks QT!
The blue 💙 isn't self preserving. Most of them are the exact targets for the radical religious culture cults that seek to return humanity to barbarian behavior and forced compliance or be put to death in the most horrific ways. Congrats blue Smurf people. You'll be fist to go I'm sure.
@PatrioticS19052@its_The_Dr Lane change ticket is to cover up for the illegal search and detainment. Cops here do that crap all the time. If their suspicion turns out to be nothing and you complain that issue tickets in retaliation for complaint. They make the court process the punishment for complaints.
Qwen3.8-27B reportedly went from 82 tokens/s to 381 tokens/s on a single RTX 3090 with 24GB VRAM.
No GPU upgrade. No hardware replacement.
The developer achieved roughly 4.6× the original generation speed by changing how the model handles decoding and reuses information from its input.
The performance progression:
• Initial setup: ~82 tok/s
• Optimised MTP: ~114 tok/s
• DFlash2 + context lookup: ~138 tok/s
• Optimised lookup verification: ~381 tok/s
The final jump is especially interesting because it combines speculative decoding with a technique that takes advantage of text already present in the prompt.
1. DFlash2 reduces the cost of sequential decoding
A standard autoregressive model generates one token at a time. Each new token depends on the tokens generated before it.
That sequential process limits how quickly output can be produced.
Speculative decoding takes a different approach. A draft mechanism proposes several tokens ahead, then the main model verifies those proposals.
When the proposals are accepted, multiple tokens can be produced without requiring a separate full decoding step for each one.
DFlash2 uses this approach to reduce the number of sequential generation steps.
2. Context lookup avoids regenerating text that already exists
This is where the developer found another opportunity to improve performance.
Imagine giving Qwen3.8-27B a 25K-token document and asking it to reproduce a section of that document.
The expected output may already exist somewhere in the input. Generating every token again would involve doing work that could potentially be avoided.
Context lookup searches the existing prompt for matching sequences, proposes them as candidate output and lets the main model verify them.
The developer optimised the verification process to handle blocks of up to 16 proposed tokens, compared with seven in the earlier setup.
The reported acceptance rate was approximately 15 out of every 16 proposed tokens.
That high acceptance rate makes a substantial difference when the output closely matches the source text.
On the reported document-reproduction workload, the results were:
• Previous DFlash2 setup: ~260 tok/s
• Optimised context lookup: ~382 tok/s
There is an important distinction here.
381 tok/s is not the model’s normal conversational speed. The developer reports approximately 133 tok/s for ordinary chat workloads.
Context lookup is particularly effective when the expected output overlaps heavily with the input. It won’t provide the same acceleration when the model is writing original content or solving a problem that requires mostly new text.
3. Prefix caching cuts repeated prompt processing
The developer also improved performance when asking multiple questions about the same large document.
Normally, a new request containing that document may require the system to process the shared text again.
Prefix caching allows it to reuse computations from the previous request when the prompt prefix remains unchanged.
In the reported 25K-token document test, time to first token dropped from 22.4 seconds to just 0.56 seconds.
That’s approximately a 40× reduction in waiting time for this repeated-prefix scenario.
The system still processes the new question and generates a fresh answer. It simply avoids repeating much of the computation associated with the shared document.
Where these techniques become useful
The combination is particularly relevant to workloads involving:
• Large-document processing and extraction
• Retrieval-augmented generation
• Repeated questions about the same source material
• Code transformations and repository workflows
• Tasks that reuse or reproduce existing text
The three optimisations target different bottlenecks.
DFlash2 reduces sequential decoding steps. Context lookup finds reusable text in the prompt. Prefix caching avoids recomputing an unchanged prompt prefix.
just friggin WIN THE WAR the old fashion way - WAR 101 - whoever gets the other side to admit total and unconditional defeat and surrender is the winner and then TAKE OVER and run the damn place so it can finally be a place of peace for those left who decide to abandon their evil ways.
they will just move everything to UAE or something where there is real police protection (and government power over everything you do if they so choose) I hear communist china is pretty safe for stores now days too - less looting and rioting and invaders = safe population right?
Run UNCENSORED DeepSeek-V4.1-Flash-1017 on a 12 GB GPU 🔥
Measured, refusals 85%→0% even in thinking, 3 sizes
64GB RAM + SSD via Strata
Get quants here 👇
https://t.co/c6OcKkvC6M