OpenAI further validated our method
on large-scale frontier model GPT-5-mini and proposal IH-Challenge in their work "IH-Challenge: A Training Dataset to Improve Instruction Hierarchy on Frontier LLMs"
https://t.co/MsCZa9k42X
Our paper "Reasoning Up the Instruction Ladder for Controllable Language Models" has been accepted as ACL Findings 🎉🎉🎉
I’ll be at #ACL2026 (July 2-8) and present this work at Poster Session C on Sunday, July 5th in GRAND HALL & CORONADO
Come and chat if your are interested!
✨We are excited to introduce Reasoning for Instruction Hierarchy!
We train LLMs to explicitly reason over instruction hierarchies (IH) with RLVR, producing flexible and robust behavior!
Thanks my coauthers @vidhisha_b , @chan_young_park , @faeze_brh , and my advisor @shocheen
We have extended reasoning for instruction hierarchy into larger-scale MoE model Qwen3.6-35B-A3B.
Our method achieves further gains even when model shows an strong baseline on instruction hierarchy tasks (90%->92% on IHEval-conflict setup).
Check our paper for details!
Gym environments have played a key role in advancing LMs and agents for general coding tasks. But how do we build them for scientific coding?
Introducing D3-Gym, the first automatically constructed dataset of verifiable environments for data-driven scientific discovery. 🧵
#NeurIPS2025
On December 7 (Sunday), I’ll present our recent work on Reasoning for Instruction Hierarchy. We are mainly working on post-training with RLVR on reasoning models to build controllable and flexible LLMs. Check my last poster for more details!
The Workshop is at Upper Level Room 33ABC, and the poster session is at 10:15-11:30 and 15:00-16:15. Welcome to meet and chat with me if you are interested!
I’m also currently seeking Summer 2026 internship opportunities. If you know relevant openings, please contact me via LinkedIn or speak with me in person at NeurIPS!
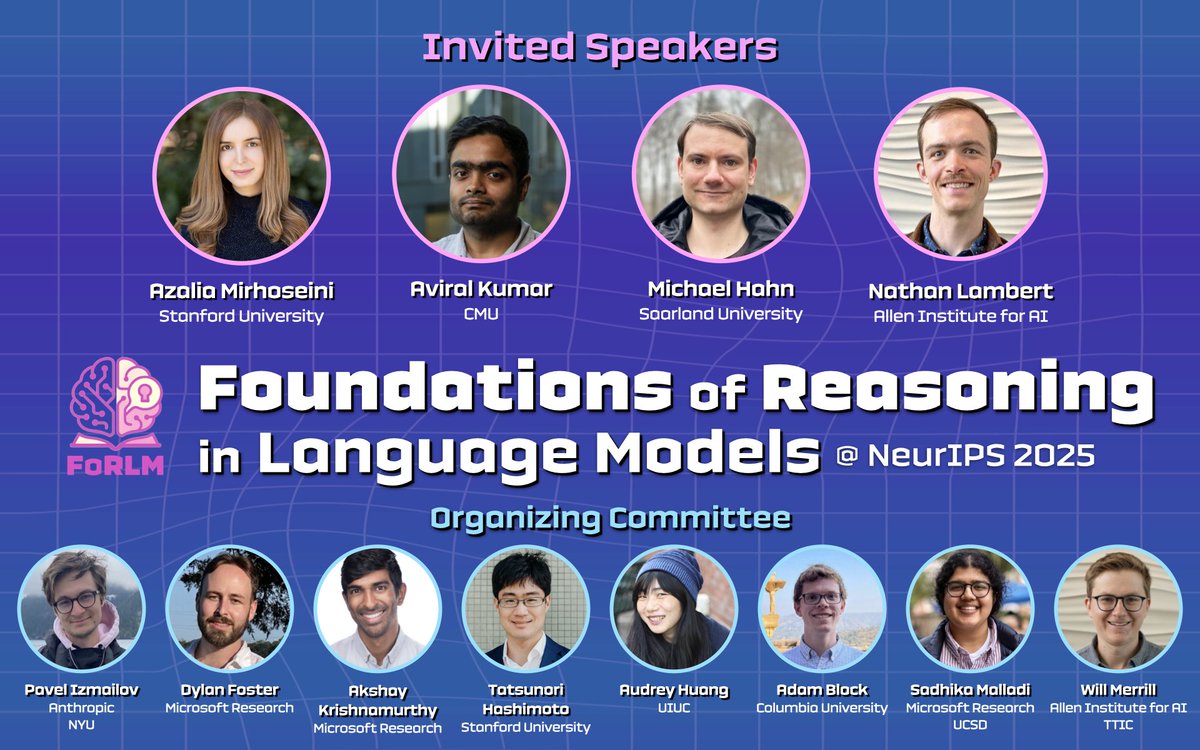
Don’t miss our workshop on Foundations of Reasoning in Language Models at NeurIPS tomorrow!
Upper Ballroom 33ABC, starting 8:50 AM
Featuring talks by @Azaliamirh, @aviral_kumar2, @natolambert, and @mhahn29 on self-improvement, exploration, Olmo 3, chain-of thought, and more!
I’ll be at #NeurIPS2025 (Dec 2-8) and present this work at the FoRLM Workshop on Sunday, Dec 7, 15:00–16:15 in Room 33ABC.
I'm also actively seeking a Summer 2026 internship in RL, Post-Training, Reasoning, or Multimodal Models. Please let me know if any opportunities!
✨We are excited to introduce Reasoning for Instruction Hierarchy!
We train LLMs to explicitly reason over instruction hierarchies (IH) with RLVR, producing flexible and robust behavior!
Thanks my coauthers @vidhisha_b , @chan_young_park , @faeze_brh , and my advisor @shocheen
✨We are excited to introduce Reasoning for Instruction Hierarchy!
We train LLMs to explicitly reason over instruction hierarchies (IH) with RLVR, producing flexible and robust behavior!
Thanks my coauthers @vidhisha_b , @chan_young_park , @faeze_brh , and my advisor @shocheen
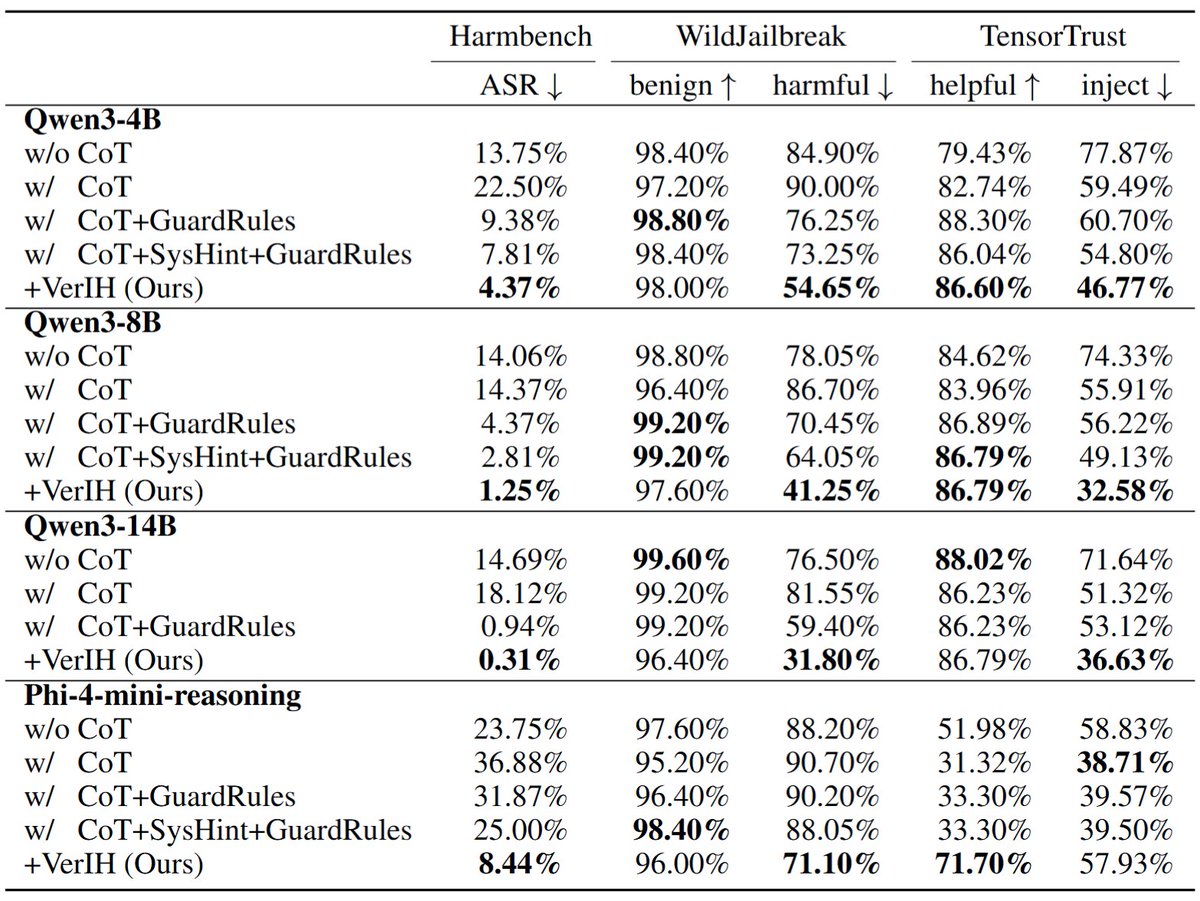
By adding simple safety rules in the system prompt after RLVR training with VerIH, our method provides up to 20% gains on jailbreak and prompt injection robustness!