The intelligence frontier keeps advancing every day. Are your agents delivering better outcomes on what matters?
For enterprises, the promise of agents is more work completed reliably, with less human intervention and a lower cost per successful task.
Today, we’re launching @neosigma_ai and our mission to empower every organization to build their own sovereign intelligence lab.
A place to operationalize their knowledge, replay real work, and optimize agents against the outcomes that matter to their business. Where production experience compounds into intelligence the organization owns.
We’re starting with NeoEval, our automated evaluation engine. It turns your production data into evaluation environments - that dynamically evolves along with your users, workflows, and frontier.
A playground for evaluating and optimizing your agents.
Your data. Your institutional knowledge. Now operationalized into evals and compounding intelligence.
Stay tuned for the next few days of updates from NeoSigma.
I have no doubts, we will continue to push the boundaries and continue to release incrementally capable models.
But personally, Rnj-1 will always be my cute code-oholic 8b 😊
Over a week ago, we at @essential_ai released RNJ-1, a world-class 8B model for code and math.
It’s now ranked #1 and #8 in text generation on Hugging Face.
📥 Instruct: 447k downloads — enthusiasts running the model locally, and providers enabling access to it.
📥 Base: 139k downloads — with businesses and researchers building on top of it.
As a grad student reading the SWE-bench paper in 2023, the idea of a model solving real software engineering tasks felt almost magical.
Today, we have an 8B model running at 20 tok/s on my MacBook, performing on-par with closed models like Gemini and GPT-4o.
Very proud of the entire team ✨
> We deliberately kept post-training limited to allow for further specialization by the community. As an indicator of the untapped potential of the models we report pass@{1,2,4,8} for hard codegen, agentic, and math benchmarks.
Cool! Exciting release.
.@essential_ai's rnj-1 model is now on Ollama!
ollama run rnj-1
8B parameter, open-weight dense model trained from scratch. The model is optimized for code and STEM with capabilities on par with other state of the art open-weight models.
Let's go! 🚀🚀🚀
Happy to share what I've been cooking over the past months as a part of a stellar team at @essential_ai labs: we bring to you Rnj-1 (h/t Ramanujan), the best USA 🇺🇸 open-source LLM in the 8B category - fully pretrained, midtrained, and posttrained from scratch on zettaflops of AMD (one of the largest AMD training clusters in the world) and TPU compute!
We are releasing our base model, and our post-trained checkpoint on HuggingFace - to help you squeeze the absolute most out of post-training for your particular use case.
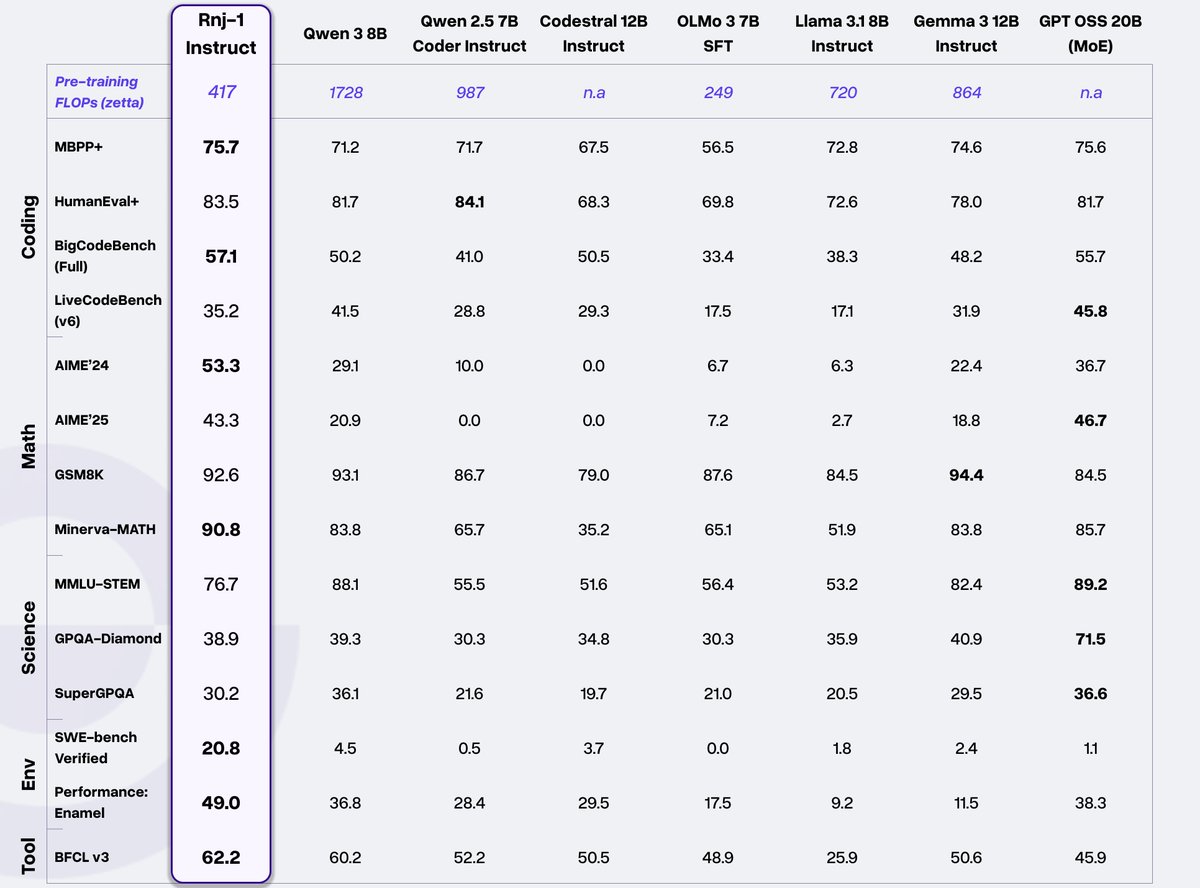
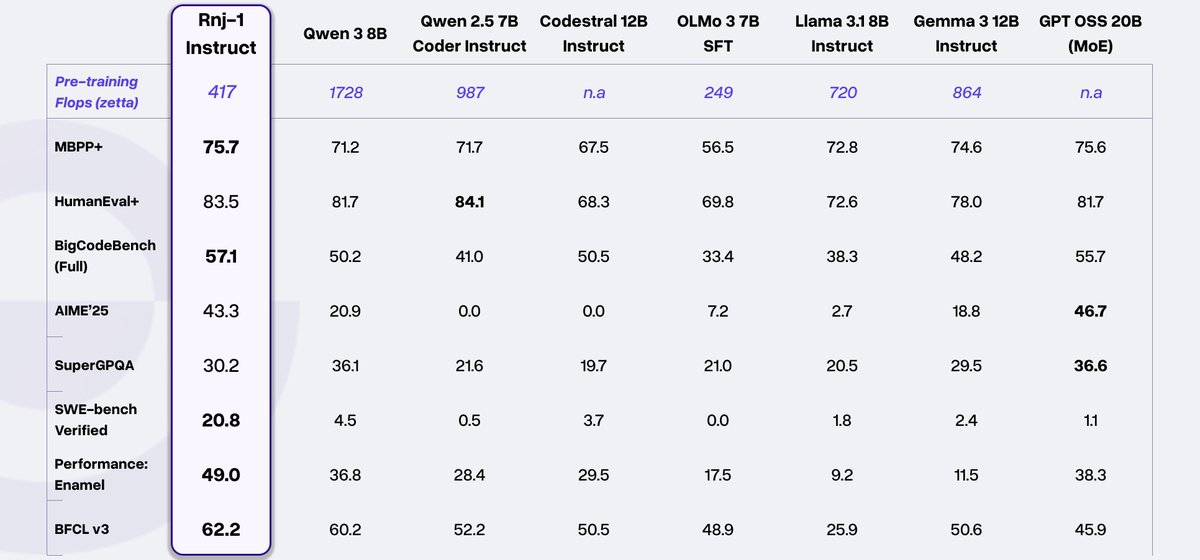
Our initial evaluations show that Rnj-1 is very strong at code, math, and tool calling.
On SWE-Bench it's an order of magnitude stronger than comparably sized models - It scores 20.8% on SWE-bench Verified in bash-only mode, which is higher than Gemini 2.0 flash and Qwen2.5-Coder 32B Instruct and on par with GPT-4o (!) under the same agent framework.
Rnj-1 was pretrained on 8.4T tokens with 8k ctx len. Followed by 380B tokens in midtraining, and a 150B SFT stage to get rnj-1-instruct. We used Muon as the optimizer. Tech report coming soon, but see our blog until then.
As the AI world drifts to whatever "the current thing" is (at this moment in time that's RL), we're going back to first principles and focusing squarely on pretraining. We believe that many behaviors people assume only emerge during post-training can actually emerge during pretraining -> if you cook the model the right way. :)
On a side note - being part of a very small (~20 members of technical staff), tightly knit, hard-working, extremely ambitious team that's working in the same physical space (!!!) is so fun. I was in the office until 2:30 a.m. last night pushing out our latest eval numbers, and a few of my colleagues pulled an all-nighter to help prepare for today's launch!
Due to our size, and my background, I feel I’m in a rare position (looking at the AI labs LLM landscape as a whole) because i got to work on the whole LLM pipeline: from our infra, in-house Spark pipelines, and the data analysis engine (did i tell you to look at your f***ing data already?) to data collection/synthesis, data mixing, training experiments, and - last but not least - evals.
As a bonus, getting to distill tokens from @ashVaswani on a daily basis is rewarding (we met at a small event w Satya earlier this year).
Conspicuously missing from our upcoming tech report are any Transformer modifications, which might come as a surprise given our team.
It’s all about research taste and making bets - in our case, that is pretraining, simulating program behaviors..
The easiest way to run Rnj-1:
* laptop -> llama.cpp or transformers
* your infra -> vLLM, Sglang
* IDEs and Agents with Cline extension -> vs code / Cursor or try claude code router
Happy to see what you build with it! My dms are open.
It's a good model, sir. 🫡
Today, we’re excited to introduce Rnj-1, @essential_ai's first open model; a world-class 8B base + instruct pair, built with scientific rigor, intentional design, and a belief that the advancement and equitable distribution of AI depend on building in the open.
We bring American open-source at par with the best in the world.
Essential-Webv1.0 has reached close to 600k downloads. 🥇
It is now available on the Registry of Open Data on AWS - https://t.co/LdUrt7qRr4 under the Open Data Sponsorship Program for publically available high value datasets.
Paper: https://t.co/SqHXWYh8NH
@essential_ai