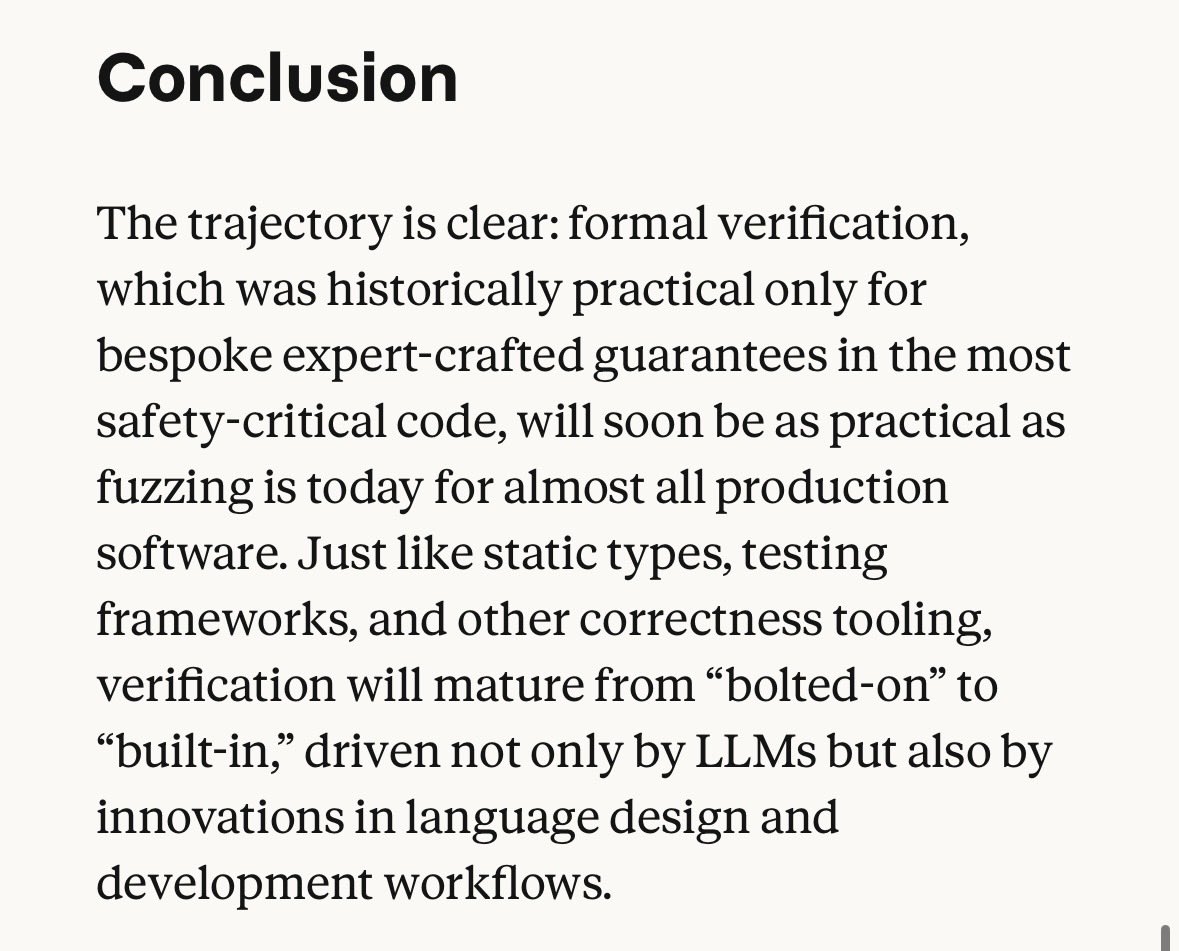
Idk if this is true or not but it's really funny that anthropic is rediscovering the hard lesson of formal specification(it's not necessarily the formal part, it's the specification part)
One heartening thing about the @AnthropicAI + @theoremlabs verification work: almost every PL researcher on my feed is excited about the future and seeing years of research put to use. Quite a contrast to the “AI is taking our jobs” mood I’ve seen in other communities.
In 2005, Penn PLClub and friends asked:
"How close are we to a world where every paper on programming languages is accompanied by an electronic appendix with machine-checked proofs?"
https://t.co/JZyg26Nt2m
I guess the answer was... about 21 years.
Everybody's larping by using formal verification but nobody knows what does it even verify.
There's no "prove me there's no bugs" magic wand as you can't formally define actual boundaries and constraints for most programs.
It's as useless as thousands "smoke tests" that test nothing.
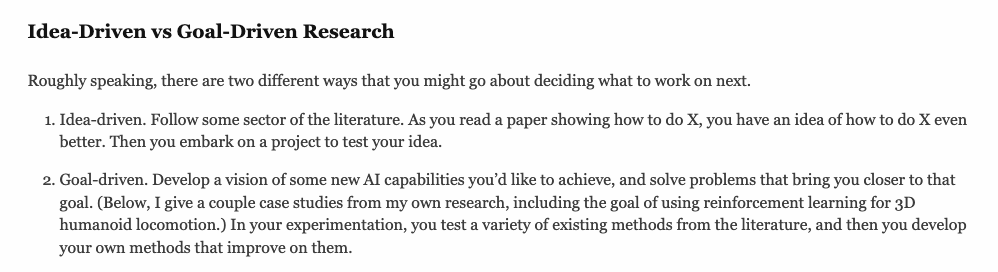
John Schulman (co-founder of Thinking Machines and OpenAI) wrote that goal-driven research beats idea-driven research.
I realized it's also really good life advice.
Don't chase what other people are doing. Figure out what life you want, and then figure out how to get there.
Your gaming PC can now serve frontier models at interactive speed using official checkpoints without extreme quantization!
Qwen3.6 35B → 8GB RTX 4060 laptop @ 39 tok/s
DeepSeek-V4-Flash 284B → RTX 5090 desktop @ 22-25 tok/s
GLM-5.2 753B → RTX PRO 6000 workstation @ 15 tok/s
Run your claude code or codex now with frontier model for $0
Meet FreeToken 🧵
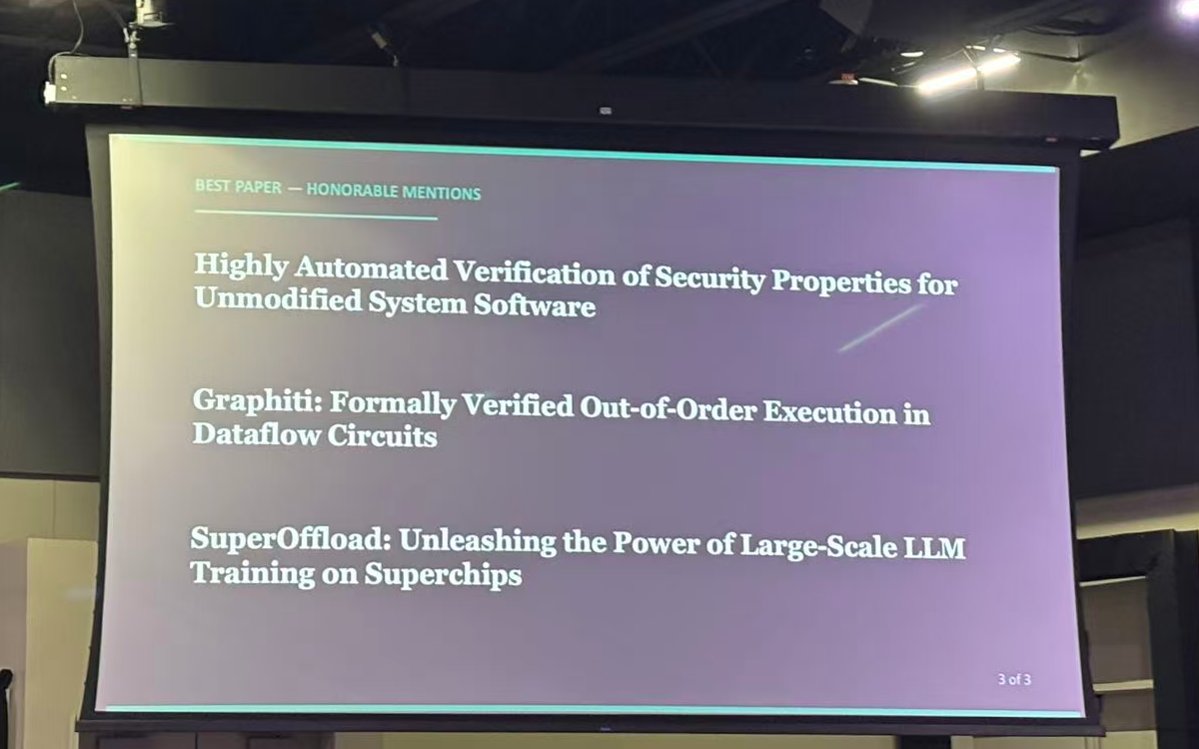
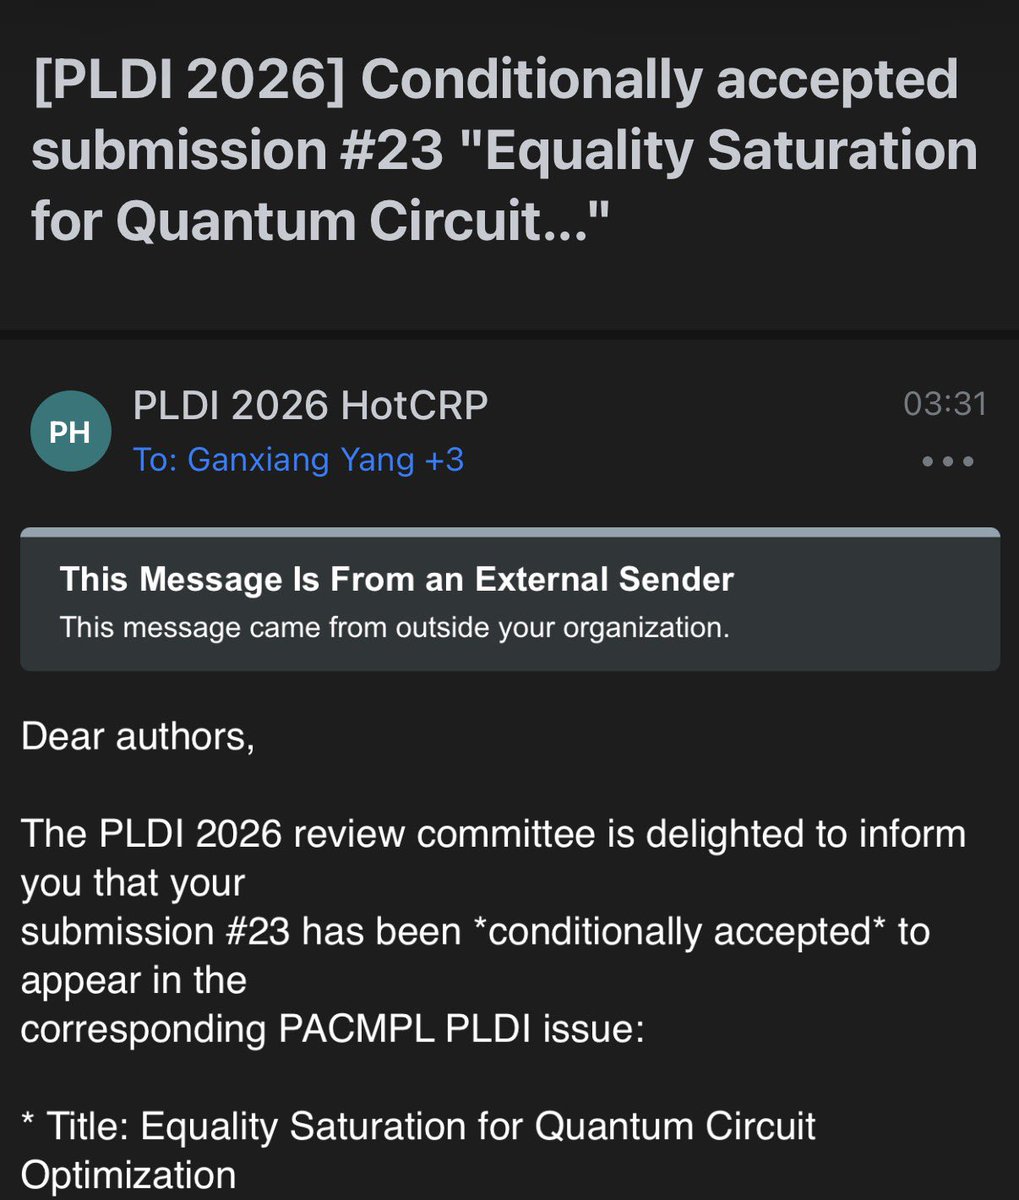
My PhD student Ganxiang Yang present our Quasar work at PLDI on Quasar, a new quantum circuit optimizer that can generate an optimal circuit under a user-specified limit on rewrite iterations.
@CertiK
Flash-KMeans was only the beginning.
Today, from the Flash-KMeans team, we are releasing FlashLib — a GPU library for fast, predictable, agent-ready classical ML operators.
Up to 26× on KMeans, 19× on KNN, 40× on HDBSCAN, 208× on TruncatedSVD, 47× on PCA, 147× on exact t-SNE, and 49× on MultinomialNB over state-of-the-art (cuML).
Blog: https://t.co/P31SGl0cyT
Code: https://t.co/9nkO2hmeOl