I’ll be in my hometown Guntur sometime next week for few days. Anyone on my TL from there and are into AI research? I’d love to chat and offer any guidance. 🙂
(Appreciate retweets to reach some right folks!)
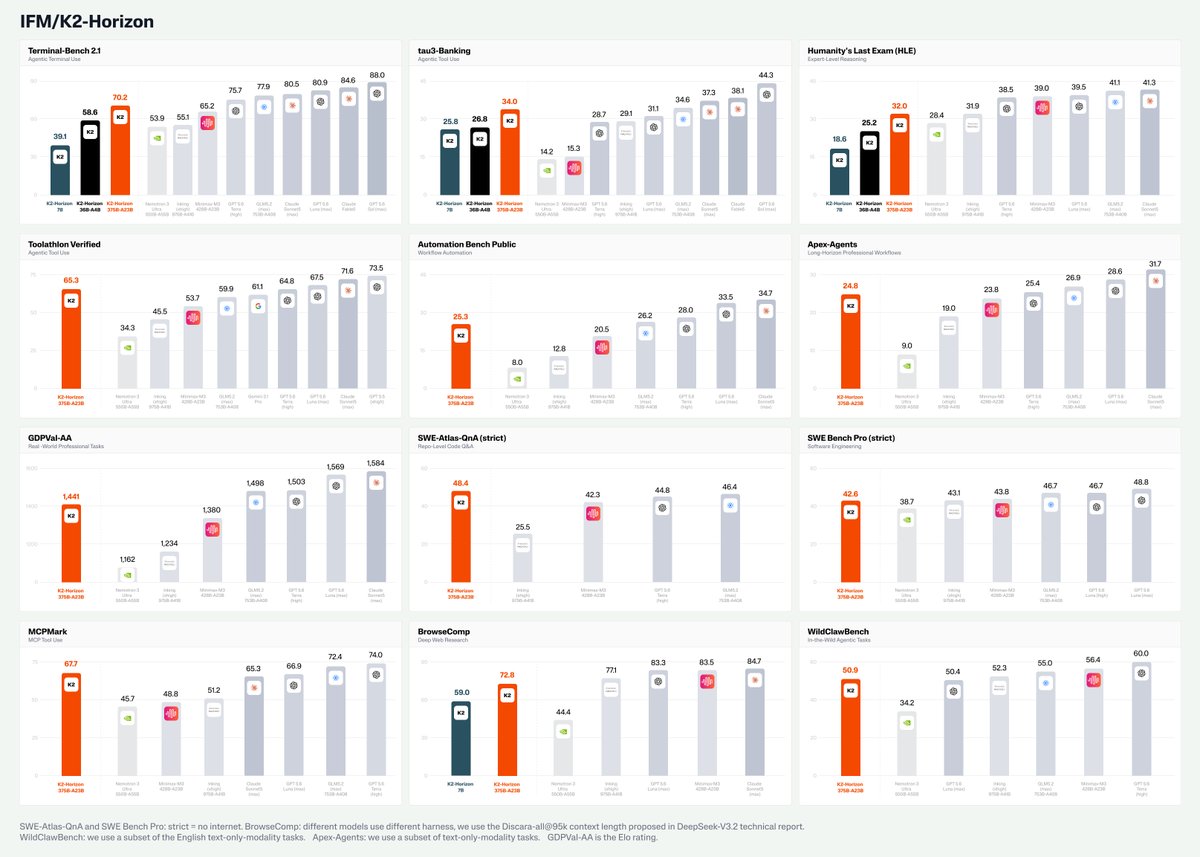
Introducing K2 Horizon: a connected fleet of six foundation models ranging from 0.9 billion to 375 billion parameters.
- Frontier performance: Across coding and agentic tasks, K2 Horizon delivers top-tier performance in every size class—with the 0.9B, 3.7B and 7B models setting new state of the art at their respective scales.
- Radical openness: K2 Horizon represents the largest fully open-source model launch in AI history. The fully open code, training data and recipes are a significant step forward in transparency.
Launch page: https://t.co/gg0k803SbL
Tech blog: https://t.co/g35L5xMGdS
Hugging Face: https://t.co/3Lb28JhyG9
K2 Horizon 375B A23B, a new open weights model from UAE's MBZUAI, scores 47 on the Artificial Analysis Intelligence Index, with relatively strong agentic performance and a 30 point jump over its predecessor
K2 Horizon 375B A23B is an open weights Mixture-of-Experts model with 375B total and 23B active parameters from @IFM_MBZUAI, MBZUAI's Institute of Foundation Models. It scores 47 on the Intelligence Index, alongside models such as MiniMax-M3 (45, also a MoE with 23B active parameters), and a large upgrade from its predecessor K2 Think V2 (17, 70B dense model). It leads nearby open weights models on agentic evals and has a low hallucination rate, but trails on knowledge and the hardest reasoning evals. K2 Think V2 ranks among the most open models on our Openness Index; MBZUAI is updating the supporting documentation and code for K2 Horizon and we expect to add it to the Openness Index soon.
Key takeaways:
➤ Strong on agentic tasks, weaker on knowledge and deep reasoning. MiniMax-M3, a recent model that is close to it on the Intelligence Index, makes the cleanest comparison: K2 Horizon 375B A23B leads on GDPval-AA, our real-world knowledge work benchmark (Elo 1430 vs 1380), and on τ³-Banking (34.2% vs 15.3%), but trails on GPQA Diamond (87.3% vs 92.9%) and Humanity's Last Exam (32.0% vs 39.0%)
➤ Low hallucination rate, driven by abstention rather than knowledge. K2 Horizon 375B A23B attempts only 40% of AA-Omniscience questions, declining the remaining 60% rather than guessing. The result is a 26% hallucination rate, among the lower rates we have measured, while accuracy is 18%, essentially unchanged from K2 Think V2
➤ A new architecture over its predecessor. K2 Horizon 375B A23B is a 375B parameter Mixture-of-Experts model with 23B active, succeeding the 70B dense K2 Think V2, and extends context from 262K to 512K tokens. Its 23B active parameters match MiniMax-M3 (428B total, 23B active)
Key model details:
➤ Architecture: Mixture-of-Experts, 375B total parameters, 23B active
➤ Context window: 512K tokens
➤ Multimodality: Text input and output only
➤ Pricing and availability: Yet to be announced
➤ Licensing: Open weights (license details to be announced)
K2-Horizon has day-0 support in vLLM, and IFM released intermediate checkpoints, detailed data-construction recipes, the training code, and fine-grained logs alongside the weights. 📷
512K context and Apache-2.0 from 3.7B up, with reasoning and tool calling in the checkpoints for agents and long documents.
vLLM runs the whole family, from local to large-scale data centers. Prototype on the small end, scale up without changing the stack.
Thanks @IFM_AI for opening all six and every stage that led to them, not just the last checkpoint! 📷
📷 https://t.co/JgteusHkLp
Introducing K2 Horizon: a connected fleet of six foundation models ranging from 0.9 billion to 375 billion parameters.
- Frontier performance: Across coding and agentic tasks, K2 Horizon delivers top-tier performance in every size class—with the 0.9B, 3.7B and 7B models setting new state of the art at their respective scales.
- Radical openness: K2 Horizon represents the largest fully open-source model launch in AI history. The fully open code, training data and recipes are a significant step forward in transparency.
Launch page: https://t.co/gg0k803SbL
Tech blog: https://t.co/g35L5xMGdS
Hugging Face: https://t.co/3Lb28JhyG9
Built a tiny diffusion LM in JAX/Flax.
Start with masks, denoise with a bidirectional Transformer, reveal tokens step by step.
Early, but the mechanics are much easier to reason about.
https://t.co/9QTWlXsX1h
🧠 the Digital Brain Project is now live:
$5M total · up to $500k per selected team
Let's open-source the modeling of the human brain brain activity!
➡️Apply on: https://t.co/W4HFA5PQBX