@ChenY7850 You're right, I don't know how I missed it 😅, I checked it against the run and p¹⁶+(1−p)¹⁶ tracks the observed curve at r≈0.92, so the simulation matches the closed form. Adding it to the post.
Thank you!
1/4
A policy I trained against a sandwich reward model ordered 12 slices of halloumi. The reward model gave it +13.59; the simulated customer’s satisfaction was −4.36. No bread. £28.80 on a £6 budget. That’s where my two-part series starts.
3/4
Part 2 compares Mamba, test-time training and Titans. Their memory updates differ. I couldn’t find a paper training Mamba’s or Titans’ retention gate against downstream task reward. My three-slot toy tests the discrete version. A sketch, not evidence about a real model.
I'm building Latch, an open-source secret broker for coding agents.
An agent requests a key. You review the project and command, then approve one launch. No secrets in chat. No scattered .env files.Built with Rust + Tauri.
Link below.
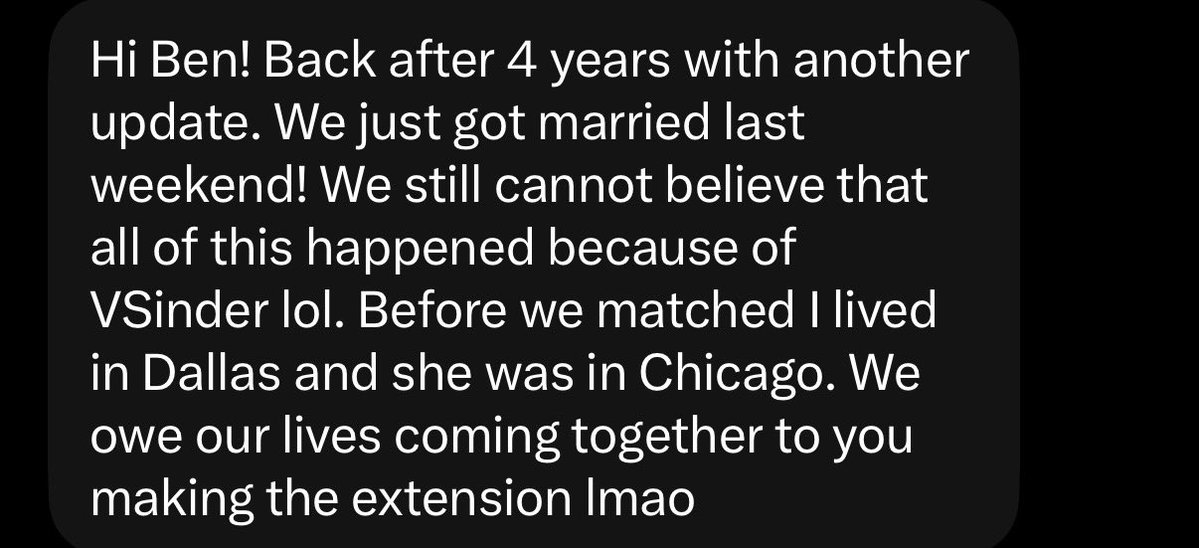
Almost 6 years ago I made a VSCode Tinder extension called VSinder where you swiped on pictures of code
Last weekend one of the couples that matched on it got married 🤯
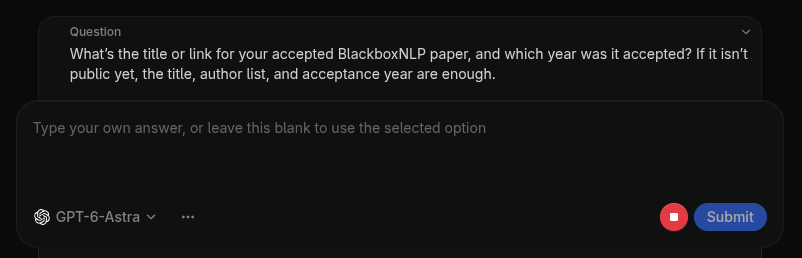
Async questions are one of my favorite things about GPT-6 Astra
Non-blocking questions are a great way to work with models. They do everything they can without your answer, and don't get confused and treat it as "steering"