Introducing Canto, our latest speech model for real-time dictation.
On our evaluation of 9.8 hours of English Flow dictations from more than 2,300 speakers, Canto achieved a 3.4% word error rate��the lowest among the models we tested.
Learn more about Canto from our CSO, Ariya Rastrow:
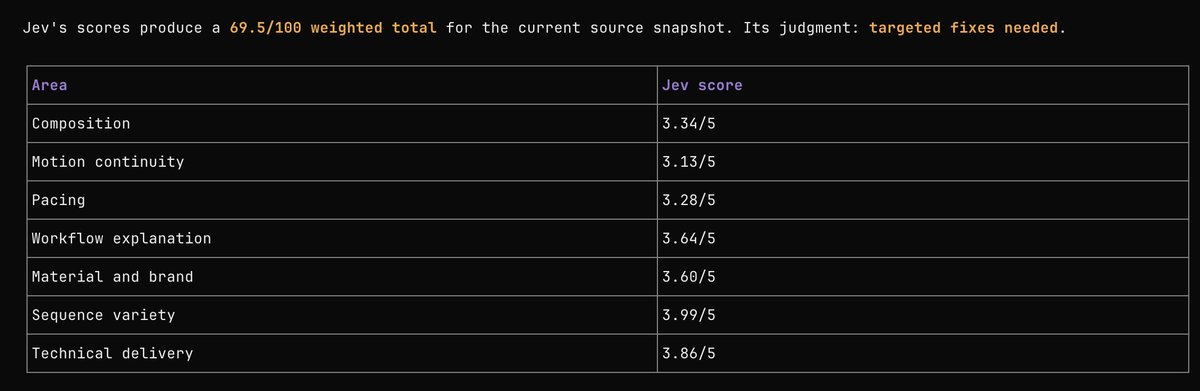
Trying out Jev to see if better eval scores can actually lead to better video production quality.
Not fully sure this is the right approach yet,let’s see if the numbers translate to pixels..
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
@geekyboiiii if i had actually taken inspiration from yours, i’d have no problem giving credit. genuinely hadn’t seen it before… probably for the best though, mine somehow ended up 10x better
These were some of my initial references for the website. Pretty happy with how it turned out , and with all the love it’s been getting :)
Will share the detailed process and the final website link soon!