@michael_nielsen@JamesGleick Not exactly what you're looking for but this audio of Feynman might be of interest to you https://t.co/JwpqwLVGne. It includes him describing his thoughts on people building a bridge in a world with nuclear weapons like in your previous tweet.
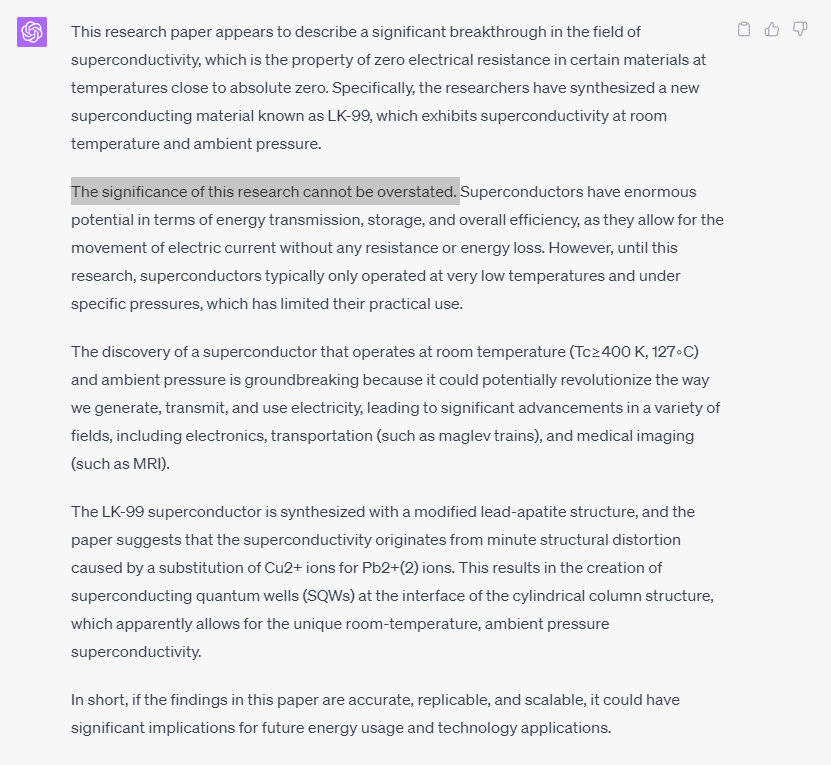
@MikePFrank One of the first things I did when I saw it popping up in my feed was feed it the abstract:
https://t.co/yk2U9aQxfQ
I liked "The significance of this research cannot be overstated" but I never gave it the whole paper to peer review 😅
@jeremyphoward I'm glad you put this out there. It often feels like a lot of Machine Learning and AI experts really don't know what they don't know when they comment on this topic.
@DivGarg9@Stanford Wow, pretty good line up. This looks like it will be an amazing digest of some pretty big research moments. Thanks for making it public 🙌
@decruz@abacaj Those adjusted guardrails and constraints could be one of the small models Anton is talking about. Also, how do you use GPT4 to make predictions on new data which is too large or fast to fit inside GPT4s context / rate limits. There's plenty of use for small models alongside GPT4
@icreatelife People buying things from Amazon.
'There’s a question that comes up very commonly: “What’s going to change in the next five to ten years?” But I very rarely get asked “What’s not going to change in the next five to ten years?”'
Jeff Bezos
@simonw I remember learning you maintain 185 PyPI packages and that was before ChatGPT.
@amasad speculates we may see 1000x developer productivity increase with ChatGPT.
Therefore you are going to be maintaining 185,000 PyPI packages in 5 years time 😂
@finbarrtimbers Its an incredible dataset. A lot of effort goes into web scraping when people don't realise there is a good chance the data is probably already sitting on S3 in parquet files which anyone can access.
@simonw@HaldemanClaire@benedictevans@ilyasut It learns how to produce useful output from the RLHF and with enough of it he feels they may be able to eliminate hallucinations in the near future.
@simonw@HaldemanClaire@benedictevans@ilyasut talks about that in a few places here https://t.co/txaX4eTcNa. He basically says the language model itself is great about learning representations of the world but can't produce useful output alone.
@iScienceLuvr Nice thread. Its hard to make comparisons with GPT-4 as we don't even know the parameter count but it feels like we are trending towards big baseline models eating the world. The @Microsoft paper shows GPT-4 performing better than Minerva, fine-tuned for Mathematics via PaLM.