IBM just released the R2 generation of their Granite multilingual embedding models for retrieval, and the jump over R1 is very notable.
Two models, both Apache 2.0:
- granite-embedding-97m-multilingual-r2 (384-dim)
- granite-embedding-311m-multilingual-r2 (768-dim)
🧵
🧵Building AI apps rarely means using just one model.
Granite 4.1 brings language, vision, speech, and guardrails together—so you can build real workflows, not just demos.
What devs should know.👇
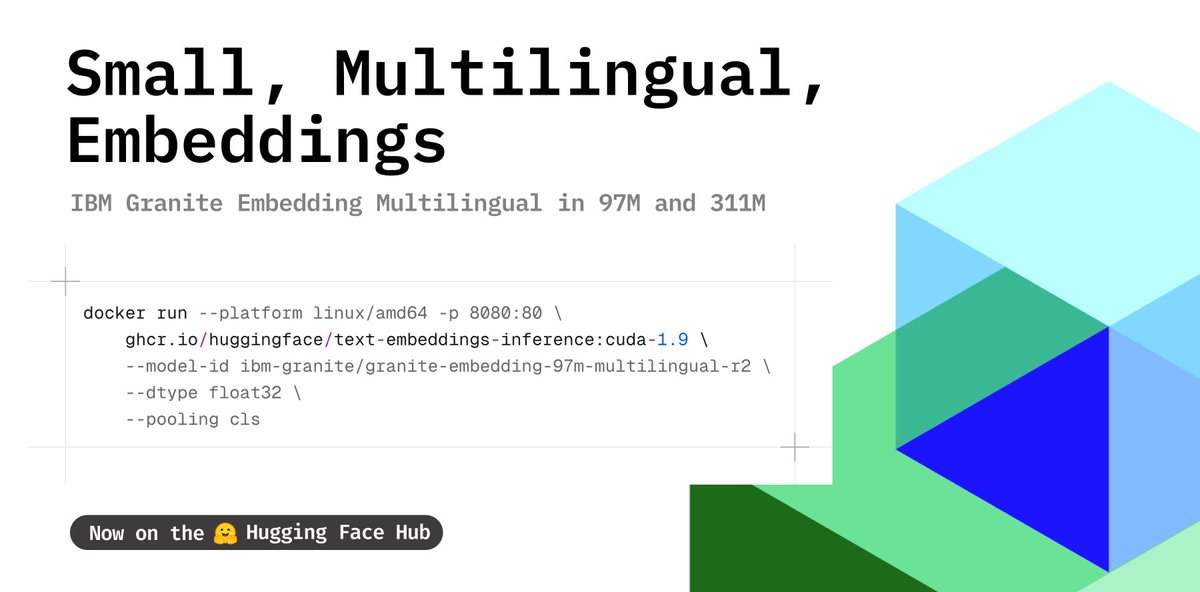
IBM Granite just released two multilingual embedding models with 97M and 311M parameters 🤏🏻
ModernBERT-based, 200+ languages, 32K context, and built for retrieval, search, similarity, and code.
And... day-zero support on Text Embeddings Inference and friends!
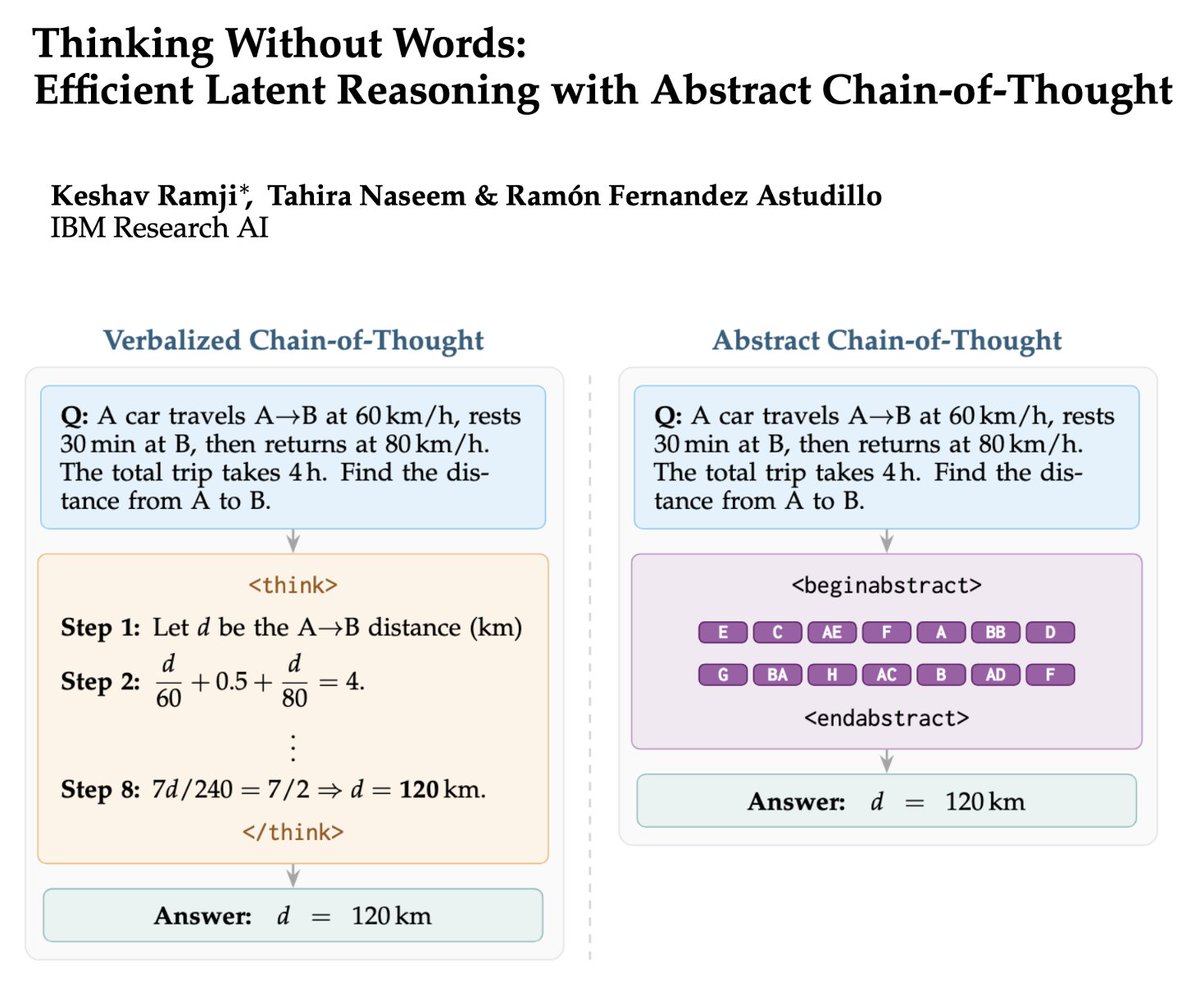
What if your language model could reason efficiently in an entirely new language?
We introduce Abstract Chain-of-Thought, a new mechanism which allows language models to reason through a short sequence of reserved "abstract" tokens through reinforcement learning. It is as performant as verbalized CoT at a fraction of the cost, achieving major gains in inference-time efficiency.
Introducing MTRAG-UN — a new benchmark for the UN parts of multi-turn RAG!
666 tasks, 2,800+ conversation turns, 6 domains — including two new enterprise corpora
📄 Paper: https://t.co/wXgzyEsdjv
💻 Benchmark: https://t.co/qLZvVbQbhV
collab: @vpshah95@lucian_popa_us
Sharing our work on improving long-context text embeddings.
TL;DR: We introduce LMK pooling, a new pooling strategy that improves long-context extrapolation and outperforms existing pooling approaches for dense embedding tasks https://t.co/yWLDcZVFje
Evaluated ModernBERT variants on the FreshStack leaderboard!
(i) GTE (ModernBERT)
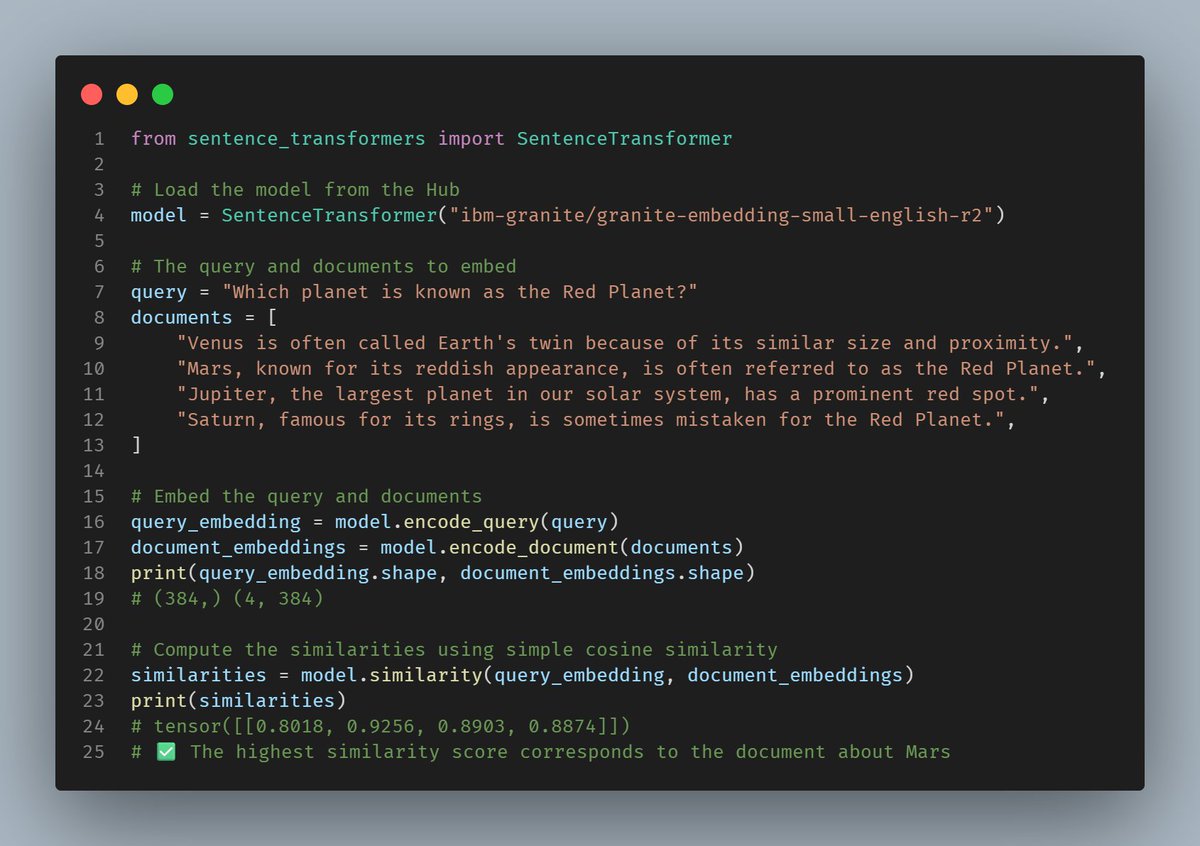
(ii) IBM Granite (and small) english R2
Outperforms Embedding Gemma 300M despite being 149M params.
Poster and other updates coming soon!
The Generative Model Alignment team at IBM Research is looking for next summer interns! Two candidates for two topics
🍰Reinforcement Learning environments for LLMs
🐎Speculative and non-auto regressive generation for LLMs
interested/curious? DM / email [email protected]
The next generation of open-source AI is here. Meet IBM Granite 4.0.
We've engineered these open, performant and trusted small language models to solve key enterprise challenges. Discover how Granite 4.0 delivers exceptional performance while requiring only a fraction of the resources: https://t.co/T9Om1Xk61z
Granite Embedding R2 Models are here!
🔥 8k context
🏆 Top performance on BEIR, MTEB, COIR, MLDR, MT-RAG, Table IR, LongEmbed
⚡Fast and lightweight
🎯 Apache 2.0 license (trained on commercial friendly data)
Try them now on @huggingface 👉 https://t.co/MxtN36YlsN
I really like the look of these, I reckon they would act as solid replacements of older models like all-MiniLM-L6-v2 and all-mpnet-base-v2.
They'll do very solid on retrieval in particular. Very solid work, IBM!
One of the most underrated players in AI models, @IBM, released 2 new extremely efficient embedding models: granite-embedding-english-r2 & granite-embedding-small-english-r2, commercially viable.
Details in 🧵:
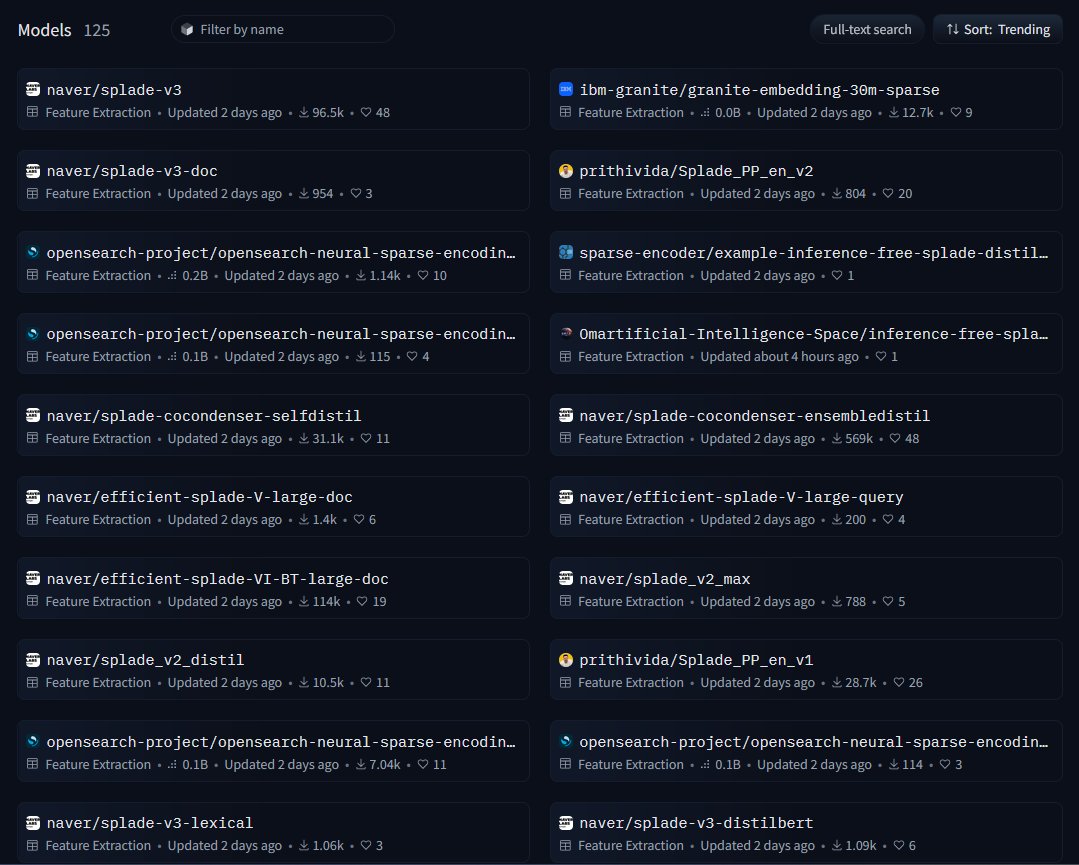
The Sentence Transformers v5.0 release from yesterday immediately integrated many of the strongest Sparse Embedding models from the literature.
You can try them out now, all with the same simple interface, e.g. for your Dense + Sparse => Hybrid Search.
Link in 🧵
🌟New Benchmark! 🌟
Do you work on RAG? Are you interested in Multi-Turn conversations? Very excited to share the new MTRAG benchmark we have released!
Data: https://t.co/KtJQgtB5Uj
Paper: https://t.co/QNRccmrEV5
@danish_c@kpfadnis@chulaka_g@vpshah95@lucian_popa_us
Our final announcement of the year — introducing Granite 3.1
What's new with this version?
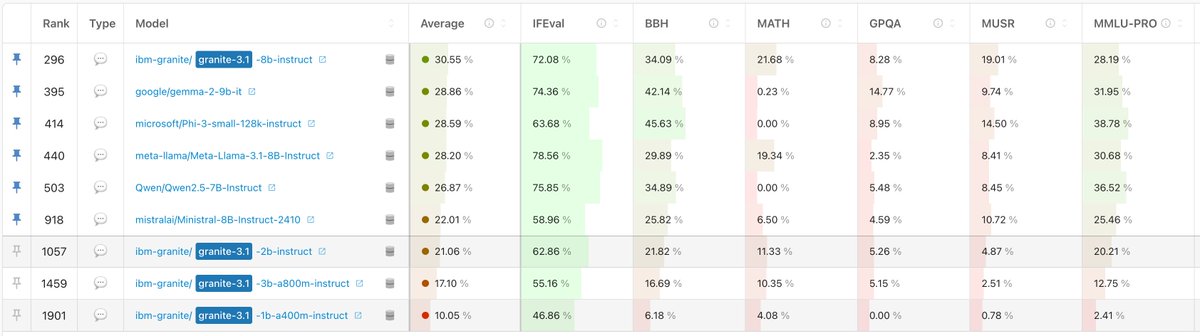
1/ Granite 3.1 8B Instruct delivers significant performance improvements over Granite 3.0 8B Instruct. Its average score across the Hugging Face OpenLLM Leaderboard benchmarks is now among the highest of any open model in its weight class.
2/ We’ve expanded the context windows of the entire Granite 3 language model family. Our latest dense models (Granite 3.1 8B, Granite 3.1 2B), MoE models (Granite 3.1 3B-A800M, Granite 3.1 1B-A400M) and guardrail models (Granite Guardian 3.1 8B, Granite Guardian 3.1 2B) all feature a 128K token context length.
3/ We’re releasing a family of all-new embedding models. The new retrieval-optimized Granite Embedding models are offered in four sizes, ranging from 30M–278M parameters. Like their generative counterparts, they offer multilingual support across 12 different languages: English, German, Spanish, French, Japanese, Portuguese, Arabic, Czech, Italian, Korean, Dutch and Chinese.
4/ Granite Guardian 3.1 8B and 2B feature a new function calling hallucination detection capability, allowing increased control over and observability for agents making tool calls.
5/ All Granite 3.1, Granite Guardian 3.1, and Granite Embedding models are open source under Apache 2.0 license.
6/ These latest entries in the Granite series follow IBM’s recent launch of Docling (an open-source framework for prepping documents for RAG and other generative AI applications) and Bee (an open-source, a model-agnostic framework for agentic AI).
7/ Granite TTM (TinyTimeMixers), IBM’s series of compact but highly performant timeseries models, are now available in https://t.co/VolrF8dKAM
through the beta release of https://t.co/VolrF8dKAM
Timeseries Forecasting API and SDK.
8/ Granite 3.1 models are now available in IBM https://t.co/VolrF8dKAM
and through platform partners, including (in alphabetical order) Docker, Hugging Face, LM Studio, Ollama, and Replicate.
9/ Granite 3.1 will also be leveraged internally by enterprise partners: Samsung is integrating select Granite models into its SDS platform; Lockheed Martin is integrating Granite 3.1 models into its AI Factory tools, used by over 10,000 developers and engineers.
I’m presenting our poster on INDUS: Effective & Efficient Language Models for Scientific Applications at #EMNLP2024 tomorrow from 2:00-3:30pm at Riverside. Drop by to say hi- we have open source models & datasets!
https://t.co/QlQxei6F3K
Joint work between @IBMResearch & @NASA