We’ve lost an icon. Margaret Hamilton, a computer science pioneer best known for her work at MIT leading development of the flight software for the Apollo missions to the moon, has died at 90. Read about her legacy via MIT News: https://t.co/ODkbdIsoHw
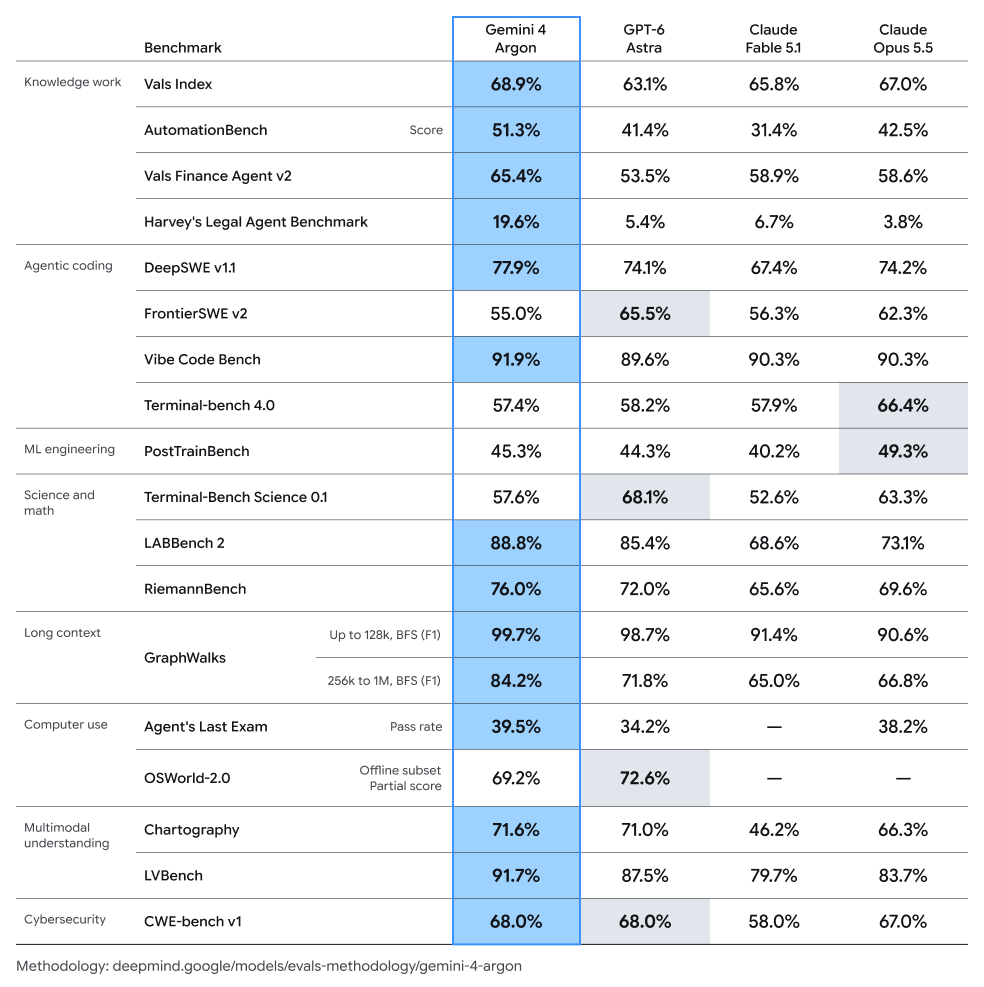
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
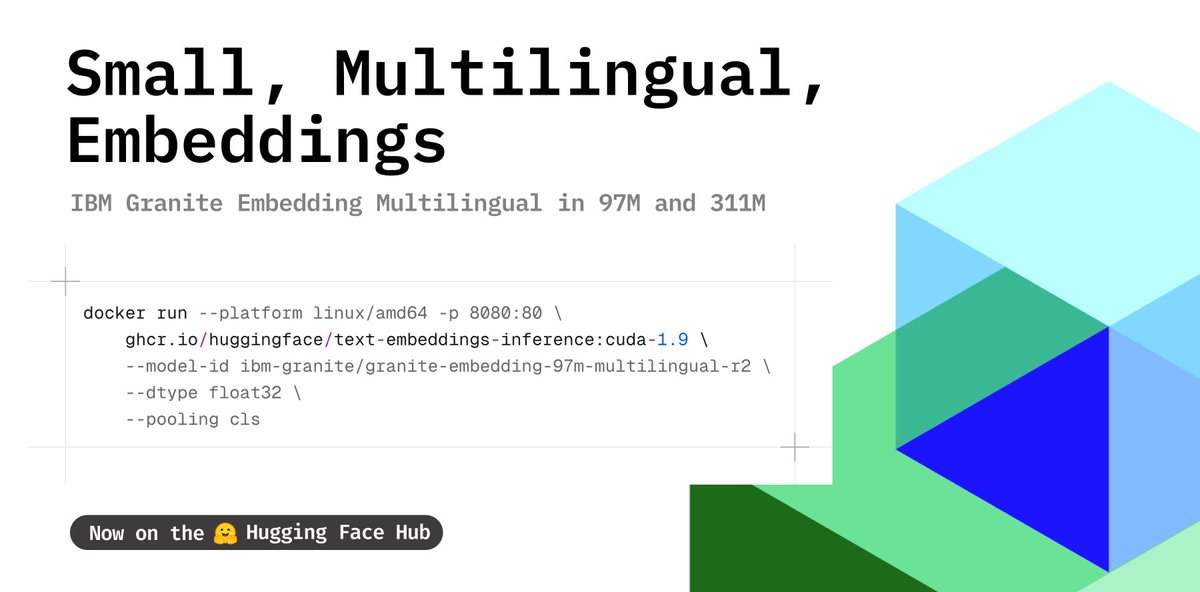
IBM Granite just released two multilingual embedding models with 97M and 311M parameters 🤏🏻
ModernBERT-based, 200+ languages, 32K context, and built for retrieval, search, similarity, and code.
And... day-zero support on Text Embeddings Inference and friends!
Introducing PRISM: Demystifying Retention and Interaction in Mid-Training
The modern LLM training pipeline has evolved beyond just pre-training + alignment. State-of-the-art models now insert a critical middle stage "mid-training" where targeted, high-quality data mixtures build reasoning foundations before RL. Yet despite its growing adoption, the field lacks a principled understanding of what actually drives its effectiveness.
— What data should you use?
— When in the pipeline should you mid-train?
— How does it interact with downstream RL?
— Does it generalize across architectures and scales?
— And beyond benchmarks: what do these stages actually do to the model at the weight and representation level?
These questions don't have clear answers in the literature at scale : and the cost of getting them wrong is significant.
PRISM is our systematic attempt to answer all of these. Using ~27B high-quality tokens, we run controlled experiments across 7 models · 4 families · 3B–24B parameters, spanning both dense Transformers and attention-Mamba hybrids, measuring what mid-training actually does: to performance, to weights, to representations, and to downstream RL.
🧵 Key findings below.
🌐 https://t.co/cZKor1qqKA
📄 https://t.co/Ds3dKGGSYL
🤗 Models and Datasets: https://t.co/XrtHX450Mw (coming soon)
State-of-the-art ColBERT models are trained by applying knowledge distillation on top of dense pre-trained models
What if we run the whole pre-training in the multi-vector?
Introducing ColBERT-Zero, a model that sets a new SOTA on BEIR, using only public data
.@ritivel helps pharma regulatory teams draft FDA submissions like CTDs and INDs in minutes instead of weeks. So life-saving drugs reach patients faster.
Congrats on the launch @tpavankalyan23, Gunin, and Nirmit!
https://t.co/qNMLwQcOiG
Ritivel just launched on @ycombinator's Launch YC!
Ritivel 💊 AI-native platform for Regulatory Document Submission. Check it out: https://t.co/757Pxm3zHX
Sharing our work on improving long-context text embeddings.
TL;DR: We introduce LMK pooling, a new pooling strategy that improves long-context extrapolation and outperforms existing pooling approaches for dense embedding tasks https://t.co/yWLDcZVFje
Evaluated ModernBERT variants on the FreshStack leaderboard!
(i) GTE (ModernBERT)
(ii) IBM Granite (and small) english R2
Outperforms Embedding Gemma 300M despite being 149M params.
Poster and other updates coming soon!
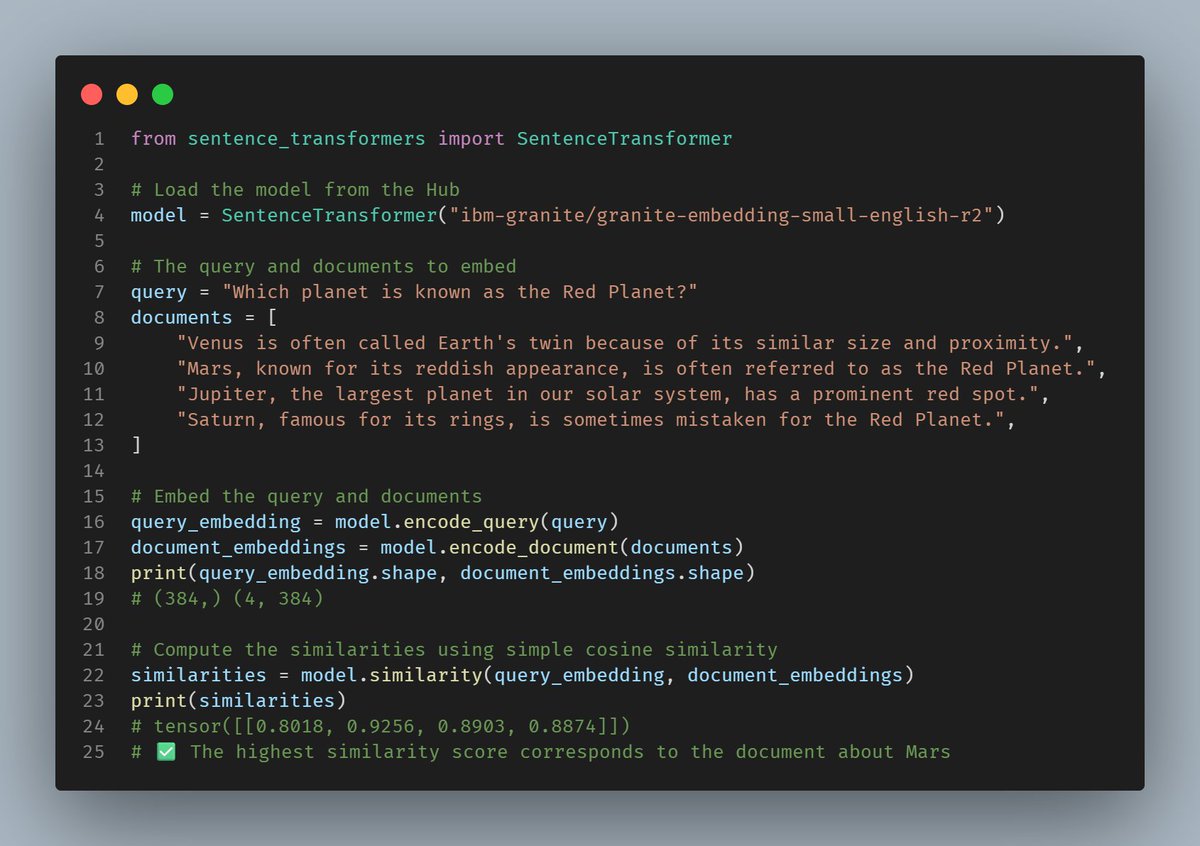
Granite Embedding R2 Models are here!
🔥 8k context
🏆 Top performance on BEIR, MTEB, COIR, MLDR, MT-RAG, Table IR, LongEmbed
⚡Fast and lightweight
🎯 Apache 2.0 license (trained on commercial friendly data)
Try them now on @huggingface 👉 https://t.co/MxtN36YlsN
One of the most underrated players in AI models, @IBM, released 2 new extremely efficient embedding models: granite-embedding-english-r2 & granite-embedding-small-english-r2, commercially viable.
Details in 🧵:
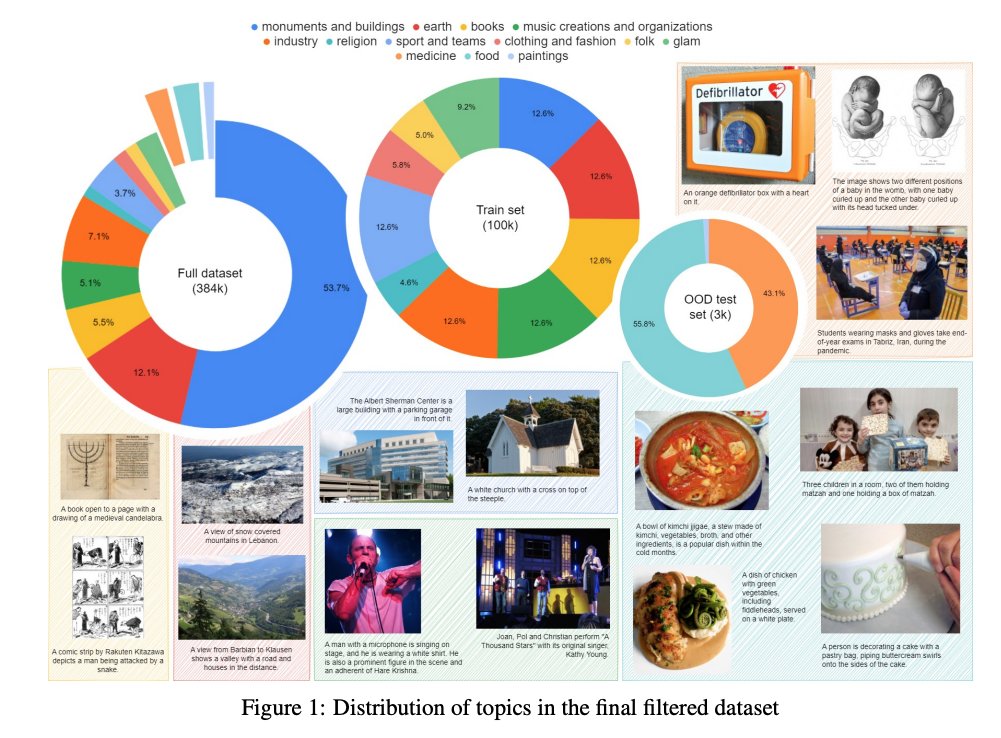
"WikiDO: A New Benchmark Evaluating Cross-Modal Retrieval for Vision-Language Models", consisting of 384K image-text pairs from Wikipedia with domain labels, along with human-verified in/out distribution test sets.
(Kalyan et al, 2024)
https://t.co/ys7gU3eGO9
🚨🚨🚨 New paper on LMs trained with machine translated data!
We all know that billions to trillions of tokens are needed to get the best LLMs. But not all languages have such data.
Q: What to do?
A: Just create it using machine translation!
Paper: https://t.co/QW2lEY08UY
Q: Do you read science type books?
A: I need to read science type books in school.
Does the answer imply that the reader is a "science type book enjoyer"?
Can an LLM understand this?
Can an LLM understand pragmatics?
Our paper titled PUB answers this: https://t.co/XE2uuSZotw