Part 1 of the LLM serving stack: an OpenAI-compatible gateway in front of Ollama, with Prometheus + Jaeger watching the queue.
Same benchmark twice, one backend env var changed. 105 → 218 tok/s aggregate, TTFT at capacity 2.26 → 0.31 s. Gateway code untouched.
Clearest finding: the gateway’s queue is admission control, not batching. It decides who waits. The backend decides whether work is shared.
#LLMOps ⚙️
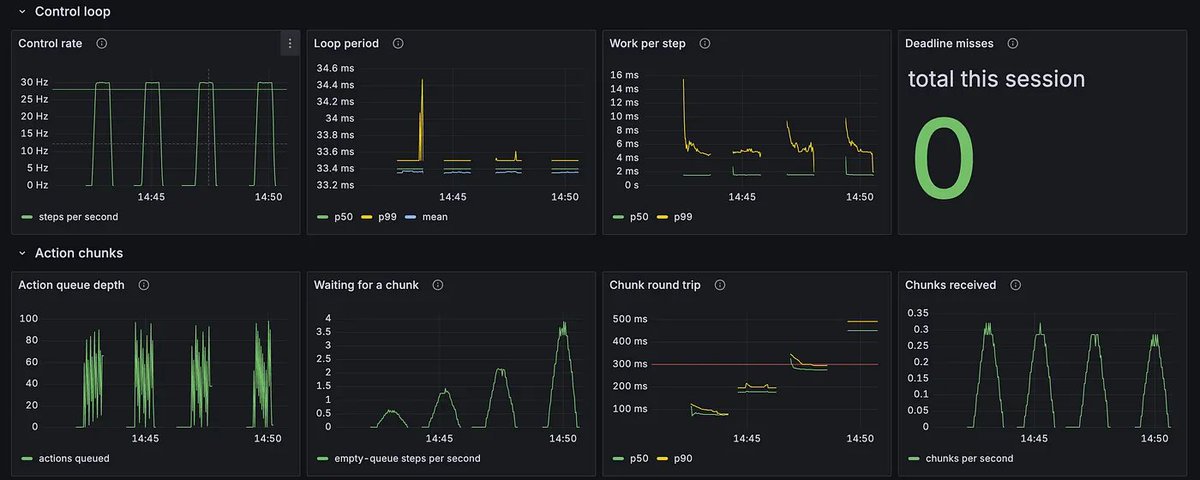
Part 2 of Gurukul: moved my SO-101 arm’s policy into its own server, with Prometheus + Grafana watching both sides.
Same 20-trial test: 9/20 vs 10/20 in-process. Within chance.
Clearest finding: a slow server doesn’t slow the robot down. It makes the robot wait.
#PhysicalAI 🧵
Taught an SO-101 robot arm to put a toy in a bowl by imitation: 45 demos, an ACT policy, 10/20 on the real arm.
Eval rules fixed before trial 1. 6 of 10 failures never grasped the toy, half after nudging it where the training data never went.
Part 1 of Gurukul 🧵
@flcnhvy@RationalEtienne@chrish7985@rlyrlysryDave The news is sometimes created, but always curated. The latter is most pernicious. On any given day, there are thousands of potential stories. By picking which stories are written about & how prominently they’re placed, a handful of publishers control much of the public narrative.