@badlogicgames@SIGKITTEN There was bug in llama.cpp that was recently fixed regarding this: https://t.co/RLGp23vaPv. I cannot speak for other inference engines though.
@mitsuhiko@hampsonw Maybe you already know this, but these reasoning models are trained for "interleaved reasoning" and perform better with thinking on, since traces are retained between tool calls to help "guide" them.
@mitsuhiko@antirez llama.cpp supports tool call parameter streaming for most models. The most common issue I've noticed is clients failing to send reasoning back from prior responses. It's not part of the OpenAI Chat Completions spec, so I understand why, but it destroys model performance.
@simonw The original template drops reasoning between tool calls, which hurts performance. llama.cpp has a custom template that fixes this, and I believe it makes Gemma 4 31B a really good coding assistant for its size.
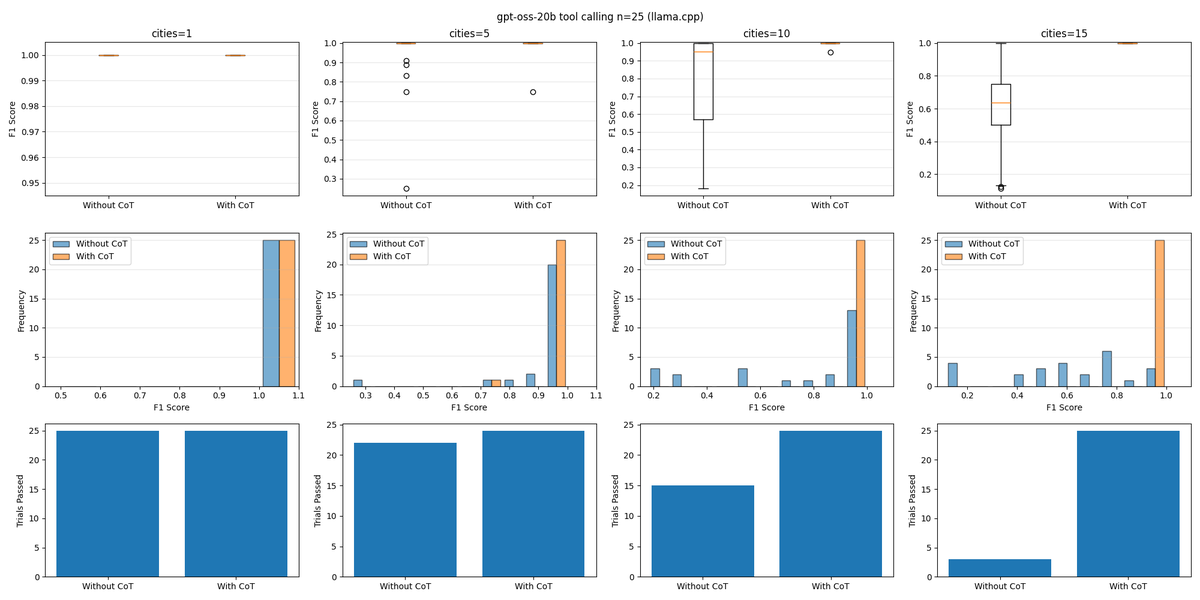
I still see people not using gpt-oss to its fullest by passing along the CoT when tool calling. I did some simple testing to show how bad it performs without it. https://t.co/U5HtMYgXHn
@hkhawaja Ollama provides structured output support in the form of JSON, but that doesn’t help in this scenario. I’m not aware of Ollama supporting custom grammars.
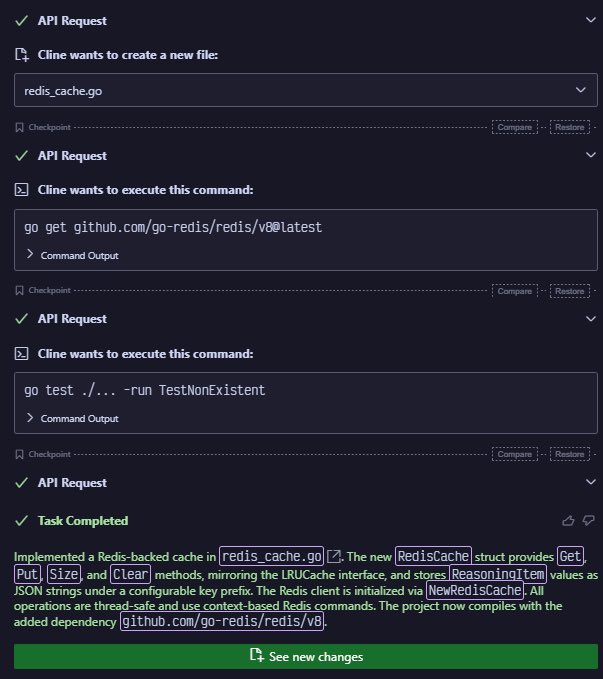
GPT-OSS 20B and Cline/Roo Code don’t work well together out of the box. Using llama.cpp and a simple grammar, GPT-OSS can be made usable. https://t.co/AQRGMHctYv
It makes me wonder if OpenAI recommends constrained decoding even in the absence of tools. If so, then I don’t see why this couldn’t be baked into inference servers.