1/ muse spark open is the most capable US open-weight model to date.
816B total params, 42B active. 1M-token context. natively multimodal. built for coding and agentic work like long-horizon tasks, hard software engineering, multi-step reasoning.
america! 🇺🇲
@elliscrosby@Frances48452643 you can use the muse wonder full from a Muse Code subscription plan (Power or Maximum usage tiers) https://t.co/KvwSPo5zWd
@brat002@alexandr_wang will look into the auth error that resulted failed to fetch model, there could be issues like geo restrictions for example. To help us debug, can you share more details via filing a support request from https://t.co/DoSRdQfVcD so we can check your account and see ways to unblock.
@AndrejDrats could you share more about how you were "banned", is it that the account could not be created, or not able to use after account creation. also feel free to report this via https://t.co/DoSRdQfVcD and share more details so we can debug and fix.
MUSE WONDER
this is the culmination of over a year of research and infrastructure work in msl
since we originally shipped muse spark in april, we have continued to scale our models across pre-training and RL, now reaching the frontier 🏆
see our model's improvements on the artificial analysis index:
what we've shipped:
muse ♥️
ton of connectors 🔧
muse invite codes 💌
muse phone call beta ☎️
muse for mac
muse in canada 🇨🇦
muse connector platform 🛠️
muse mac computer use 💻
muse for small business 💼
muse gadgets 🕹️
muse memes 🤡
no butthole 🍰
what should we ship next?
muse for mac is HERE!! your agent can now get stuff done right on your computer — files, messages, calendar, notes, all of it.
you're in control of what it can access, and it always asks before doing anything sensitive.
Add it to the dock - https://t.co/bFHgBZlkLj
4 launches this week from us: Muse Spark 1.3 and 1.3 Max, Muse Voice Transcribe, Muse Code subscriptions, and Muse Image. Try them all in https://t.co/SR4TgoWw84
1/ we just publicly released Muse Spark 1.3 max!
we see significantly stronger coding and agentic performance on muse spark 1.3 max, so would strongly recommend trying it out even if you've already tried muse spark 1.3 high or muse spark 1.3 xhigh.
1/ we just publicly released Muse Spark 1.3 max!
we see significantly stronger coding and agentic performance on muse spark 1.3 max, so would strongly recommend trying it out even if you've already tried muse spark 1.3 high or muse spark 1.3 xhigh.
Muse Image is now available on Meta Model API and priced for production volumes at $0.01/image.
It’s an agentic image model that reasons before it renders. Each call searches the web to refine the output through iterative passes and evaluates the prompt for precise elements like charts and QR codes.
Text-to-image, single-image and multi-image editing, and multi-reference composition all live in one model, so there's no multi-step pipeline to stitch together.
Start building → https://t.co/Q0TSXkIp03
And just like that, Muse Image is now live on the Meta Model API. $0.01/image - yes, that is indeed the price.
This is agentic image generation, again priced incredibly competitively.
We're going to keep cooking. By now, you know where to go - https://t.co/vf8UjrmDiq
Today is the start of a new era of natively multimodal AI innovation.
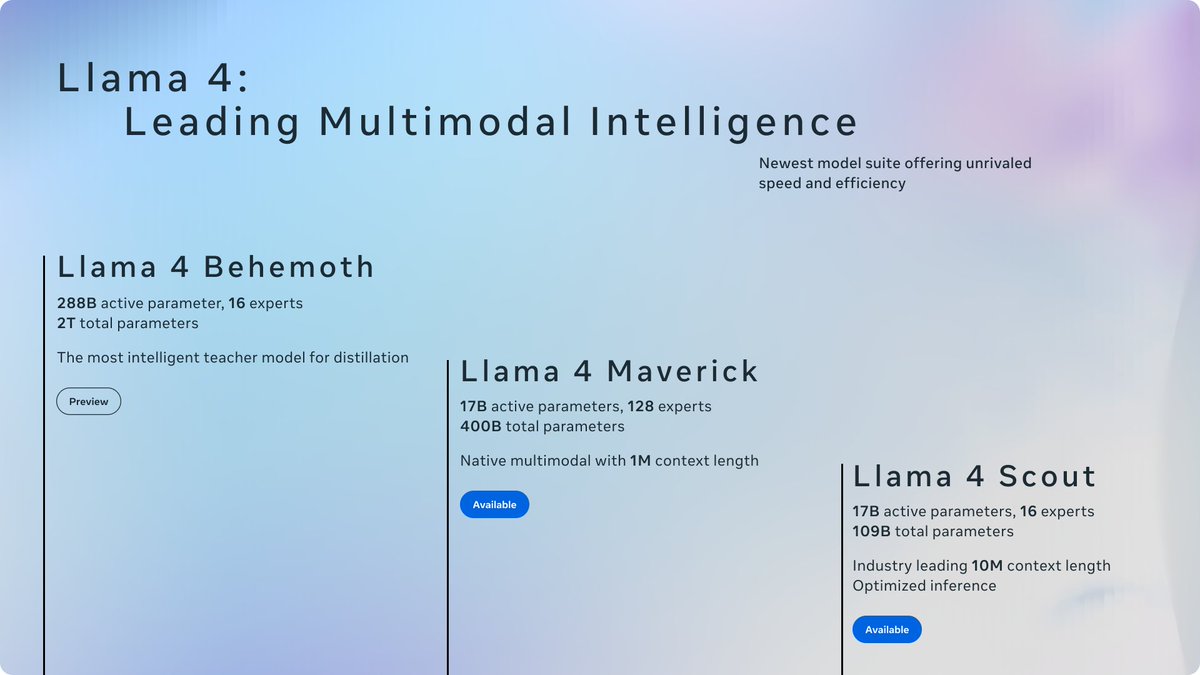
Today, we’re introducing the first Llama 4 models: Llama 4 Scout and Llama 4 Maverick — our most advanced models yet and the best in their class for multimodality.
Llama 4 Scout
• 17B-active-parameter model with 16 experts.
• Industry-leading context window of 10M tokens.
• Outperforms Gemma 3, Gemini 2.0 Flash-Lite and Mistral 3.1 across a broad range of widely accepted benchmarks.
Llama 4 Maverick
• 17B-active-parameter model with 128 experts.
• Best-in-class image grounding with the ability to align user prompts with relevant visual concepts and anchor model responses to regions in the image.
• Outperforms GPT-4o and Gemini 2.0 Flash across a broad range of widely accepted benchmarks.
• Achieves comparable results to DeepSeek v3 on reasoning and coding — at half the active parameters.
• Unparalleled performance-to-cost ratio with a chat version scoring ELO of 1417 on LMArena.
These models are our best yet thanks to distillation from Llama 4 Behemoth, our most powerful model yet. Llama 4 Behemoth is still in training and is currently seeing results that outperform GPT-4.5, Claude Sonnet 3.7, and Gemini 2.0 Pro on STEM-focused benchmarks. We’re excited to share more details about it even while it’s still in flight.
Read more about the first Llama 4 models, including training and benchmarks ➡️ https://t.co/9G3QgVdCkB
Download Llama 4 ➡️ https://t.co/eVomRvEr0w