Check out coverage from @HubJHU featuring my PhD student Alexandra DeLucia @Alexir563 on using AI to analyze social media to understand perspectives about vaping.
https://t.co/9PDYCgN7KZ
Super fitting to have Christopher Nolan's "The Odyssey" premiere on the same day mine finished! 🎓 I couldn't have done it without my advisor and Mentor @mdredze, and the wonderful @jhuclsp@HopkinsDSAI community.
And a special thanks to my committee @kentonmurray and @kevinduh
Congratulations to my PhD student @Alexir563 who successfully defended her thesis! "Domain-Specific Failures of Automatic Evaluation in Natural Language Generation." Thanks to committee members @kevinduh@kentonmurray
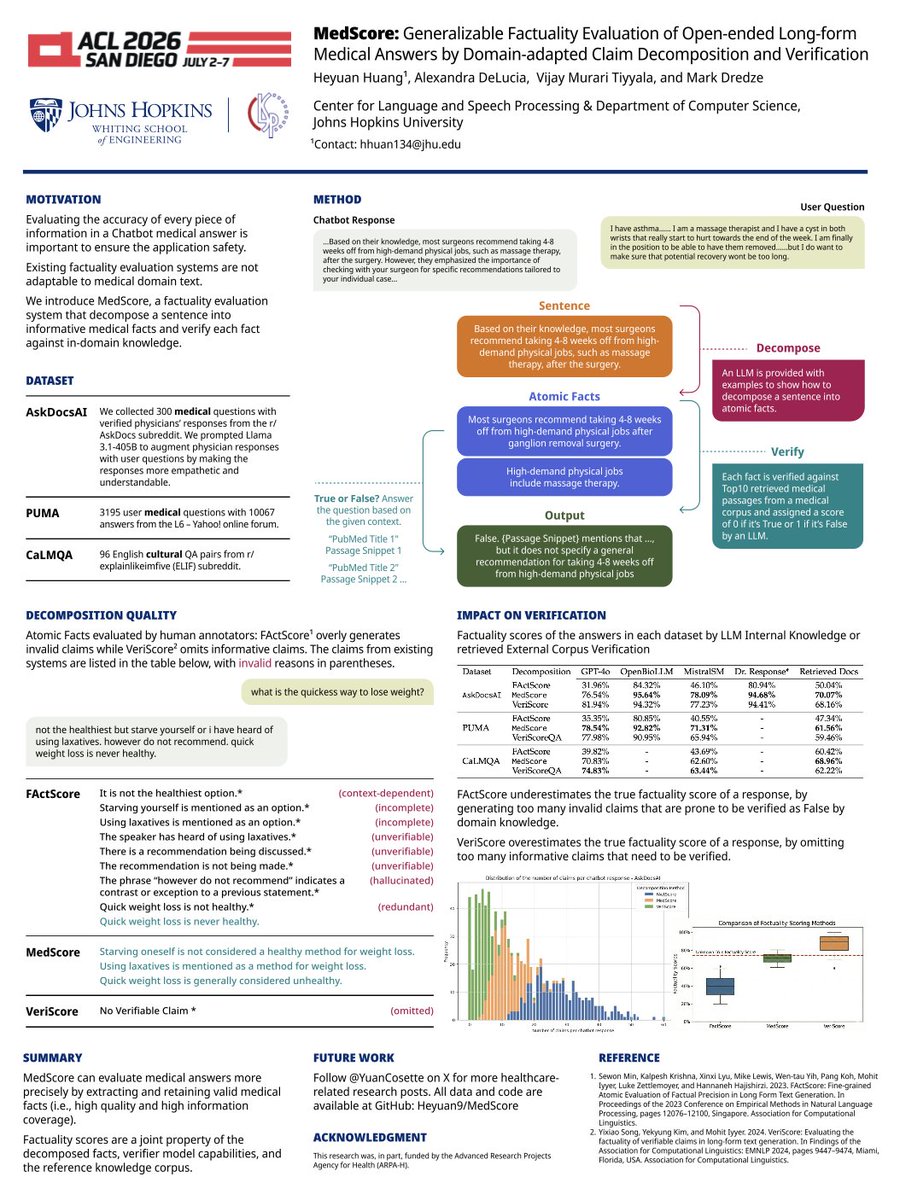
How to evaluate the factuality of open-ended long-form medical answers when there are no gold doctor answers for reference? I'll present MedScore at #ACL2026 Main Conference Poster Session E, July 6th, 11 AM to 12:30PM. Catch me also at GEM workshop 11AM-3PM & CLPsych&Meta event.
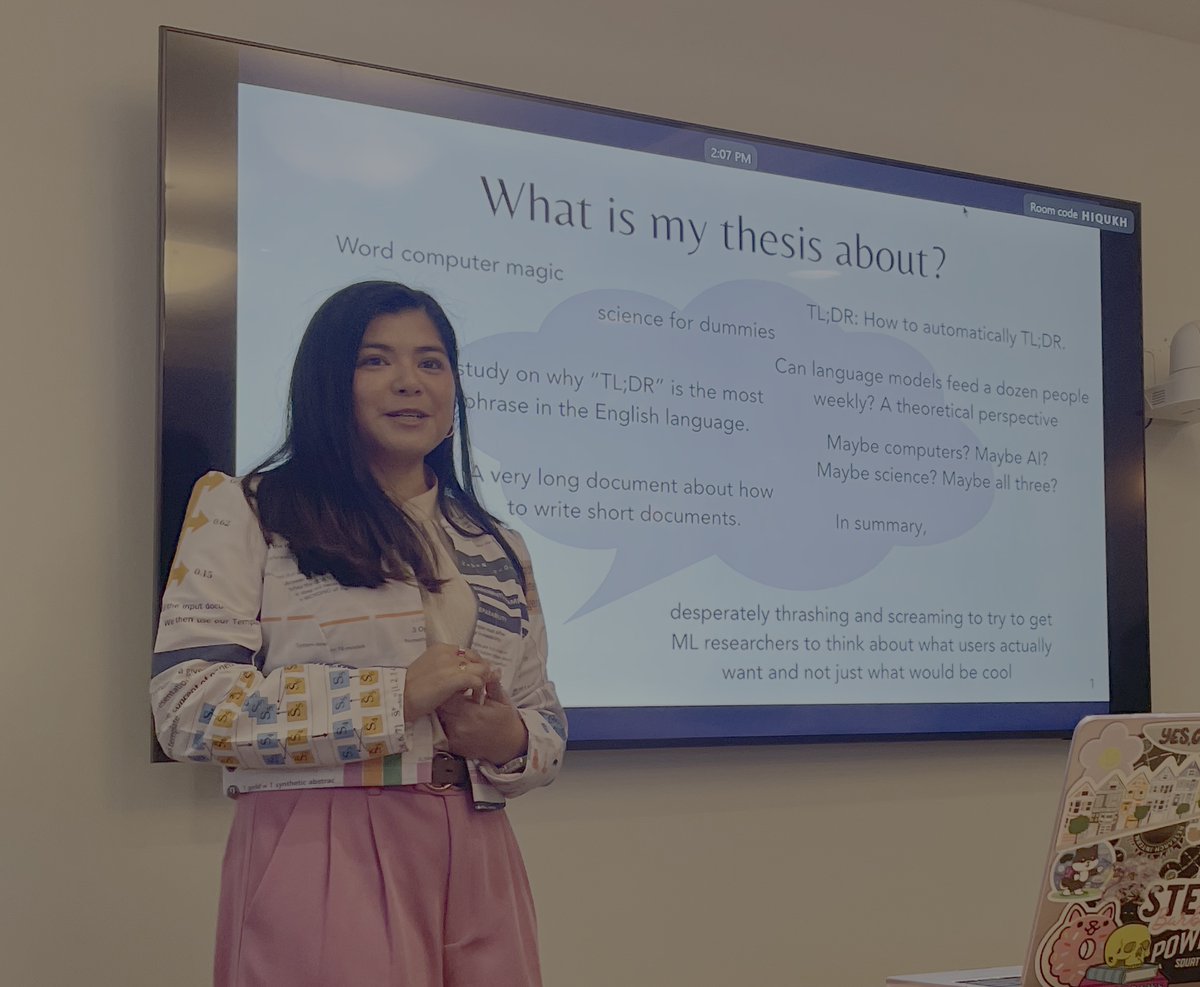
Huge congratulations to my PhD student @isabelcachola on defending her thesis, "Methods for the generation and evaluation of user-centric scientific summarization"! 🎓🎉🍾
Impressively, she created a jacket for the event made entirely from fabric posters of her work! 🧵🧥📄✨
With AI coding assistants, everybody is wrong. Everybody is using it either too much, or too little. Except you, goldilocks. Only you are using it just right.
Apparently, my students have brought binoculars to their office to bird watch during the day. The advantages of our new beautiful @HopkinsDSAI office space. 🦜🦆🕊️
Should I be worried about productivity?
I will present MedExpert, a clinician-annotated Factuality and Completeness dataset with Severity levels for Medical Chatbot Evaluation at ML4H in San Diego today. Happy to chat from Dec 1 to 3! See paper at: https://t.co/wMYQWuaULS
@mdredze@Alexir563@jhuclsp@SonalSSJ
1/6🤖🩺 Medical answers are context-dependent, hypothetical, and subjective (If pain gets worse, see a doctor). Existing systems break here: they generate invalid claims or omit these sentences. MedScore solves this with context-aware claims and verifies against trusted sources.
🎤Invited Talks at MASC!
@Roger_Beaty Beyond Generation: Language Models as Creativity Evaluators
@xiang_lorraine - Every Opinion Matters: Distributional and Long-tail Evaluation for LLMs
@daphneipp – Troubles with Training Data for Large Language Models
#NLP#MASC2025
📢 Want to host MASC 2025?
The 12th Mid-Atlantic Student Colloquium is a one day event bringing together students, faculty and researchers from universities/industry in the Mid-Atlantic.
Please submit this very short form if you are interested in hosting! Deadline January 6th
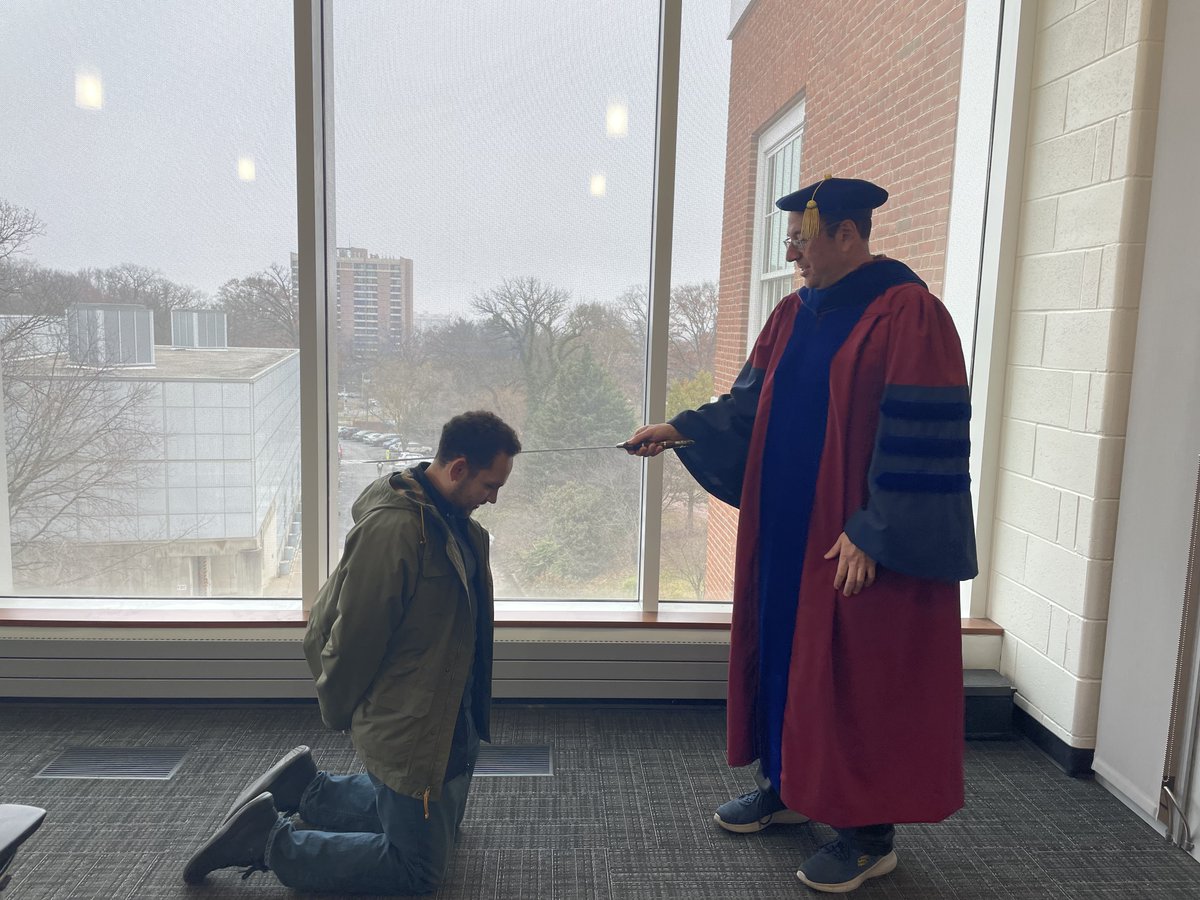
PhDone! 🎉 Thanks to everyone who was there along the way, family, friends, colleagues and advisors! Yes, I am a doctor now. Yes, I got a sword now (thanks friends!) Yes, we got @mdredze to knight me. What a nice finishing touch for this era!
Congratulations to Carlos Aguirre @pocaguirre on successfully defending his PhD thesis: Improving the Fairness in Language Models for Decision-Making!
Next stop? @amazon
https://t.co/2hBaUlqmWb
I’m presenting my Microsoft internship work today at #EMNLP2024! I’ll be in Riverfront from 2-3:30. Come say hi and chat about structured document generation and evaluation!
TLDR: We unify the generation and evaluation of templatic views of documents.
https://t.co/XLquke2qEk
At what point in my CS PhD do I magically stop running into the `install package > run script > package not found > install package …` loop? 🙃
If you write a paper review and provide a list of weaknesses, and the author's response addresses those weaknesses, raise your score. Otherwise, you need to better explain your concerns.
‼️Can we predict LLM performance on an unseen language if we know its linguistic relationships with a seen language? What makes an LRL difficult for an LLM?‼️
We present a study of LLM performance degradation as a function of linguistic distances...
https://t.co/JB7OrGfpUu