i avoid emotional topics in my posts but decided to just say it how it is in this tiering of classic PDFs. i think real PDF lovers will agree but some of you may get your feelings hurt
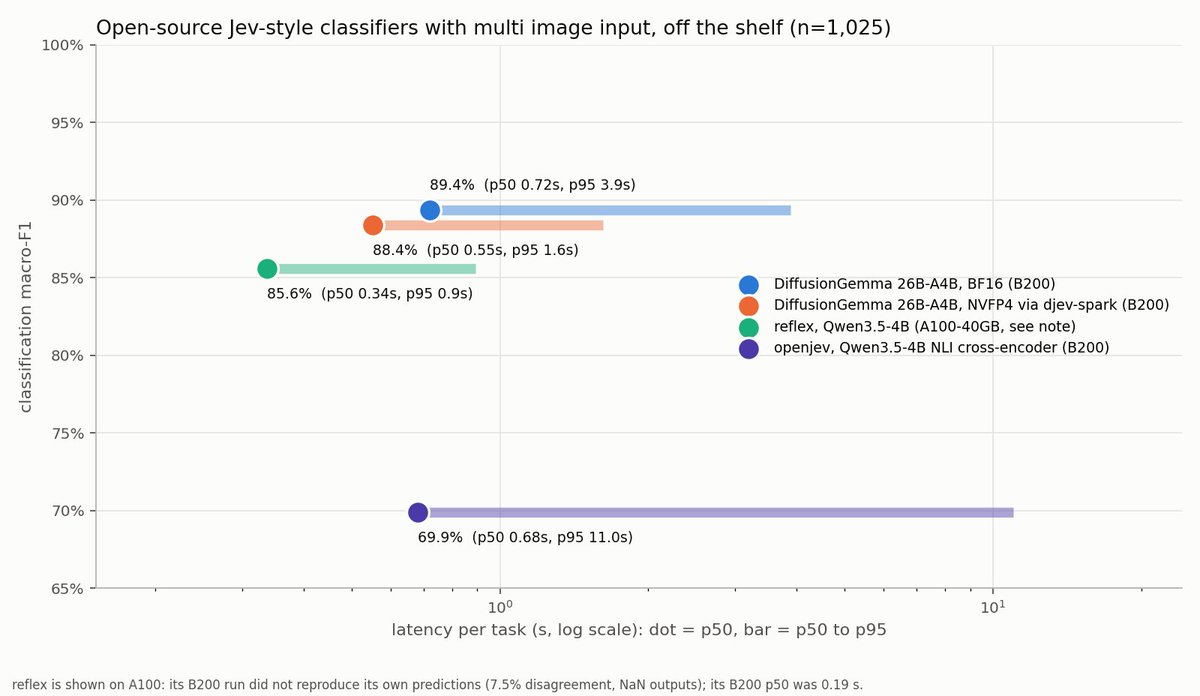
Jev doesn't support image input yet, so I tested out some open-source Jev-like alternatives.
Seems like DiffusionGemma and reflex are on the pareto for the open source Vision-Jevs!
https://t.co/jy18qLK1NW (ty @mmastrac)
https://t.co/fKW3Pd6Mjf (ty @kshetrajna )
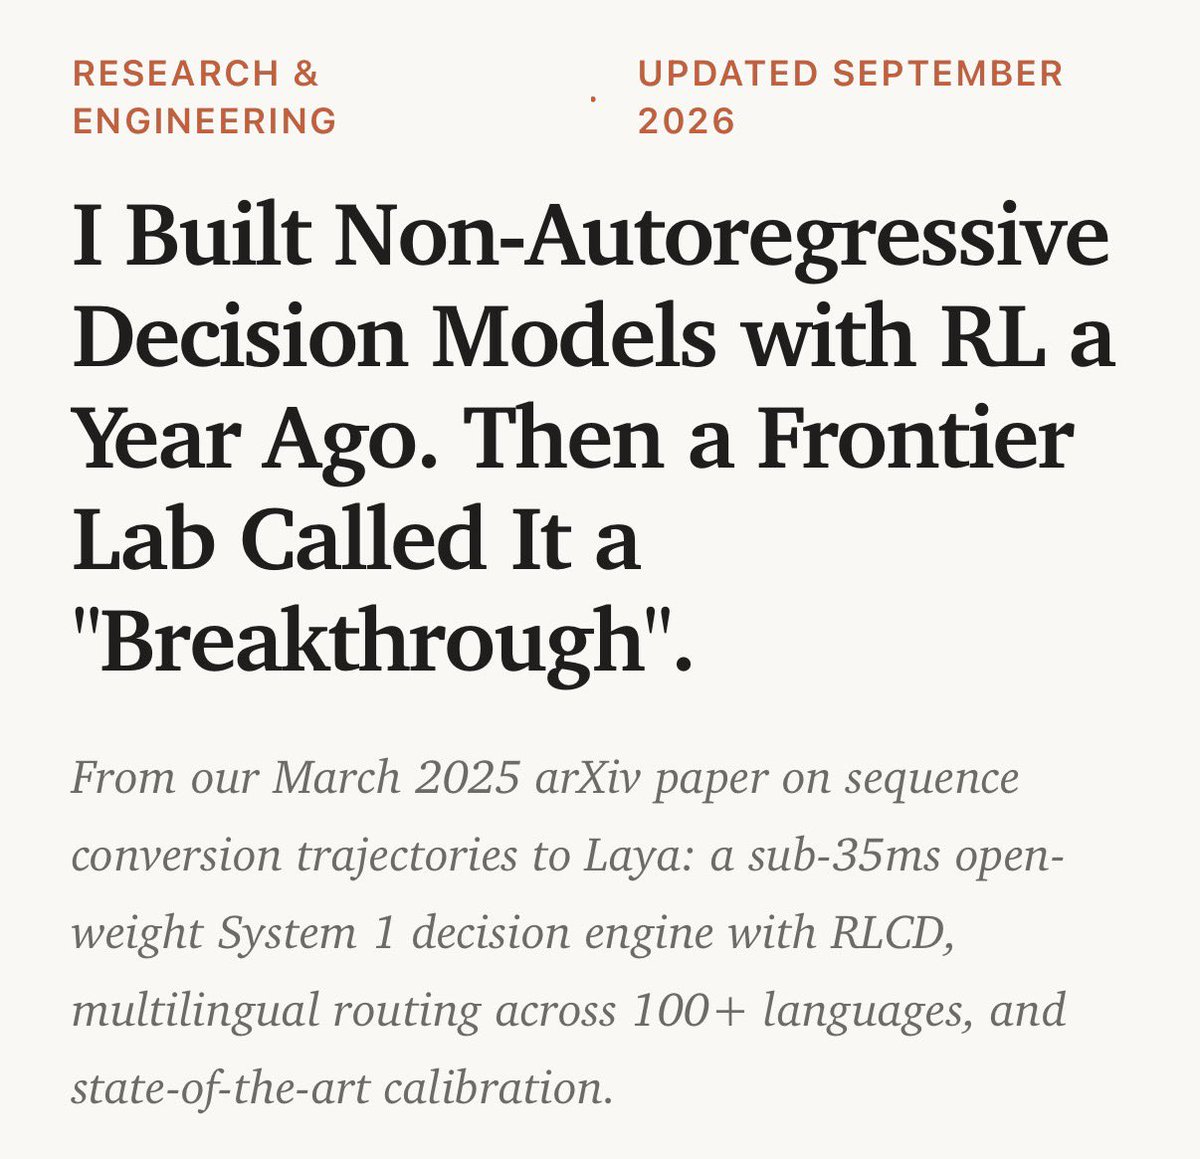
poor guy claim to have built Jev a year ago but no one cared, and now Jev stole all the thunder
many people are saying “you gotta tell your story” or “marketing is important”, and they just completely missed what actually made the difference here
i just looked into this laya model https://t.co/8QWCGZqS43 and:
- it only supports 512-1k context… a lot of use cases won’t fit at all
- evaluating the model directly shows its accuracy is as good as a coin flip. in order to get good results, you need to first fine tune it
i’m sorry, but that’s not Jev
there’s a massive gap between an interesting research and a useful product
you can “tell your story” all you like, but you can’t blame Jev for stealing your thunder when Jev did all the work to make a well-packaged solution anyone can just grab and go
Jev is not completely new from an academic sense, just like how ChatGPT was not the first LLM
don’t underestimate the effort and value in putting together something that’s actually good enough for adoption - it makes all the difference
Jev doesn't support image input yet, so I tested out some open-source Jev-like alternatives.
Seems like DiffusionGemma and reflex are on the pareto for the open source Vision-Jevs!
https://t.co/jy18qLK1NW (ty @mmastrac)
https://t.co/fKW3Pd6Mjf (ty @kshetrajna )
"DiffusionGemma as Jev" showcases the power of non-autoregressive architectures.
While Jev demonstrates the value of rapid decision models, running DiffusionGemma in this paradigm leverages canvas diffusion to evaluate structured choices in a single parallel pass:
⚡ ️Massive Parallelism: Denoises across an open canvas in a single step instead of sequential autoregressive token generation (~0.2s on a DGX spark).
🧠 Full Bidirectional Attention: Allows every option to attend to the full context concurrently, yielding well-calibrated decision distributions.
👁️ Multimodal Grounding: Inherits Gemma 4's spatial vision capabilities for complex visual and text decisions.
Read more about this approach here:
https://t.co/hCEg276mzA
https://t.co/vRLhy6KECT
https://t.co/EQEumaQLYd