Cohere Labs x ICLR 2026: Making, Not Taking, the Best of N
Introduing Fusion-of-N (FusioN) where we replace “pick the best sample” with “generate a better one by combining samples.”🚀
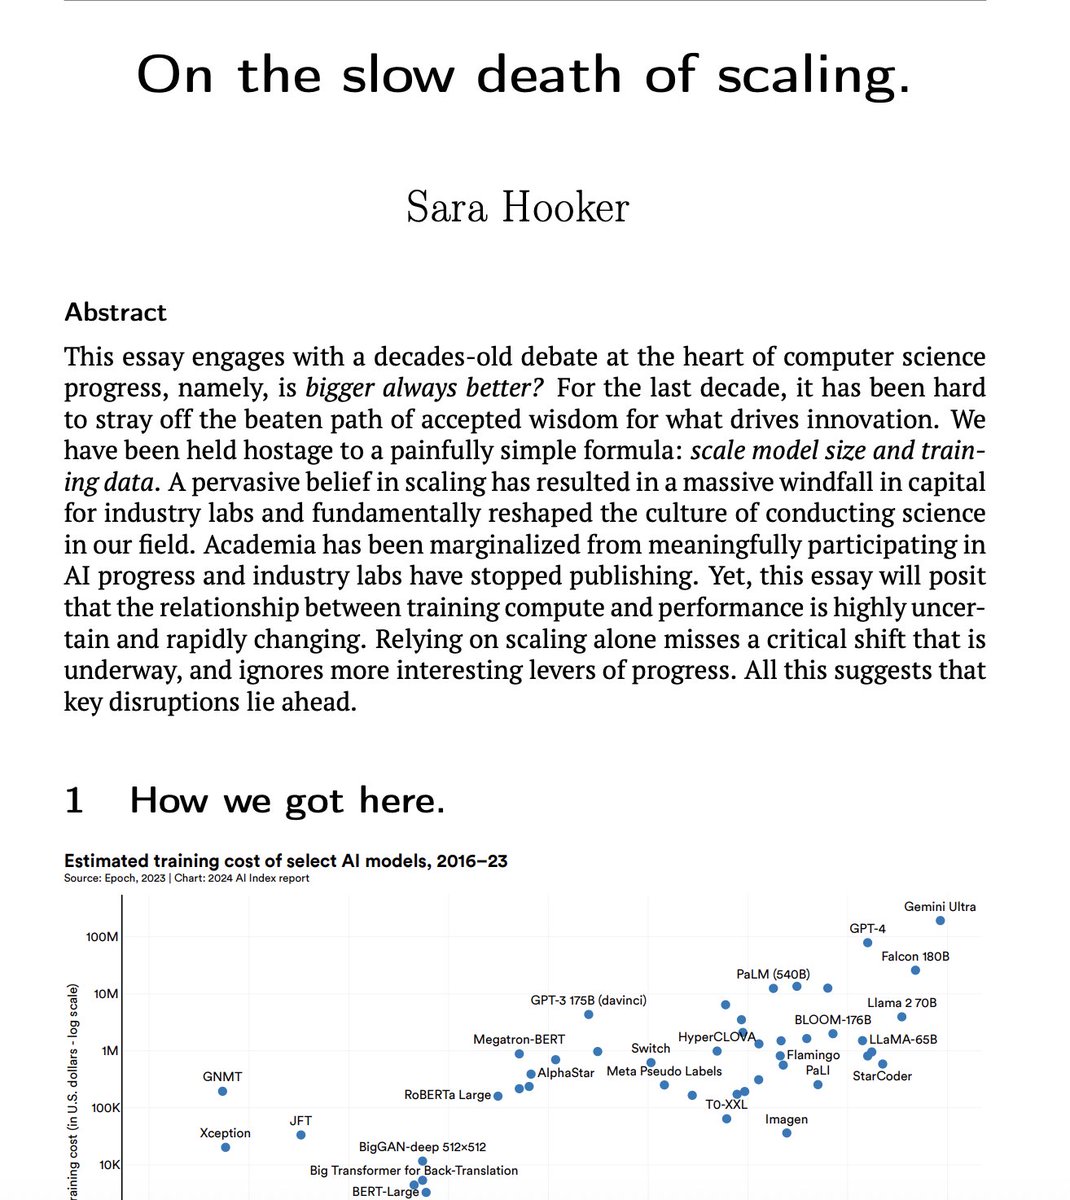
For the last decade, it has been hard to stray off the beaten path of accepted wisdom that scaling training parameters drives innovation.
However, the relationship between training compute + performance is uncertain + rapidly changing.
كيف وصل كولومبيون للقتال مع الدعم السريع؟ 🇸🇩
ظهر هذا الأسبوع تحقيق استقصائي من صحيفة «القارديان» كشف عن شبكة من الشركات المسجّلة في بريطانيا، يديرها أشخاص صدرت بحقّهم عقوبات أمريكية، جندوا مئات الجنود الكولومبيين السابقين للقتال مع قوات الدعم السريع في السودان.
معظم المجنّدين متقاعدين من خلفيات عسكرية في كولمبيا، وقد وُعدوا برواتب تتراوح بين 2500 و4000 دولار في الشهر، وهي أعلى بستة أضعاف من معاشاتهم التقاعدية في بلدهم كولومبيا. وأشار التقرير إلى ارتباط طرف خارجي بتمويل هذه القوات عبر الشركات التي تولّت عملية تجنيدهم.
حسب التقرير كان بعض الجنود الكولومبيين متخصصين في تشغيل المسيّرات، إضافة إلى دورهم في تدريب مقاتلين من قوات الدعم السريع، وكان بعض المتدرّبين أطفالًا. وذكر التقرير اتهام المرتزقة الكولمبيين بارتكاب مجازر وجرائم حرب، إضافة إلى المشاركة في حصار الفاشر ومجاعتها.
LLMs already generate far more knowledge than we use and most of it is thrown away.
What if we could use it all? To scale smarter, generate richer data, and train models that actually learn from diversity?
Happy to share our work: Making, not taking, the Best of N ✨
Best-of-N (BoN) is the go-to for inference scaling and a cornerstone of building synth data for SOTA models.
But can we do better than the Best?
Introducing Fusion-of-N: a simple and powerful way to go beyond BoN 🧵
What if the way we verify synthetic code is limiting model performance?
In our latest work we uncover the Verification Ceiling Problem: strict “all tests must pass” rules throw away useful data, while weak tests let errors through.
Our work on scaling test time compute will appear on #EMNLP2025 Main Conference 🎉
🍋 Our LLMonade recipe combines strategic sampling with novel selection to squeeze out the most performance of LLMs.
Huge thanks to: Julia Kreutzer, @mrdanieldsouza, @YeS855811 and @sarahookr
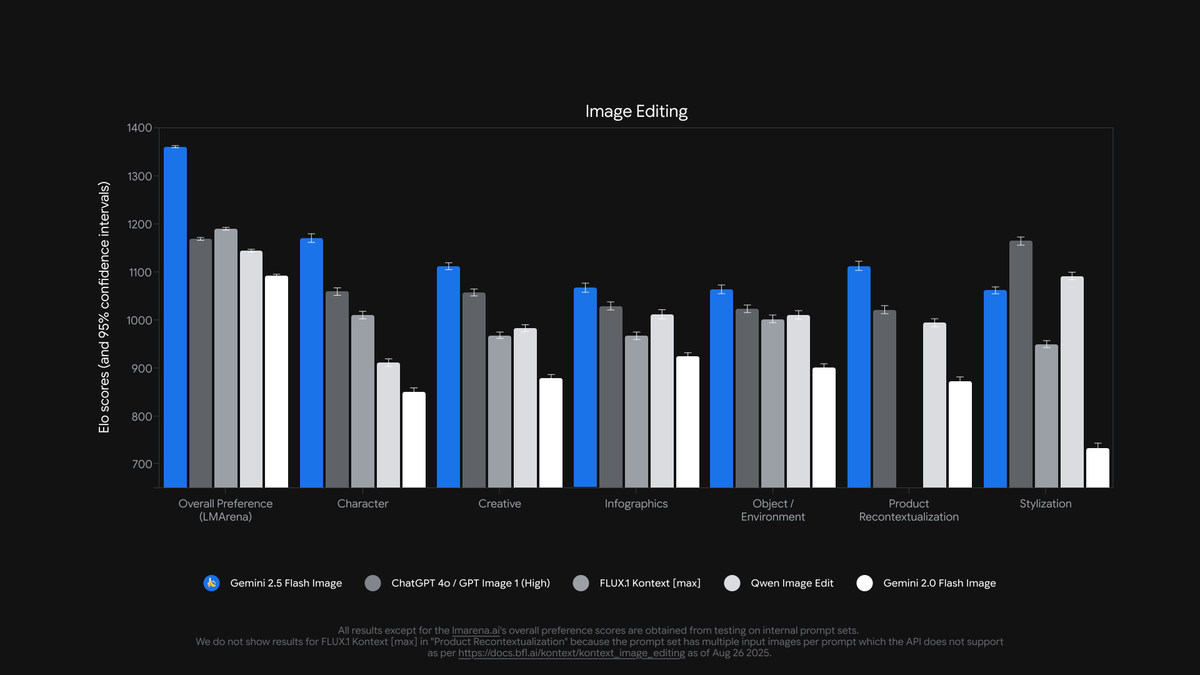
Introducing Gemini 2.5 Flash Image (aka nano-banana), our SOTA image generation and editing model 🍌
As you might have already seen, this model excels at character consistency, creative edits, and has Gemini's world knowledge!
Resilience is a key attribute among successful researchers, which is why we place such high value on it in the application process for the Scholars Program.
@dianaabagyan exemplifies this.
Looking forward to connecting with new & familiar faces through this year's application.
Applications are now open for the next cohort of the Cohere Labs Scholars Program! 🌟
This is your chance to collaborate with some of the brightest minds in AI & chart new courses in ML research. Let's change the spaces breakthroughs happen.
Apply by Aug 29.
Applications to the Scholars Program are open now! It is one of the most unique and exciting research programs out there.
Come join us at the info session and make sure not to miss the deadline.
أنصح بشدة الناس تقدم في البرنامج، وإذا في أي أسئلة أنا ممكن أساعد.
Can we improve the performance of LLMs during inference without the need for extensive sampling OR special reward models? 🤔
Our latest work introduces a new inference time scaling recipe that is sample-efficient, multilingual, and suitable for multi-task requirements. 🍋
💪🏼Huge thanks to my incredible mentors: Julia Kreutzer @mrdanieldsouza, @YeS855811, @sarahookr for guiding me and supporting this work ✨
Find our arXiv release here! 📜: https://t.co/6BTErQ4qIN
🚀 Want better LLM performance without extra training or special reward models?
Happy to share my work with @Cohere_labs : "When Life Gives You Samples: Benefits of Scaling Inference Compute for Multilingual LLMs"
👀How we squeeze more from less at inference 🍋, details in 🧵