LangGraph subgraphs aren’t just useful for reusability. They also enable enforcement of state boundaries.
By defining a subgraph state along with input and output schemas, we can control what gets passed between the subgraph and the parent along with what state keys are kept private within the subgraph.
I keep seeing the same gaps in AI engineering project repos. Having them really makes candidates stand out:
1. A README that explains the problem and how the project solves it
2. Deterministic code where an LLM isn't needed with the reasoning written down
3. Structured outputs on model responses
4. Fallbacks for when a step fails or the model gets it wrong
5. An eval suite with a dataset that shows thought about what's being tested and why
6. Cost and latency considered and documented
What would you add?
When I review an AI engineer's repo, I'm often more interested where they didn't use an LLM.
I want the docs to tell me what needed a model and why and which steps are deterministic and why.
That tells me each step was considered and the most efficient option was picked. Systems built that way are cheaper, faster and much more likely to hold up in production.
What are some unnecessary LLM calls you've seen?
Just reread The Wisdom of Crowds. The idea of the best decisions coming from aggregated opinions of a diverse group including experts and non-experts sounds a lot like weak learners in a Random Forest.
#datascience#machinelearning#randomforest
Have you got a problem with unwanted white space in your pandas dataframes? The code snippet on https://t.co/trGe6GUlKH shows a simple way to remove leading and trailing white space. #DataScience#python#nlp
https://t.co/3DM44tfPB8
Datacated Academy has excellent courses focussed on visualisation. Aleksa Gordic posts are some of the best around and includes a post on his path to becoming a research engineer at Deep Mind.
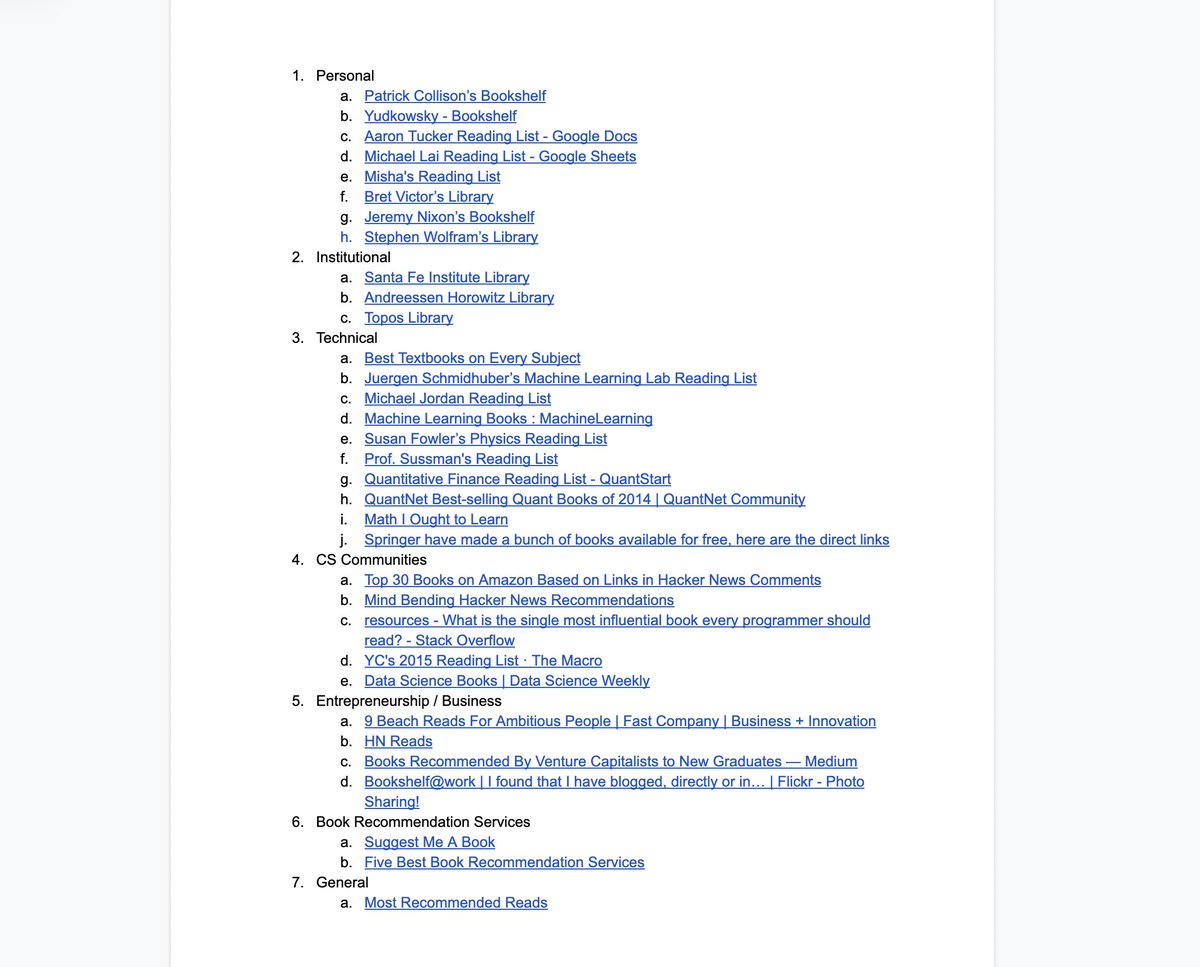
Our current data science resource recommendations:
1. https://t.co/v8pgypo7WA for creating creating, storing and sharing data science code snippets
2. https://t.co/euAqjGO6oH from @datacated_
3. https://t.co/bhH1kRC0VH from @gordic_aleksa#datascience#100DaysOfCode
A code snippet for using the cross_validate function to score your model across different folds of your data. #DataScience#Python#MachineLearning
https://t.co/3FhSMNLH5o