#Qwen4Max redefines AI economics: 2.4T params, 1M context, and native vision at 80% lower cost. But the real story?
#AgenticAI coding matches frontier models, yet fails on terminal replication
https://t.co/cqi8X5au8l
"bigger is better" vs. "smart sparsity wins"
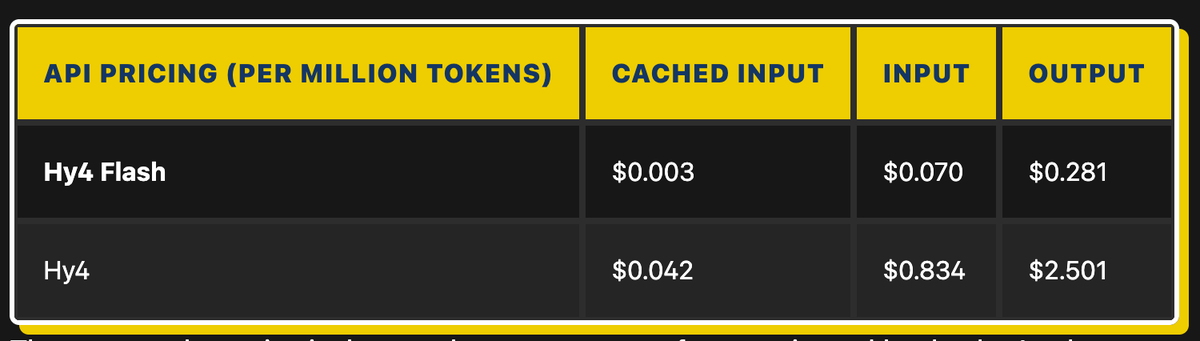
#Hy4Flash redefines #AIEfficiency with 12B active params from 224B total, cutting input cost to $0.07/M tokens.
https://t.co/PXrc7vEGod
#DIYAIRigs are the new hot rods: 8x GPU water-cooled behemoths pushing thermodynamics, PCIe lane math, and personal sanity. One lawyer's 8-V100 build hits 215 tokens/s, entirely offline
https://t.co/lgWkHAJj6M
The #AIscaling crisis hits hard: 770B-parameter models need 462GB RAM at Q4. Your 128GB workstation? Obsolete. Is #MixtureOfExperts the escape hatch or just delayed collapse?
https://t.co/3sLaj2Ri4Q
#DatabaseIndexing fundamentals still matter: a missing composite #BTree index on 16M rows turns a query from 1ms to 5s. Your ORM won't save you from physics
https://t.co/q5GAUAXynM
#DistributedAI gets a controversial twist: #Microsoft's patent proposes using idle consumer #GPUs for micro-training tasks, rewarding users with opaque "credits". But will #ComputeCredits cover your power bill, and can you trust the opt-in?
https://t.co/8tBciLRATl
#MiniMax#H3Image drops 16MP in 10s with a single 33B DiT checkpoint, no upscalers, no CFG, 6-step distillation.
But the #OpenWeights license blocks US/EU/UK/KR.
Geopolitical gatekeeping?
https://t.co/bSHpGiqIgp
The software moats era is over: a single dev with #ClaudeOpus5.5 built 7 Adobe clones in a week.
At $13.50 per reverse-engineering attempt, #CompetitiveAdvantage now hinges on data, distribution, and liability, not code
https://t.co/Z8XkKrGlY0
#Qwen's 'redditor neuron' (L11 N8147) flips between confident lies and blind trust. A single activation shift reveals #ModelBehaviorControl with poetic precision. The canary is writing haiku
https://t.co/tGMwmCyQlz
Per-tenant #SQLite isolation is secure but unmaintainable. The shift to #PostgresRLS isn't about scalability, it's about survivability.
But #RLS alone won't save you from #ViewLeakVectors or cross-tenant index scans.
https://t.co/pxYql2De1G
Running a 284B-parameter #LLM on 64GB RAM with no GPU?
Meet #LlamaModchip: a CPU-first architecture using extreme #Quantization (2-4 bit) to run DeepSeek 284B at 5-7 tokens/sec. This isn't slow, it's strategic. #EdgeAI
https://t.co/D7nCZjCZSH
#PostHog just ditched #DuckLake after 5 months and 2PB of data. The #CatalogTax was killing writes, 99% of stats belonged to deleted tables. When 'portable' becomes a bottleneck, #LakehouseArchitecture meets reality.
https://t.co/GaL0HSRujN
#SoftDelete trap is real: that innocent `is_deleted` flag inflates indexes by 4x, breaks unique constraints, and turns queries into landmines.
At 180M rows, your B-tree becomes a ghost town. #DatabasePerformance
https://t.co/GddyqbxmtV
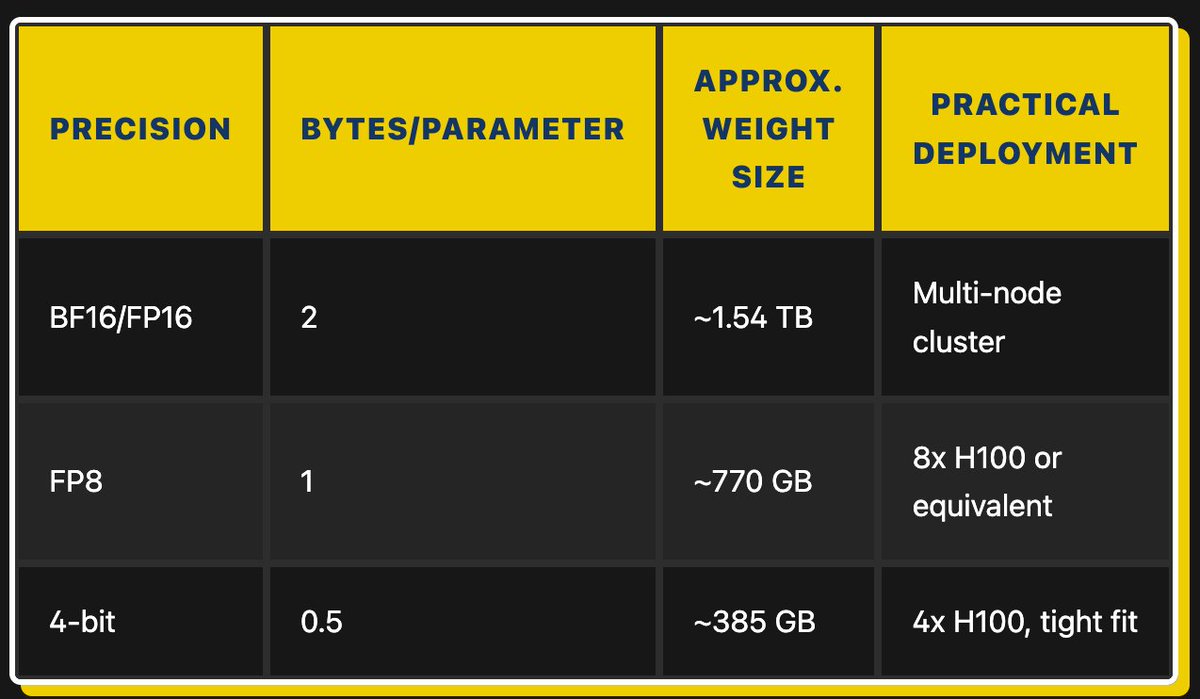
#Tencent's #Hy4 drops with 770B params, Apache 2.0 license, and native #ComputerUse capabilities. Vision + million-token context?
It's a strategic play for #TencentCloud dominance. But at what cost to security research?
https://t.co/8xYqHVLWRE
#Moonshot just dropped #KimiK31Pro, a 2.8T-parameter #MoE model on Hugging Face with 1.56TB of MXFP4 weights.
Your GPU is crying. But it's not the full frontier model. The released checkpoint scores 81% vs 90.5% on xdev-bench-hard
https://t.co/VKhMqVtcF2
#SelfHostedAI wins: #Revolut slashes coding costs by 90% with #GLM5.3 on B200s. Ditched Claude, saved millions.
The #OpenWeights revolution just hit fintech at scale.
https://t.co/JSfLml7csD
#FabricCertification vouchers reveal Microsoft's ecosystem play: 100% coverage for DP-700/DP-600 but only 50% for legacy Azure certs.
Is #FreeCertification a talent boost or platform adoption desperation?
https://t.co/iQctdZYVuE
#BinanceHack in 20 minutes: $6.3B drained without stealing keys. The attacker exploited a trusted service, proving #HighThroughputSystems fail when trust replaces verification. Architectural blind spots matter more than code flaws. #SecureByDesign
https://t.co/1Ivd0qQQqO
NVIDIA just axed the RTX 5080 16GB, same die, same cores, same bus, but 24GB VRAM is coming.
This isn't a refresh. It's a #VRAMOverCompute manifesto. The #AIGPUEra begins where gaming ends
https://t.co/mBcacIZfqq