

Top Tweets for #Quantization

763.2B DeepSeek V4.1 Flash GGUF now runs on 12GB VRAM; if you already downloaded, the update is just 80 KB. ISTA-DASLab/DeepSeek-V4.1-Flash-1017-GSQ-RCO-GGUF #AI #LocalLLM #OpenSource #GGUF #Quantization


A model doesn't always need FP32 weights.
You can represent weights using fewer bits:
FP32 → FP16 → INT8 → INT4
Fewer bits can mean:
↓ memory
↑ throughput
↓ inference cost
The challenge?
Keep the accuracy.
Read: https://t.co/HKcbVm7DGP
#LLM #AI #Quantization

Qdrant 1.20 enhances full-text search & adds TurboQuant, boosting performance & efficiency for hybrid search and vector database scaling.
#qdrant #vectordatabase #fulltextsearch #quantization
https://t.co/DAEtiEuK0F

@xuhb20 Congrats on STEPQuant, Haobo! Tackling quantization for Delta-rule recurrent states is such a useful direction, and sharing both the paper and code makes it easy for others to build on. Great work! #LLM #Quantization


🚀 Introducing STEPQuant for recurrent state quantization in linear attention!
6-bit states → near-FP32 accuracy + >5× compression.
📄 Paper: https://t.co/26ypnLX20f
💻 Code: https://t.co/gNThpQm8Im
#LLM #Quantization

Ethical Hacking und Penetration Testing Tipps: Aufbau eines KI-Cybersicherheitslabors - Teil 11: LLM Benchmark's
#Ollama #HuggingFace #LocalLLM #KI #LLM #RAG #Quantization #Xubuntu #coolstuff
👇👇👇👇
https://t.co/v5XjUc9Com


🧵 The next era: build your own local inference engine.
Why now?
1/ Open models are good enough
2/ Quantization makes them fit on any hardware
3/ Cost and cost are pushing teams off the cloud
#LocalAI #LLM #Quantization #GPU #OpenSourceAI #AIEngineering #BuildInPublic

RaBitQ is now in Vectorium!
Up to 30x compression, no training, 1/2/4/8 bits per component, 1.4-2.2x faster than the original implementation.
Against PQ, on neural embeddings it wins on every axis, and the gap grows with dimensionality.
#VectorSearch #Quantization #NeuralIR


Launch: vllm-position-parity🚀
This position-resolved measurement tool for vLLM has been used in:
5-arm determinism isolation (#54521) – confirmed 4 co-occurring defects & full zeroing with combined fixes
https://t.co/mIUsb0MuOZ
#vLLM #quantization #determinism

Our pick of the week by
@dhairya_su47605
: "Task-Circuit Quantization: Leveraging Knowledge Localization and Interpretability for Compression" by @hanqi_xiao, @yilin_sung, @EliasEskin and @mohitban47
#Quantization #Interpretibility

#PickoftheWeek @fbk_mt
Super cool paper on leavaraging Interpretability for Compression!
https://t.co/ixQtcUxmUm

Full Zenodo blueprint: https://t.co/j42t9dG4kT
GitHub Spec: https://t.co/3lBeWB7EOr
Tagging @karpathy @Tim_Dettmers @ggerganov for thoughts on the entropy hysteresis bounds. #vLLM #Quantization

'Approximations and Learning for Continuous State and Action MDPs under Average Cost Criteria', by Ali D. Kara, Serdar Yüksel.
https://t.co/fRm0w2NHxT
#quantization #quantized #discretization

다음은 저도 @0xSero 의 아주 훌륭한 작업인 https://t.co/J5ZAGDoGc4 의 개념을 도입해서 glm-5.2의 파라메터 자체를 더 줄여보려고 합니다.
#Quantization #glm-5.2 #mlx

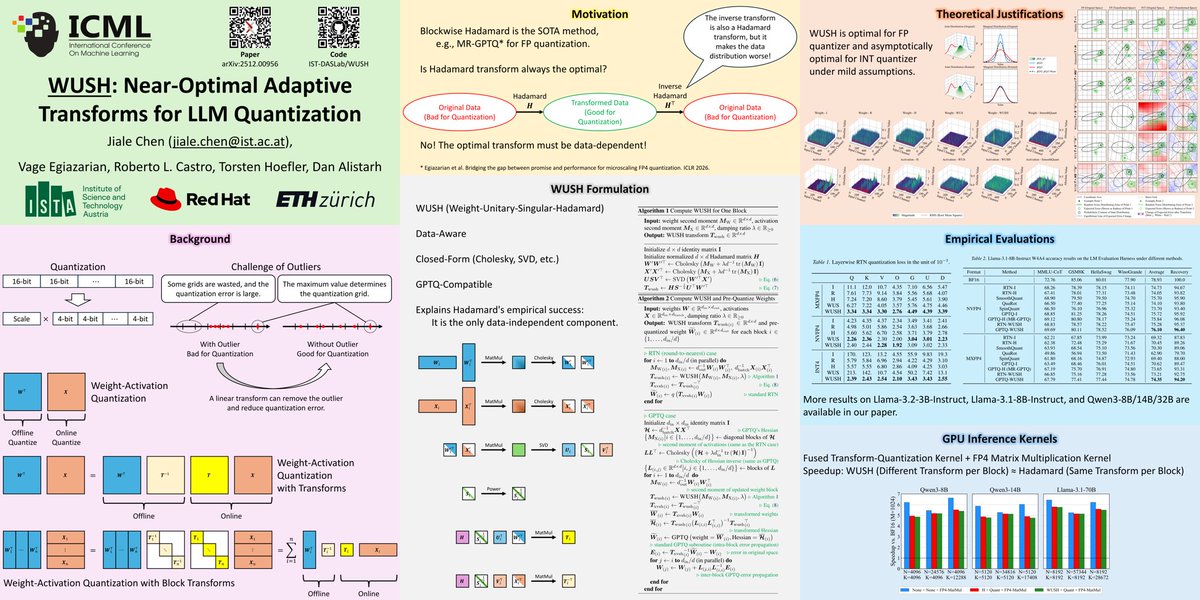
🚀 Our #ICML2026 paper: WUSH: Near-Optimal Adaptive Transforms for LLM Quantization
WUSH is a closed-form, data-aware, near-optimal blockwise transform that reduces LLM quantization error.
🔗 https://t.co/xTtxc9BMQG
🔗 https://t.co/SGeyLWSVD1
#ML #LLM #Quantization

I always thought quantizing LLMs was something that needed crazy hardware or training.
Finally gave it a shot today and it was way simpler than I expected.
Thanks to llama.cpp for making the whole process ridiculously easy and @Alibaba_Qwen for good SMLs.
#LLM #Quantization #GGUF

FP8 KV cache is underrated. Weights load once, but KV grows with every token and batch. Halving KV from FP16 to FP8 roughly doubles the context you hold at fixed VRAM, and attention is memory-bound so the accuracy hit stays small. #quantization #KVcache #FP8 #inference #LLM

Here's my quant of qwen3.6 35b
this is my tune to get around my slow ass ram
https://t.co/i7jR4KSWvr
#Qwen3 #Quantization #HuggingFace #AI #OpenSource


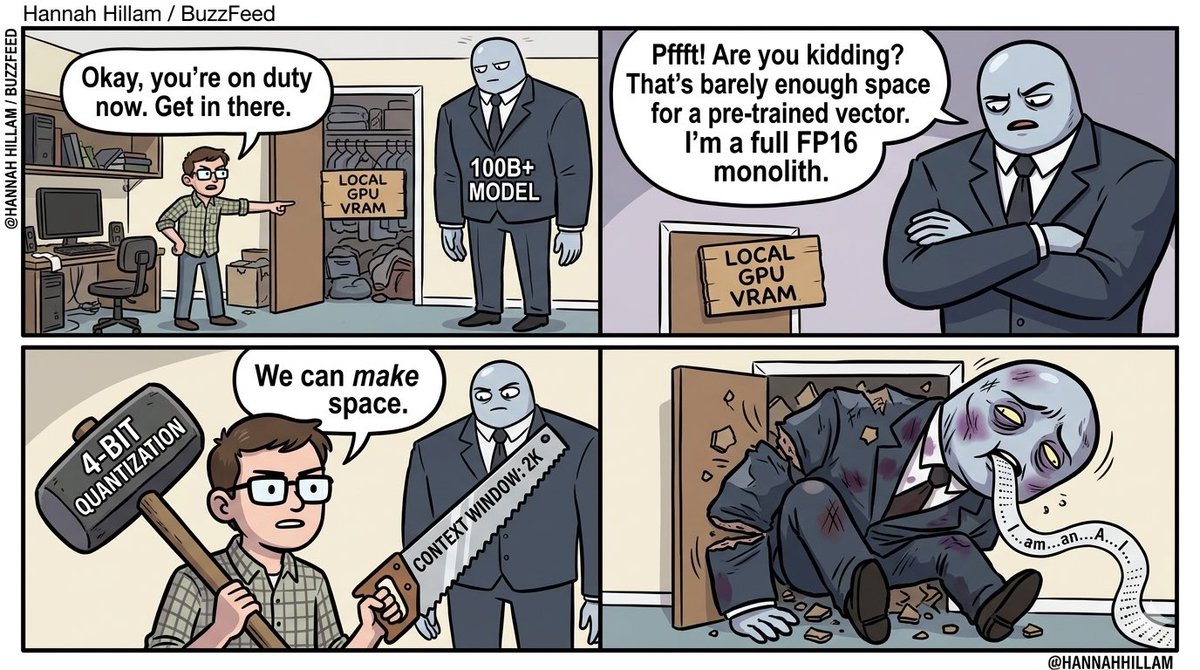
When you try to force a massive 100B parameter model into your tiny local GPU using 4-bit quantization and context window chopping... 🔨💥 The brutal reality of local LLM deployment! 😂
#工头熊猫的漫画时间 #ForemanPandasComicTime #LLM #LocalAI #Quantization #GPU #TechHumor #MachineLearning
Our pick of the week by @dhairya_su47605
: "Scaling Laws for Precision" by @tanishqkumar07, Zachary Ankner, @bfspectorShiekh, @blake__bordelon, @Muennighoff, @mansiege, @CPehlevan, Christopher R´e, @AdtRaghunathan
📰https://t.co/PZCB3fyOCw
#Quantization #LLM #ScalingLaw
Pick of the week @fbk_mt
Super interesting paper on the limitations of quantization, demonstrating how post-training quantization scales poorly in data.
https://t.co/tBuGTL0Myi
Last Seen Hashtags on Sotwe
vei34
Seen from United States
minichatt
Seen from Netherlands
سكس
momson()*********************
Seen from Brazil
tricolorporlos6
Seen from United States
ipcam filter:videos since:2025-10-28
Seen from United States
تانجو_حصري
Seen from Qatar
นัดเย็ดบางเขน
Seen from Thailand
travesti
Seen from Turkey
mgai()()()()video()()()
Seen from Netherlands
Most Popular Users

Elon Musk 
@elonmusk
241.5M followers

Barack Obama
@barackobama
118.8M followers

Cristiano Ronaldo
@cristiano
114.5M followers

Donald J. Trump
@realdonaldtrump
111.9M followers

Narendra Modi
@narendramodi
107.1M followers

Rihanna
@rihanna
98.7M followers

NASA
@nasa
92.3M followers

Justin Bieber
@justinbieber
91.8M followers

KATY PERRY
@katyperry
90M followers

Taylor Swift
@taylorswift13
84M followers

Lady Gaga
@ladygaga
75.5M followers

Virat Kohli
@imvkohli
73.5M followers

Kim Kardashian
@kimkardashian
70.9M followers

YouTube
@youtube
68.8M followers

Neymar Jr
@neymarjr
66.5M followers

Bill Gates
@billgates
65.3M followers

Selena Gomez
@selenagomez
63.1M followers

The Ellen Show
@theellenshow
62.2M followers

CNN
@cnn
61.7M followers

X
@x
60.7M followers