@yume_arasaki@Blackfrost_AI someone had stock flash next on one spark at ~66 earlier today. 60.7 on a 180b finetune of it with those coop kernels is a pretty small tax
@LuminaBench some of that infinite is it quitting early. a threat hunting bench today had it using ~10% of its turn budget, $0.01 a hunt, 9.3% vs opus 5 at 45.1
@MiaAI_lab same glm 5.3 flash squeezed to 2.05bpw on two 3090s with ddr4 spill was doing ~9 earlier. fitting the whole 4bit in unified memory is most of that gap
@niklaslenz_ai@ashxhart code barely moving 184.8 to 186.5 while prose picked up ~12 looks like code was already at the ceiling. rapidmlx 0.15.7 took the same nemotron lightning from 151 to ~245 on mac
@0xSero a 4gb card holding 128k of kv and still doing 21 decode is the part i'd have bet against. single spark was doing ~228 coding on a 35b a3b earlier
@MinLiBuilds 56% more prefill from dropping to iq3 is more than i'd have guessed. 2x3090 with mtp4 were pushing ~75 coding on the same flash next earlier
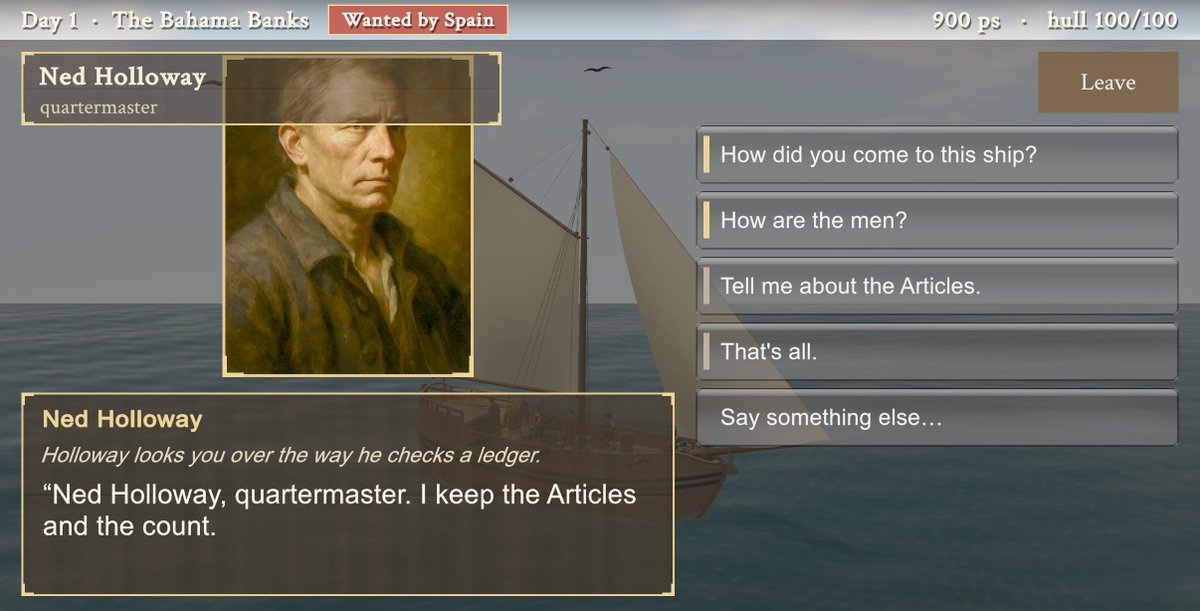
day 1 in tortuga, signed on 5 hands for 45 pieces of eight and the crew screen already has them racing for the sloop. maribel's out front at 18, holloway sitting at 14
@Oluwaphilemon1 130 on full bf16 for free is kind of rude, same 27b on a single dgx spark was getting ~40 overall with nvfp4 and a dflash2 drafter earlier tonight
@0xSero same flash next on a 96gb rtx pro 6000 was doing 83-87 tok/s without mtp an hour ago, 24 with 50gb living on nvme is a lot closer than it has any right to be
@gakonst same lesson one layer down in llama.cpp today, two strix halos splitting every layer over thunderbolt actually wrote slower than the old split, 11.4 vs 14.8 tok/s, the cable ate the gain