I reverse engineer things, find vulnerabilities and write FOSS under pseudonyms.
Local LLM entusiast, I do experiments with the RTX 6000 Pro, CMP HX170, M5 Max
@AndriusStepona1@sfxnz Yeah, speculative decode should be tested on real stuff, like a real coding repo or so...
BTW, a M5 Max with 3x Thunderbolt 5 M.2 with fast Gen4 x4 NVMEs can go from ~14gbps to ~30/35gbps if you tune streaming properly with 4x replicas 👀
@itsjustmarky Very nice!
I'm going with EPYC + TURIND8X-2T/500W
1x RTX 6000 Pro WS
4x CMP 170HX 64GB
I'll squeeze them inside a WS case with limited Watt (260W for the CPU, 325W for the 6000, 160W for the 170HX)
Buying more 6000 Pro at this price it's not worth it IMHO, I'd rather CMP-MAX
@ashxhart -for disk offload -> ability to use different disks (with replicas of the model) to stream faster (like a fake raid) [required proper cpu/thread/ram management as well since the type of op could be sync, async, batched, etc, needs proper scheduling]
-some auto-sweep ->best config
@ashxhart -knob to choose how much ram to use, how much for experts/layers to be streamed, how much for engrams
-fast ssd offload (FreeToken style) with several backend depending on the action (e.g. mixing io_uring, odirect, pread, mmap, depending if it's model load, expert stream, engram)
@ashxhart Local Deepseek V4.1 Flash is amazing for cyber-sec work, even better than GLM-5.3 Flash.
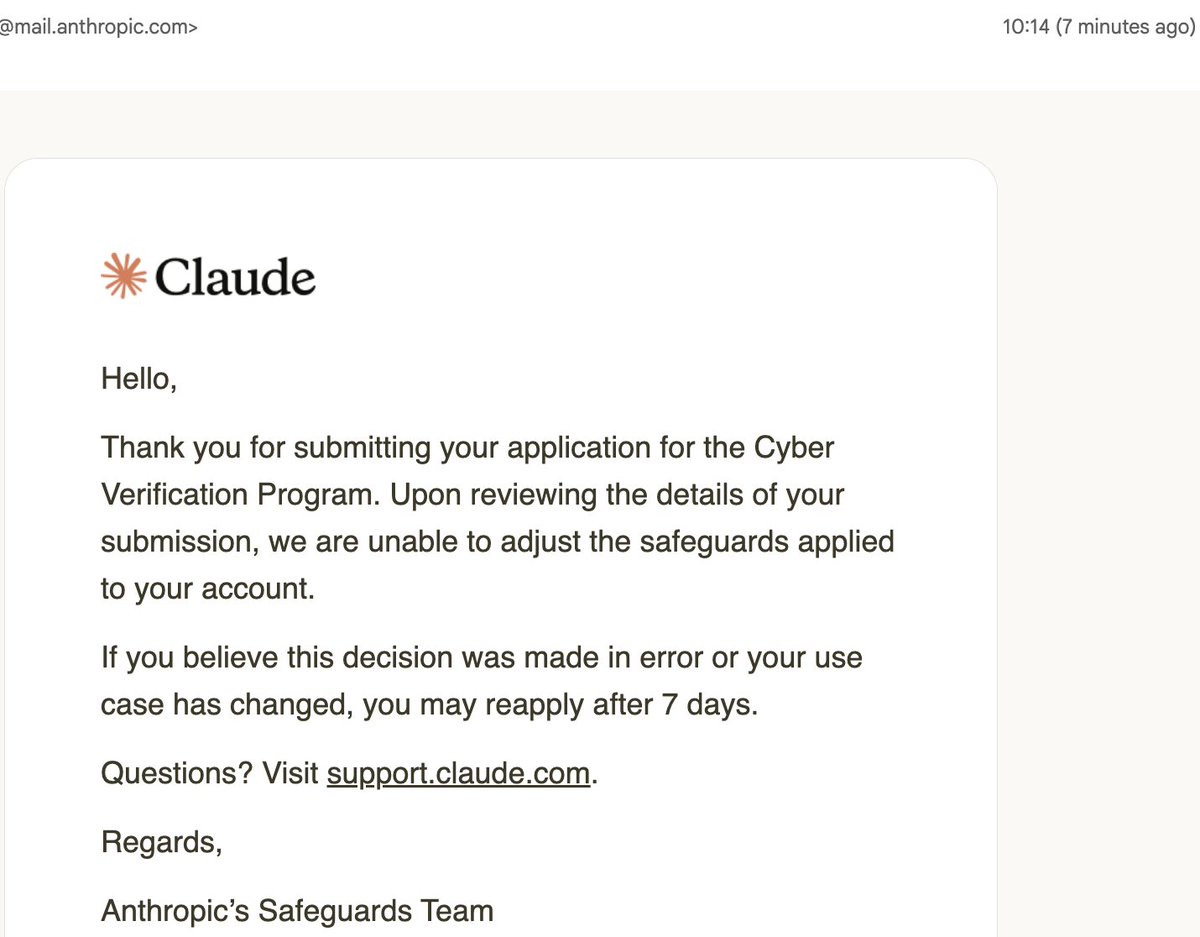
Meanwhile Anthropics does this (I have Apple CVEs and cyber-sec is all I do, so...)