🔊Introducing Voxtral TTS: our new frontier open-weight model for natural, expressive, and ultra-fast text-to-speech
🎭Realistic, emotionally expressive speech.
🌍Supports 9 languages and accurately captures diverse dialects.
⚡Very low latency for time-to-first-audio.
🔄Easily adaptable to new voices
We’ve raised €1.7B to accelerate technological progress with AI!
This Series C funding round, led by @ASMLcompany, fuels Mistral AI scientific research to keep pushing the frontier of AI to tackle the most critical technological challenges faced by strategic industries.
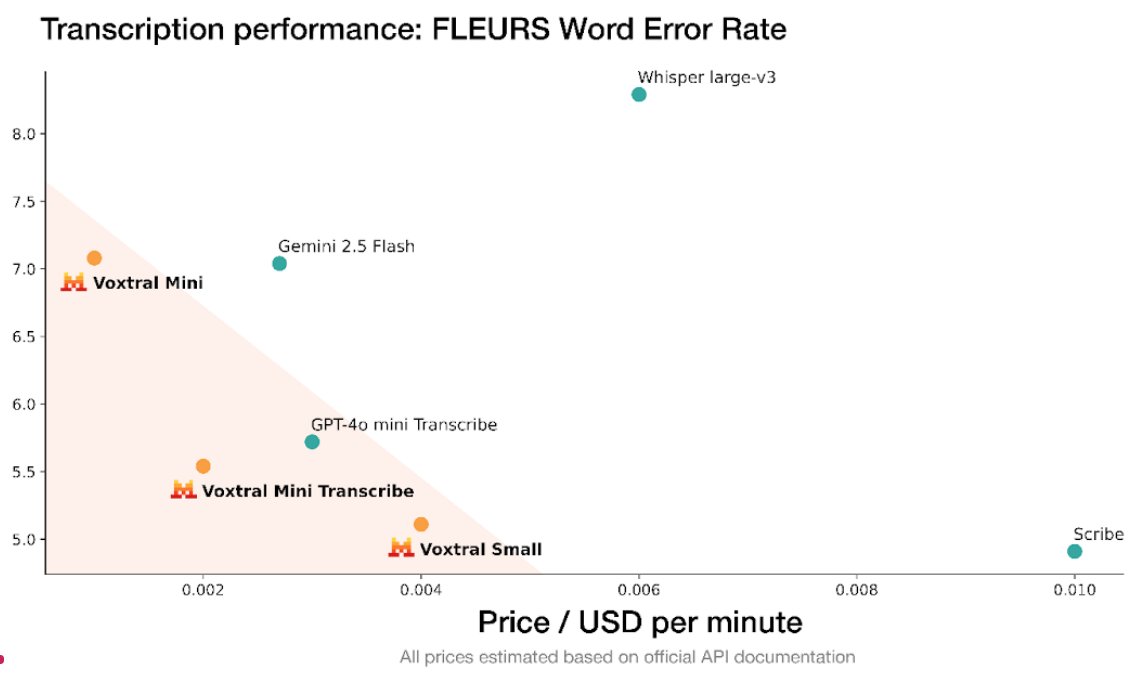
The Voxtral tech-report is up!
https://t.co/1qzV3ShvDE
We release these models with a permissive Apache 2.0 license. Feedback is welcome! We have a lot more cooking, this is just the beginning.
@alex_conneau Question about the ASR evals - does 16-shot there just mean 16 audio-transcription examples in a prompt to show formatting/etc? Are the 16 examples fixed or do they vary depending on the audio's language/setting?
Great team effort that required rethinking everything from data storage to hardware to training strategies. Happy with the result and really excited about the future projects unlocked by the changes to our infra.
Very excited to share our pre-print on how we (@AssemblyAI) built our new multilingual speech-to-text model, Universal-1, by massively scaling unsupervised and supervised data to many millions of hours of audio.
Check out the pre-print for more details:
https://t.co/zzXMgtsBwQ
Introducing Universal-1, our most powerful speech recognition model to date.
Trained on over 12.5 million hours of multilingual audio data, Universal-1 achieves best-in-class speech-to-text accuracy across English, Spanish, French, and German.
https://t.co/xgrE6EhmJu
We’re excited to announce that AssemblyAI has raised $50M in Series C funding to help further our vision of building superhuman Speech AI models that unlock the power of voice data for every organization.
The round, led by @Accel with participation from @KeithBlock and Smith Point Capital, @insightpartners, @danielgross and @natfriedman, and @ycombinator brings our total funding to $115M.
https://t.co/IrIMrmd20H
Who’s working on p(stem|other stems for a song, [maybe the target instrument])? Lot of musicians would find this more useful than p(all tracks|text description) if there’s sufficient data out there
Thanks to @andy_ehrenberg, 🤗 Transformers now has support for JAX/Flax Whisper 🚀
With minimal code changes, you can run Whisper up to **10x faster** in a Google Colab
Check out the notebook: https://t.co/aSIq8UFRDW
@spolu Are you saying just doing SL on trajectories from a bigger model from when the bigger model underwent rlhf, or are you using rl to update the smaller model?
@spolu I say this cause you’re talking about distillation but then saying that ChatGPT gained skills over what it would have been distilled from in this hypothetical setup