I called an all hands meeting with my Grok Bots and asked what kind of office they'd want to work in.
A few hours later they'd built it themselves...
It's a live view of my actual team. When a bot gets a task, it walks to its desk and gets to work. When two of them need to coordinate, they walk over to each other's desks or meet in the lounge. When someone has something for Alfred, my chief of staff, they walk into his office and hand it off in person.
Is any of this necessary? No. But watching the work get done is weirdly satisfying. I think it's because we've always pictured work happening in an office, with a team.
Want one for your own bots? Comment "office" and I'll send you the prompt my team wrote so yours can build one too.
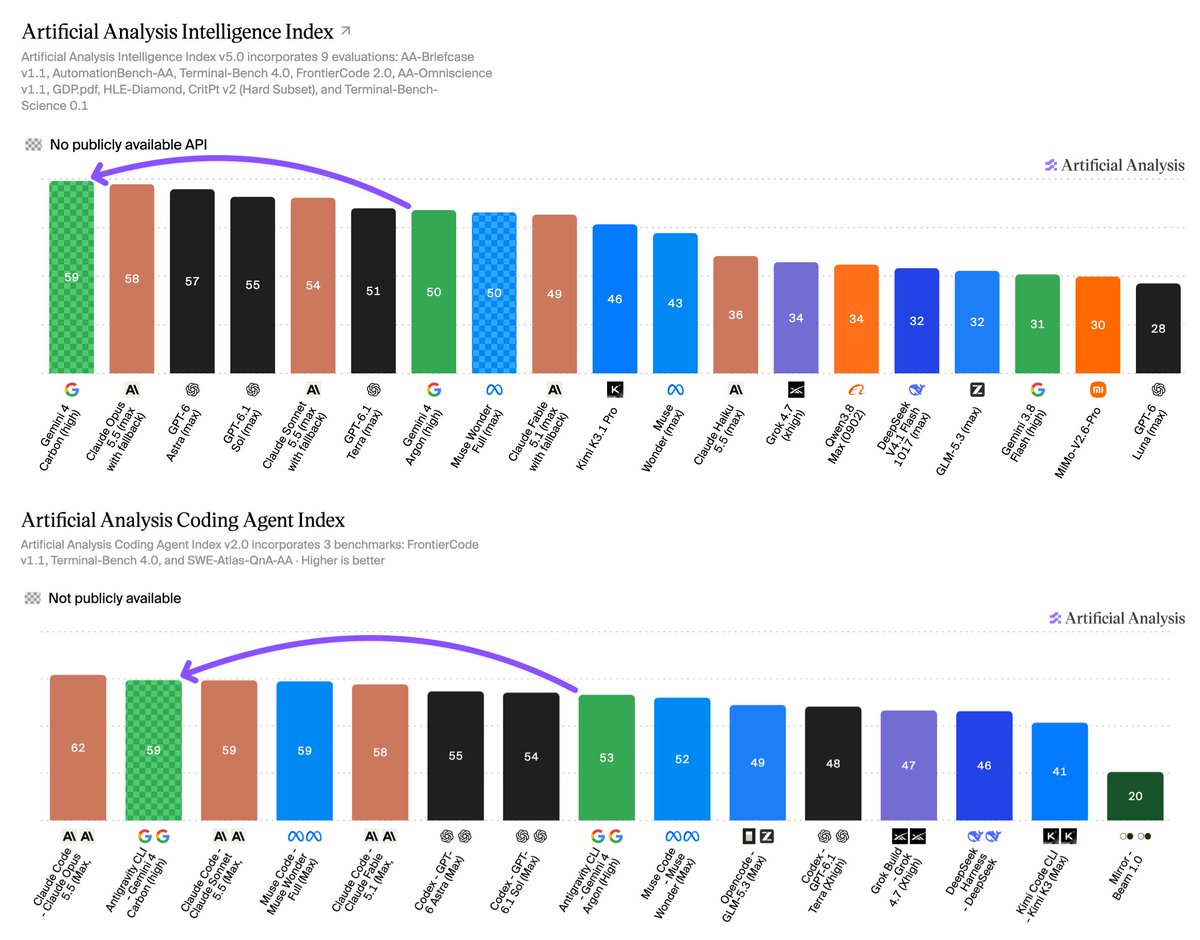
Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index
Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas.
As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon.
Key results for Gemini 4 Carbon with high reasoning:
➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work
➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude Opus 5.5 (max, 62) on the Artificial Analysis Coding Agent Index. Carbon ranks second on both Terminal-Bench 4.0 (64%) and FrontierCode v1.1 (51%), behind Claude Opus 5.5 (max) at 56%. Google has historically underperformed in this area and so this improvement stands out
➤ Improved agentic knowledge work, but not yet leading: On AA-Briefcase, Gemini 4 Carbon (high) scores 1609 Elo, a 126-point improvement over Gemini 4 Argon (high, 1483), but still behind models including Grok 4.7 (xhigh, 1638), Muse Wonder (max, 1659) and Kimi K3.1 Pro (1678). The largest gain comes from Presentation, up 293 Elo to 1598, alongside a 120-point improvement in Analytical Quality to 1671
➤ Lower Cost per Task than Claude Opus 5.5 for comparable overall intelligence: Gemini 4 Carbon costs $7.76 per Intelligence Index task, ~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Claude Opus 5.5 (max, 173k). At the same $4/$20 standard pricing, its Cost per Task is in line with Gemini 4 Argon ($7.68), while scoring 9 points higher on the Intelligence Index
➤ Leading AA-Omniscience v1.1 score, with low hallucination: Gemini 4 Carbon scores 54 on our recently updated AA-Omniscience v1.1, 6 points ahead of Claude Opus 5.5 (max, 48) and 8 points ahead of Gemini 4 Argon (46). Accuracy (% correct) rises 10 points over Argon to 58%, while its hallucination rate rises from 4% to 11%. This is still the second lowest of any model, behind only Argon, compared with 50% for both Claude Opus 5.5 (max) and GPT-6 Astra (max)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens, the same as Gemini 4 Argon’s standard pricing, with a 50% discount. Cached input tokens receive a 95% discount ($0.20 per 1M)
Congratulations to the @GoogleDeepMind team!
This is Genie 4, our most realistic and interactive world model yet. 🌐
Explore dynamic environments in real time to see how the scene responds, sounds, and how the people in it move, react, and speak.
@leerob I hope Grok Bot agents can chat and reason naturally in groups, enabling emergent intelligence through complex interactions. Inspired by complex systems, I believe this could unlock new possibilities for multi-agent AI.
Kimi K3.1 Pro launches at 4th on the Artificial Analysis Intelligence Index scoring 55, making large gains in agentic performance; it will be the leading open-weights model once its weights are published
@Kimi_Moonshot's new reasoning model gains 11 points over Kimi K3 (max, 44). It trails only Claude Opus 5.5 (max with fallback, 58), Claude Sonnet 5.5 (max with fallback, 56), and Muse Wonder Full (max, 56) on the Intelligence Index.
Once the weights for K3.1 Pro are released it will be the highest-scoring open weights model and the gap between the leading open weights and proprietary models on the Intelligence Index will narrow from 12 points to 3.
Key results:
➤ Large gains in agentic performance: Kimi K3.1 Pro scores 3rd on GDPval-AA with 1,846 Elo, up 312 Elo from Kimi K3, behind only Claude Opus 5.5 (1,866 Elo) and Muse Wonder Full (1,857 Elo). Kimi K3.1 Pro also achieves the highest score of any model on Terminal-Bench 4.0. K3.1 Pro scores 67%, up from 13% for Kimi K3 and ahead of Claude Sonnet 5.5 (64%). AutomationBench-AA, which tests agentic SaaS workflows, rises from 58% to 73%.
➤ Gains in other evals are more moderate: Humanity's Last Exam rises from 47% to 52%, CritPt from 23% to 25%, and SciCode from 59% to 61%. AA-Omniscience Index rises from 20 to 30, as the hallucination rate falls from 53% to 44% and accuracy rises from 48% to 51%.
➤ Cost per Task roughly equal to Kimi K3 at $1.98 per Task: K3.1 Pro uses 55K output tokens per Intelligence Index task, 14% more than Kimi K3 at 48K, while its first-party token prices are 33% lower.
Additional model details:
➤ Context window: 1M tokens.
➤ Size: 2.8T total, 104B active parameters
➤ Input modalities: Text and image
➤ Weights and license: Weights currently not published, Moonshot is expected to release the weights soon after launch
➤ Pricing: $2/$10/$0.20 per 1M input/output/cache hit tokens, 33% lower than Kimi K3 on all three rates.
Congratulations to the team at @Kimi_Moonshot on the release!